
Engineering teams frequently reach a fork in the road when building information retrieval systems: should they deploy standalone semantic search or implement a full Retrieval-Augmented Generation (RAG) pipeline? The confusion often stems from treating these as competing technologies rather than hierarchical components of a single intelligence stack.
In production environments, the distinction is not about picking one over the other but understanding where your system needs to stop. If your users require raw document discovery, semantic search is the end state. If they require synthesis, reasoning, or summarization, semantic search becomes the foundation upon which you build your RAG architecture.
The Core Mechanics: Semantic Search Vs Rag Foundations
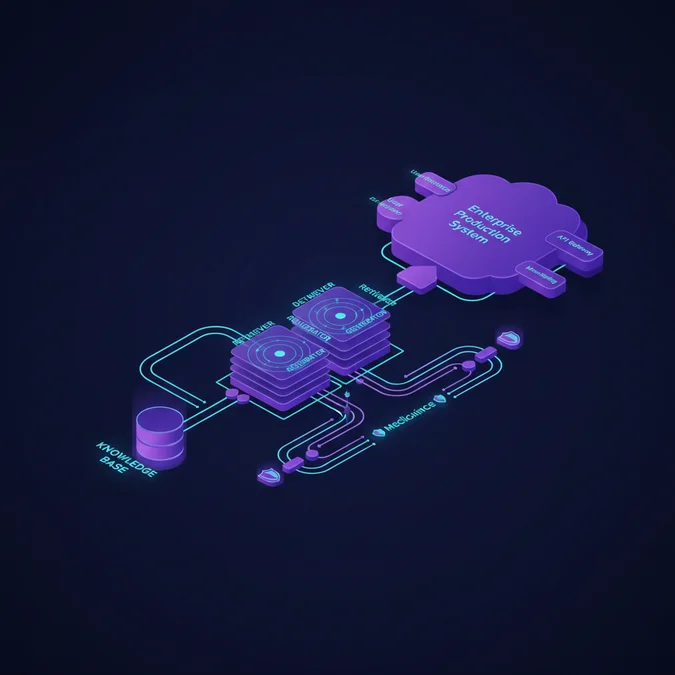
When evaluating semantic search vs rag, it is critical to recognize that RAG is a superset architecture. Semantic search provides the retrieval engine, while RAG adds the generative synthesis layer. Think of semantic search as the “eyes” of your application, capable of finding relevant data points in a high-dimensional vector space, and RAG as the “brain” that interprets those data points to answer complex questions.
Engineering Note: A RAG pipeline without a robust semantic search implementation is effectively blind. The quality of your generative output is strictly bounded by the precision and recall of your underlying retrieval mechanism.
Runtime Mechanics: Why RAG And Semantic Search Intersect
The retrieval phase of a RAG pipeline is, by definition, a semantic search operation. When a user submits a query, the system converts that query into an embedding vector and performs a k-nearest neighbor (k-NN) search across an index. The resulting documents serve as the context window for the LLM.
| Phase | Semantic Search | RAG Pipeline |
|---|---|---|
| Query Transformation | Embedding Only | Embedding + Prompt Engineering |
| Retrieval | Vector Similarity | Vector Similarity + Reranking |
| Generation | None | Contextual Synthesis |
Performance Benchmarks: Latency, Cost, And Accuracy
Production systems require strict adherence to latency budgets. Adding a generative model to your retrieval loop introduces significant compute overhead and token costs. The table below illustrates the performance trade-offs inherent in these architectures.
| Metric | Semantic Search | RAG Pipeline |
|---|---|---|
| Latency (ms) | 20 – 100ms | 500ms – 3000ms |
| Cost | Low (Index Query) | High (LLM Inference) |
| Accuracy | Top-k Precision | Synthesis Quality |
Engineering Implementation: Minimal Pipelines In Python
The following Python implementation demonstrates the delta in complexity. A semantic search implementation is a single-step process, whereas RAG involves managing context injection and model inference.
# Standalone Semantic Search
def search_only(query, vector_db):
 query_vec = embed(query)
 return vector_db.query(query_vec, top_k=5)

# RAG Pipeline Implementation
def rag_pipeline(query, vector_db, llm):
 docs = search_only(query, vector_db)
 context = "\n".join([d.text for d in docs])
 prompt = f"Context: {context}\n\nQuestion: {query}"
 return llm.generate(prompt)
Production Decision Matrix: Choosing The Right Framework
Deciding between these two depends on your end-user requirements. Use this checklist to validate your architectural choice.
- Use Semantic Search if: Your primary goal is document discovery, filtering, or finding exact matches in a large corpus.
- Use RAG if: You need to synthesize information, answer complex questions, or maintain a conversational interface.
- Mitigate Hallucinations: Always verify the retrieval quality before passing context to the LLM to prevent false generation.
Frequently Asked Questions
Is semantic search vs rag a choice of one or the other?
It is not a binary choice. Semantic search is a fundamental retrieval component used within a RAG pipeline. You use semantic search to find relevant documents, and then RAG uses those documents as context for a Large Language Model to generate an answer.
What is the primary difference between rag and semantic search?
Semantic search focuses purely on finding relevant content based on vector similarity. RAG builds upon this by taking that retrieved information and passing it into a generative model to synthesize a natural language response, effectively adding a synthesis layer to the retrieval process.
The choice between semantic search and RAG is rarely about choosing one over the other; it is about defining the scope of the intelligence you wish to provide. By treating semantic search as your high-performance retrieval foundation, you can scale your system from simple document lookup to complex, generative reasoning with minimal friction.
Evaluate your latency requirements and user personas today to determine if your current retrieval infrastructure is ready for the overhead of a generative synthesis layer.