
Retrieval augmented generation for large language models a survey represents the critical intersection between static model weights and dynamic, domain-specific knowledge bases. As of 2026, the industry has shifted from simple semantic search implementations toward complex, multi-hop reasoning agents that require precise architectural orchestration.
This analysis bypasses theoretical abstraction to address the engineering friction points encountered when deploying RAG at scale. We examine the transition from naive retrieval to adaptive, self-correcting pipelines, providing a technical baseline for architects tasked with reducing hallucination rates while managing operational costs in high-throughput environments.
Taxonomy of Retrieval Augmented Generation For Large Language Models A Survey
Categorizing the landscape of retrieval augmented generation for large language models a survey requires a multi-dimensional approach. We classify systems based on their retrieval depth, the complexity of the augmentation layer, and the synthesis strategy employed by the LLM.
| Category | Retrieval Strategy | Latency Profile | Use Case |
|---|---|---|---|
| Naive RAG | Dense Vector Search | Low (50-200ms) | Internal Q&A |
| Advanced RAG | Hybrid + Re-ranking | Medium (300-800ms) | Technical Support |
| Agentic RAG | Iterative Reasoning | High (>1000ms) | Complex Analytics |
Understanding these tiers is essential for selecting the appropriate infrastructure. As the architecture evolves, the trade-off between retrieval precision and inference cost becomes the primary driver of system design.
Synthesizing Findings from the Latest Rag Survey
The latest industry literature, as consolidated in every comprehensive rag survey, indicates that the bottleneck has shifted from retrieval accuracy to context window management and token efficiency. Architectural designs that prioritize modular re-ranking over brute-force retrieval are now the gold standard for enterprise deployments.
Key findings highlight that embedding models are increasingly domain-specific. Engineering teams are moving away from general-purpose models toward fine-tuned, task-specific embedding spaces to reduce noise in the augmentation phase.
Core Mechanics and Pipeline Implementation
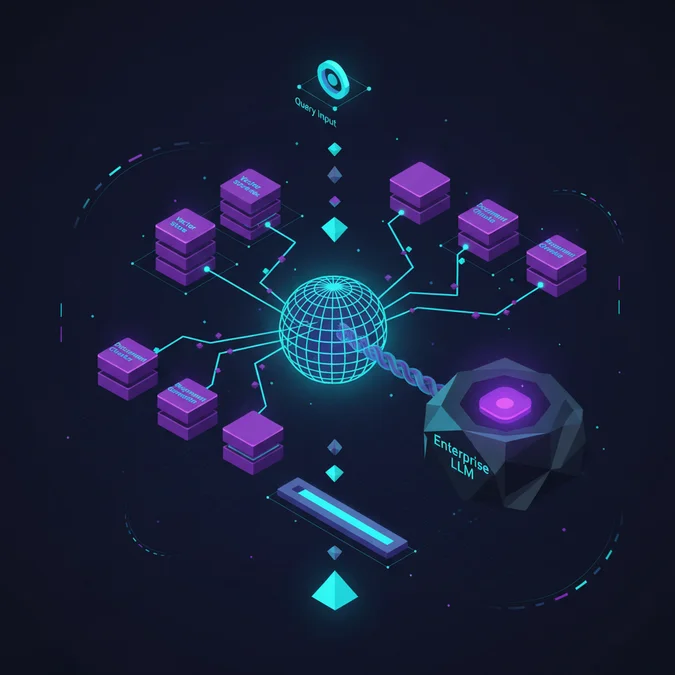
A robust RAG pipeline executes a sequence of operations designed to maximize signal-to-noise ratio before the context is injected into the model. The following implementation demonstrates a standard retrieval-augmentation flow.
- Query Transformation: Normalize user input using a lightweight model.
- Vector Retrieval: Fetch candidate chunks from the vector store.
- Re-ranking: Apply a cross-encoder to refine top-k results.
- Context Injection: Format the prompt with retrieved metadata.
import openai
from qdrant_client import QdrantClient

def retrieve_and_generate(query, client: QdrantClient):
 # Vector search implementation
 results = client.search(collection_name="docs", query_vector=encode(query), limit=5)

 # Re-ranking logic
 ranked_results = cross_encoder.rank(query, [r.payload for r in results])

 # Prompt construction
 prompt = f"Context: {ranked_results[0].text}\n\nQuestion: {query}"
 return openai.ChatCompletion.create(model="gpt-4o", messages=[{"role": "user", "content": prompt}])
Production Readiness and System Evaluation
Transitioning to production requires moving beyond functional correctness to operational observability and reliability. Use this checklist to validate your RAG system maturity.
- [ ] Observability: Implement tracing for every retrieval step to identify latency bottlenecks.
- [ ] Guardrails: Introduce PII redaction and fact-check verification loops.
- [ ] Caching: Deploy semantic caching to reduce API costs for redundant queries.
- [ ] Evaluation: Automate RAGAS metrics to track faithfulness and answer relevance over time.
- [ ] Throughput: Load test the vector database to ensure p99 latency remains within SLAs under peak load.
Frequently Asked Questions
What is the primary purpose of a retrieval augmented generation for large language models a survey document?
This survey provides a structured review of architectural patterns, retrieval mechanisms, and generation strategies. It serves as a foundational reference for engineers to understand how external data integration improves LLM accuracy, reduces hallucinations, and optimizes knowledge retrieval in production-grade AI systems.
How does a rag survey assist in choosing vector databases?
A rag survey categorizes vector database performance based on latency, indexing algorithms, and scalability. It provides comparative benchmarks that help developers align specific storage solutions with their latency requirements, data volume, and metadata filtering needs in complex production pipelines.
Engineering a high-performance RAG system requires balancing retrieval precision with inference latency. By focusing on modular components and rigorous evaluation, teams can effectively mitigate the inherent limitations of LLMs.
The path to production involves constant iteration on the retrieval layer and strict adherence to observability standards. Aligning your architecture with the patterns discussed ensures long-term system maintainability and performance.