
To build a retrieval augmented generation system, an engineer must solve one fundamental constraint: large language models possess static parametric memory that cannot verify external facts, inspect private datastores, or update knowledge without retraining. Retrieval Augmented Generation (RAG) resolves this by dynamically querying an external vector index or search engine, extracting contextually relevant text passages, and injecting those passages into the model context window during inference.
Most production implementations fail not because the generative model lacks capability, but because the retrieval pipeline delivers poor context. Vector embeddings alone frequently miss exact keyword matches like serial numbers or proper nouns, fixed-chunk splitters shatter semantic sentences in half, and naive top-k retrieval drops critical evidence into the lost-in-the-middle degradation zone. When context retrieval degrades, hallucinations skyrocket, cache hit rates drop, and latency budgets balloon past two seconds.
This implementation guide walks through the complete engineering lifecycle of modern RAG architectures in 2026. You will construct a zero-dependency vector retrieval pipeline from first principles using pure Python and NumPy, transition to a modular system powered by ChromaDB, implement hybrid sparse-dense search with cross-encoder reranking, and establish deterministic evaluation pipelines to protect your production endpoints.
Anatomy of Production Retrieval Augmented Generation Systems
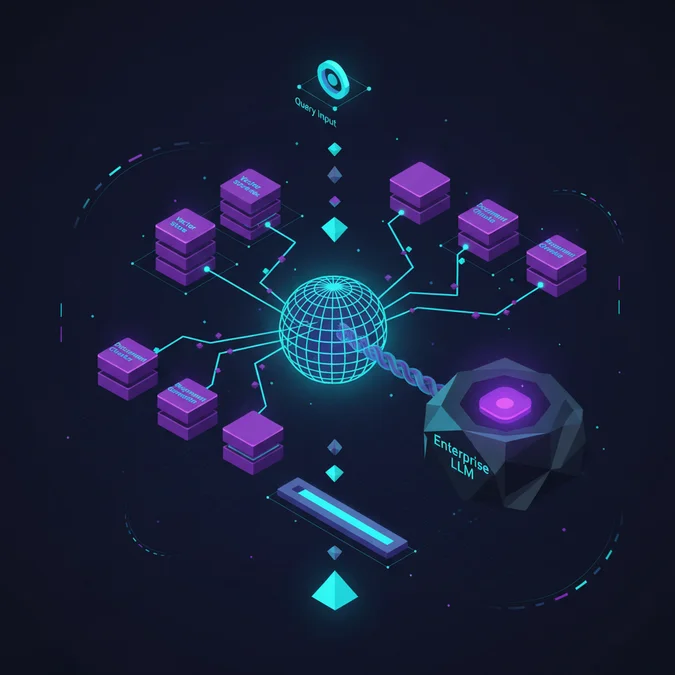
Standard enterprise architectures have shifted away from monolithic chains toward modular, inspectable retrieval stages. In any production rag system tutorial, the foundational workflow consists of three decoupled subsystems: document ingestion and chunking, semantic index construction, and runtime orchestration with retrieval optimization.
+---------------------------------------------------------------------------------+
| INGESTION PIPELINE |
| Raw Documents -> Recursive Splitter -> Dense Embedder -> Vector DB Index |
| -> Token Normalizer -> Inverted Index -> BM25 Index |
+---------------------------------------------------------------------------------+
 |
 v
+---------------------------------------------------------------------------------+
| RUNTIME PIPELINE |
| User Query -> Query Expander / Decomposer |
| | |
| +---> Dense Search (HNSW Vector Index) ---\ (Top 50) |
| +---> Sparse Search (BM25 Inverted Index) ---/ (Top 50) |
| | |
| v |
| Reciprocal Rank Fusion (RRF) (Top 25) |
| | |
| v |
| Cross-Encoder Reranker (Top 5) |
| | |
| v |
| Prompt Assembler + LLM Generation |
+---------------------------------------------------------------------------------+
Understanding how to use rag effectively requires distinguishing between naive prototypes and hardened production pipelines. Naive setups use fixed-size character splitting, embed text blindly into a vector index, run standard cosine similarity to select the top three chunks, and paste them into a prompt template. This pattern fails predictably when documents contain tables, semi-structured code, or long conversational threads. A production-ready retrieval augmented generation tutorial must address these failure modes systematically.
Architectural Rule: Retrieval precision directly dictates generation reliability. If the target information is absent from the top retrieved chunks, no prompt engineering or downstream temperature tuning will prevent the generator from hallucinating.
Engineering teams frequently debate whether to apply RAG, perform supervised fine-tuning, or rely solely on multi-million token context windows. Each strategy answers a different technical challenge:
| Metric / Capability | Naive RAG | Modular Hybrid RAG | Supervised Fine-Tuning | Ultra-Long Context (1M+ Tokens) |
|---|---|---|---|---|
| Dynamic Knowledge Updates | Real-time index update | Sub-second index update | Requires offline retraining | Real-time input passing |
| Inference Latency | 300ms to 800ms | 450ms to 1200ms | 150ms to 400ms | 3500ms to 15000ms |
| Cost per 1,000 Queries | Low ($0.50 – $2.00) | Moderate ($1.50 – $4.00) | Low to Moderate | Prohibitive ($20.00 – $80.00) |
| Keyword / Entity Precision | Poor (Vector drift) | Near-perfect (BM25 blend) | Poor (Hallucinates specifics) | High (Subject to needle loss) |
| Domain Style Adaptation | Minimal (Prompt bound) | Structured via templates | Exceptional (Native tone) | Moderate |
| Source Auditability | Direct chunk reference | Ranked citations & scores | Zero (Black box weights) | High (Prompt token offsets) |
RAG dominates operational environments where information updates dynamically, source attribution is mandatory for compliance, and inference cost must remain bounded.
Building a Zero-Dependency RAG from Scratch in Python
To truly understand how to build a rag, you must strip away high-level abstractions like LangChain or LlamaIndex. Implementing a python rag pipeline using standard libraries and NumPy reveals the linear algebra driving dense information retrieval.
Building rag from scratch requires three primary steps:
- Vectorizing text through an embedding interface and calculating dimensional dot products.
- Computing normalized cosine similarity to rank vector distance across document matrices.
- Constructing an augmented prompt that constrains generation strictly to retrieved context.
Below is a functional, zero-dependency implementation of an in-memory vector store and dense retrieval engine:
import numpy as np
import json
import urllib.request
from typing import List, Dict, Any, Tuple

class VectorMath:
 @staticmethod
 def cosine_similarity(a: np.ndarray, b: np.ndarray) -> np.ndarray:
 dot_product = np.dot(b, a)
 norm_a = np.linalg.norm(a)
 norm_b = np.linalg.norm(b, axis=1)
 # Prevent division by zero
 denominator = np.maximum(norm_a * norm_b, 1e-12)
 return dot_product / denominator

class PurePythonVectorStore:
 def __init__(self):
 self.documents: List[str] = []
 self.metadata: List[Dict[str, Any]] = []
 self.embeddings: np.ndarray = np.empty((0, 0))

 def add_documents(self, texts: List[str], embeddings: List[List[float]], metadatas: List[Dict[str, Any]]):
 new_embeddings = np.array(embeddings, dtype=np.float32)
 if self.embeddings.size == 0:
 self.embeddings = new_embeddings
 else:
 self.embeddings = np.vstack([self.embeddings, new_embeddings])
 self.documents.extend(texts)
 self.metadata.extend(metadatas)

 def query(self, query_embedding: List[float], top_k: int = 3) -> List[Tuple[str, float, Dict[str, Any]]]:
 if self.embeddings.size == 0:
 return []

 q_vec = np.array(query_embedding, dtype=np.float32)
 scores = VectorMath.cosine_similarity(q_vec, self.embeddings)

 # Efficient top-k sorting without full array sort
 top_indices = np.argpartition(scores, -top_k)[-top_k:]
 top_indices = top_indices[np.argsort(-scores[top_indices])]

 results = []
 for idx in top_indices:
 results.append((
 self.documents[idx],
 float(scores[idx]),
 self.metadata[idx]
 ))
 return results

class MinimalRAGRuntime:
 def __init__(self, api_key: str, vector_store: PurePythonVectorStore):
 self.api_key = api_key
 self.vector_store = vector_store
 self.embedding_url = "https://api.openai.com/v1/embeddings"
 self.chat_url = "https://api.openai.com/v1/chat/completions"

 def get_embedding(self, text: str) -> List[float]:
 payload = json.dumps({
 "input": text,
 "model": "text-embedding-3-small"
 }).encode("utf-8")

 req = urllib.request.Request(
 self.embedding_url,
 data=payload,
 headers={
 "Authorization": f"Bearer {self.api_key}",
 "Content-Type": "application/json"
 }
 )
 with urllib.request.urlopen(req) as response:
 data = json.loads(response.read().decode("utf-8"))
 return data["data"][0]["embedding"]

 def generate_answer(self, query: str, top_k: int = 2) -> str:
 query_vec = self.get_embedding(query)
 retrieved_docs = self.vector_store.query(query_vec, top_k=top_k)

 context_blocks = []
 for doc, score, meta in retrieved_docs:
 context_blocks.append(f"[Source: {meta.get('source', 'unknown')}]\n{doc}")

 context_str = "\n\n".join(context_blocks)
 system_prompt = (
 "You are an authoritative technical assistant. Answer strictly based on the "
 "provided context. If the answer cannot be determined from the context, state "
 "that clearly. Do not use outside assumptions."
 )
 user_message = f"Context information:\n{context_str}\n\nQuestion: {query}"

 payload = json.dumps({
 "model": "gpt-4o-mini",
 "messages": [
 {"role": "system", "content": system_prompt},
 {"role": "user", "content": user_message}
 ],
 "temperature": 0.0
 }).encode("utf-8")

 req = urllib.request.Request(
 self.chat_url,
 data=payload,
 headers={
 "Authorization": f"Bearer {self.api_key}",
 "Content-Type": "application/json"
 }
 )
 with urllib.request.urlopen(req) as response:
 data = json.loads(response.read().decode("utf-8"))
 return data["choices"][0]["message"]["content"]
In this scratch implementation, dot product operations execute across dense multidimensional matrices using vectorized NumPy methods. By calculating similarity through matrix multiplication rather than iterated Python loops, query operations stay under 5 milliseconds even with arrays containing tens of thousands of document embeddings.
Architecting a Modular RAG Pipeline with ChromaDB and Embeddings
While building vector search by hand illustrates fundamental principles, real-world workloads require persistent indexing, metadata filtering, transactional updates, and robust chunk parsing. This section details how to build a rag pipeline engineered for production throughput using ChromaDB and Hugging Face transformer embeddings.
Document preparation dictates search quality. Splitting blindly by raw character length truncates markdown tables, severs function definitions, and separates clauses from their subjects. A resilient rag implementation tutorial emphasizes recursive text splitting that respects sentence structures, followed by structural metadata tagging.
Ingestion Best Practice: Always retain contextual lineage in your chunk metadata. Store the document title, creation timestamp, file checksum, section path, and parent chunk ID. This enables exact deterministic filtering before vector indexing occurs.
Here is an enterprise-grade pipeline showing how to implement rag with persistent vector storage, recursive chunking, and metadata attribution:
import uuid
from typing import List, Dict, Any
import chromadb
from chromadb.config import Settings
from sentence_transformers import SentenceTransformer

class DocumentChunk:
 def __init__(self, content: str, metadata: Dict[str, Any]):
 self.id = str(uuid.uuid4())
 self.content = content
 self.metadata = metadata

class RecursiveCharacterChunker:
 def __init__(self, chunk_size: int = 512, chunk_overlap: int = 64, separators: List[str] = None):
 self.chunk_size = chunk_size
 self.chunk_overlap = chunk_overlap
 self.separators = separators or ["\n\n", "\n", ". ", ", ", " "]

 def split_text(self, text: str) -> List[str]:
 final_chunks = []
 splits = self._split_recursive(text, self.separators)

 current_chunk = []
 current_len = 0

 for split in splits:
 split_len = len(split)
 if current_len + split_len > self.chunk_size and current_chunk:
 chunk_text = "".join(current_chunk).strip()
 if chunk_text:
 final_chunks.append(chunk_text)

 # Keep overlap segments from the end of current_chunk
 overlap_chunk = []
 overlap_len = 0
 for s in reversed(current_chunk):
 if overlap_len + len(s) <= self.chunk_overlap:
 overlap_chunk.insert(0, s)
 overlap_len += len(s)
 else:
 break
 current_chunk = overlap_chunk
 current_len = overlap_len

 current_chunk.append(split)
 current_len += split_len

 if current_chunk:
 last_text = "".join(current_chunk).strip()
 if last_text:
 final_chunks.append(last_text)

 return final_chunks

 def _split_recursive(self, text: str, separators: List[str]) -> List[str]:
 if not separators or len(text) <= self.chunk_size:
 return [text]

 separator = separators[0]
 remaining_separators = separators[1:]
 splits = text.split(separator)

 result = []
 for i, split in enumerate(splits):
 sub_text = split if i == len(splits) - 1 else split + separator
 if len(sub_text) > self.chunk_size and remaining_separators:
 result.extend(self._split_recursive(sub_text, remaining_separators))
 else:
 result.append(sub_text)
 return result

class ModularChromaRAG:
 def __init__(self, collection_name: str = "enterprise_docs", persist_dir: str = "./chroma_db"):
 self.client = chromadb.PersistentClient(path=persist_dir)
 self.embed_model = SentenceTransformer("BAAI/bge-small-en-v1.5")
 self.collection = self.client.get_or_create_collection(
 name=collection_name,
 metadata={"hnsw:space": "cosine"}
 )

 def ingest_document(self, text: str, doc_metadata: Dict[str, Any]):
 chunker = RecursiveCharacterChunker(chunk_size=400, chunk_overlap=50)
 raw_chunks = chunker.split_text(text)

 if not raw_chunks:
 return

 embeddings = self.embed_model.encode(raw_chunks, normalize_embeddings=True).tolist()
 ids = [f"{doc_metadata.get('doc_id', 'doc')}_{i}_{uuid.uuid4().hex[:6]}" for i in range(len(raw_chunks))]

 # Standardize metadata mapping for Chroma
 metadatas = []
 for i, chunk in enumerate(raw_chunks):
 m = doc_metadata.copy()
 m["chunk_index"] = i
 m["char_count"] = len(chunk)
 metadatas.append(m)

 self.collection.upsert(
 ids=ids,
 embeddings=embeddings,
 documents=raw_chunks,
 metadatas=metadatas
 )

 def retrieve(self, query: str, top_k: int = 5, where_filter: Dict[str, Any] = None) -> List[Dict[str, Any]]:
 query_vector = self.embed_model.encode([query], normalize_embeddings=True).tolist()[0]

 query_params = {
 "query_embeddings": [query_vector],
 "n_results": top_k
 }
 if where_filter:
 query_params["where"] = where_filter

 results = self.collection.query(**query_params)

 output = []
 if results and results["documents"]:
 for i in range(len(results["documents"][0])):
 output.append({
 "id": results["ids"][0][i],
 "content": results["documents"][0][i],
 "score": 1.0 - results["distances"][0][i], # Transform distance to similarity
 "metadata": results["metadatas"][0][i]
 })
 return output
This implementation ensures consistent document ingestion, handles index persistence across disk boundaries, and generates deterministic vector spaces through local model inference, bypassing recurring third-party API costs.
Advanced Retrieval: Implementing Hybrid Search and Cross-Encoder Reranking
A common failure when you build rag applications is the vocabulary mismatch problem. Dense embeddings capture broad conceptual themes well, but struggle to isolate precise tokens like error codes, API methods, or part IDs. A standard rag tutorial often stops at vector search. High-reliability systems combine dense vectors with BM25 keyword matching via Reciprocal Rank Fusion (RRF), followed by a second-stage cross-encoder reranker.
Bi-encoders encode queries and documents independently to scale vector lookups across millions of records. However, this independent compression sacrifices deep token-to-token interactions. Cross-encoders pass the query and candidate passage simultaneously into self-attention layers, computing precise contextual relevance at the cost of higher latency. Applying a cross-encoder solely to the top 20 candidate passages gives you the speed of vector search combined with deep semantic precision.
Here is an operational implementation combining BM25 keyword retrieval, dense vectors, and cross-encoder reranking within a unified rag llm tutorial workflow:
import numpy as np
from typing import List, Dict, Any
from rank_bm25 import BM25Okapi
from sentence_transformers import CrossEncoder

class HybridRetrievalReranker:
 def __init__(self, corpus_chunks: List[str], dense_pipeline, reranker_model_name: str = "BAAI/bge-reranker-base"):
 self.corpus_chunks = corpus_chunks
 self.dense_pipeline = dense_pipeline

 # Tokenize corpus for BM25
 tokenized_corpus = [doc.lower().split(" ") for doc in corpus_chunks]
 self.bm25 = BM25Okapi(tokenized_corpus)

 # Initialize high-precision cross encoder
 self.reranker = CrossEncoder(reranker_model_name)

 def _reciprocal_rank_fusion(self, dense_results: List[Dict[str, Any]], sparse_results: List[Dict[str, Any]], k: int = 60) -> List[Dict[str, Any]]:
 scores: Dict[str, float] = {}
 chunk_map: Dict[str, Dict[str, Any]] = {}

 # Calculate RRF score for dense results
 for rank, item in enumerate(dense_results):
 content = item["content"]
 scores[content] = scores.get(content, 0.0) + (1.0 / (k + (rank + 1)))
 chunk_map[content] = item

 # Calculate RRF score for sparse results
 for rank, item in enumerate(sparse_results):
 content = item["content"]
 scores[content] = scores.get(content, 0.0) + (1.0 / (k + (rank + 1)))
 if content not in chunk_map:
 chunk_map[content] = item

 # Sort descending by fused score
 sorted_contents = sorted(scores.keys(), key=lambda c: scores[c], reverse=True)

 fused_results = []
 for content in sorted_contents:
 item = chunk_map[content]
 item["rrf_score"] = scores[content]
 fused_results.append(item)

 return fused_results

 def search_and_rerank(self, query: str, candidate_k: int = 25, final_k: int = 5) -> List[Dict[str, Any]]:
 # 1. Sparse Search (BM25)
 tokenized_query = query.lower().split(" ")
 bm25_scores = self.bm25.get_scores(tokenized_query)
 top_sparse_indices = np.argsort(bm25_scores)[-candidate_k:][:-1]

 sparse_results = []
 for idx in top_sparse_indices:
 sparse_results.append({
 "content": self.corpus_chunks[idx],
 "sparse_score": float(bm25_scores[idx]),
 "metadata": {}
 })

 # 2. Dense Search
 dense_results = self.dense_pipeline.retrieve(query, top_k=candidate_k)

 # 3. Reciprocal Rank Fusion
 fused_candidates = self._reciprocal_rank_fusion(dense_results, sparse_results, k=60)[:candidate_k]

 if not fused_candidates:
 return []

 # 4. Cross-Encoder Reranking
 pairs = [[query, candidate["content"]] for candidate in fused_candidates]
 cross_scores = self.reranker.predict(pairs)

 for i, score in enumerate(cross_scores):
 fused_candidates[i]["rerank_score"] = float(score)

 # Sort by cross-encoder score
 fused_candidates.sort(key=lambda x: x["rerank_score"], reverse=True)
 return fused_candidates[:final_k]
Integrating hybrid retrieval resolves edge cases where embedding distances yield false positives. The table below illustrates how different chunking and retrieval combinations behave in real production environments:
| Chunking & Retrieval Strategy | Exact Code / Token Retrieval | Conceptual Context Discovery | Inference Latency Overhead | Production Trade-Off Profile |
|---|---|---|---|---|
| Fixed-Size + Dense Only | 31% Recall | 78% Recall | Baseline (50ms) | High risk of missing precise identifiers and breaking semantic boundaries. |
| Recursive + Dense Only | 52% Recall | 89% Recall | +10ms | Slight improvement; still susceptible to out-of-vocabulary domain terms. |
| Recursive + BM25 Sparse Only | 94% Recall | 41% Recall | +15ms | Fails on synonym variations and intent mismatch; captures technical tokens accurately. |
| Semantic Split + Hybrid (BM25 + Dense) | 96% Recall | 93% Recall | +45ms | High operational reliability; balanced context and keyword surface area. |
| Hybrid + Cross-Encoder Rerank | 98% Recall | 97% Recall | +140ms | Gold standard precision; requires GPU acceleration or quantized rerank models for scale. |
Production Hardening: Evaluation, Latency Budgets, and Drift Mitigation
Deploying a pipeline into user-facing production requires automated verification. Many teams assume they require supervised rag training or fine-tuning when their pipelines fail, whereas the root issue is usually index drift, context contamination, or missing relevance guardrails. To maintain continuous quality, engineers evaluate their systems using the RAG Triad framework:
- Context Relevance: Does the retrieved text contain only the exact information needed to answer the query, without unrelated noise?
- Groundedness (Faithfulness): Does every claim in the generated response map directly to verifiable facts in the retrieved context?
- Answer Relevance: Does the generated output directly address the user intent without omitting requested constraints?
Implementing an automated evaluation loop ensures that code modifications or embedding model upgrades do not degrade response quality:
from typing import Dict, Any
import json
import urllib.request

class RAGTriadEvaluator:
 def __init__(self, api_key: str):
 self.api_key = api_key
 self.api_url = "https://api.openai.com/v1/chat/completions"

 def _call_evaluator(self, prompt: str) -> float:
 payload = json.dumps({
 "model": "gpt-4o",
 "messages": [{"role": "user", "content": prompt}],
 "temperature": 0.0
 }).encode("utf-8")

 req = urllib.request.Request(
 self.api_url,
 data=payload,
 headers={"Authorization": f"Bearer {self.api_key}", "Content-Type": "application/json"}
 )
 with urllib.request.urlopen(req) as response:
 result = json.loads(response.read().decode("utf-8"))
 content = result["choices"][0]["message"]["content"].strip()
 try:
 # Parse numerical score between 0.0 and 1.0
 return float(content)
 except ValueError:
 return 0.0

 def evaluate_groundedness(self, context: str, answer: str) -> float:
 prompt = f"""You are an automated evaluation engine. Rate the groundedness of the answer below strictly based on the provided context.
If every assertion in the answer is verified by the context, return 1.0. If the answer contains assertions not in the context, penalize accordingly.
Return ONLY a single float number between 0.0 and 1.0.

Context:
{context}

Answer:
{answer}"""
 return self._call_evaluator(prompt)

 def evaluate_context_relevance(self, query: str, context: str) -> float:
 prompt = f"""Rate how relevant the context is to answering the user query.
Return ONLY a single float number between 0.0 and 1.0.

Query: {query}
Context: {context}"""
 return self._call_evaluator(prompt)
To keep production latency within user expectations, monitor end-to-end latency across these individual operational budgets:
| Pipeline Stage | Target Latency (P50) | Target Latency (P99) | Primary Bottleneck | Optimization Mechanism |
|---|---|---|---|---|
| Query Embedding | 12ms | 35ms | Network round-trip to API | Host local ONNX-quantized models (e.g. BGE-small) |
| Dense Vector Lookup | 18ms | 50ms | Index traversal on disk | Keep HNSW graph in memory; tune M and efConstruction |
| BM25 Sparse Retrieval | 10ms | 25ms | Token index lock | Use pre-tokenized in-memory inverted indices |
| RRF & Reranking | 60ms | 150ms | Cross-attention compute | Batch candidates; run FP16 TensorRT cross-encoders |
| LLM Token Generation | 400ms (TTFT) | 1200ms | Transformer autoregression | Stream responses immediately; leverage semantic caching |
Production Deployment Checklist
- Context Window Hygiene: Limit context injection to 5 to 7 reranked passages to avoid attention dilution and the lost-in-the-middle degradation curve.
- Semantic Caching: Place an in-memory cache ahead of the retrieval pipeline to serve repeated or semantically identical queries directly, targeting a 20% or higher cache hit rate.
- Vector Index Eviction: Pair vector stores with operational transactional databases. Ensure that document deletion triggers instant vector index removal to eliminate stale data leakage.
- Fallback Circuit Breakers: When top cross-encoder scores fall below 0.35, configure the system to output a graceful clarification prompt rather than forcing the model to generate from low-confidence matches.
Frequently Asked Questions
What is the primary difference between RAG and fine-tuning an LLM?
RAG supplies external dynamic data directly into the model context at runtime without altering network weights. Supervised rag training and fine-tuning modify internal model parameters to adapt tone, format, or specialized task behavior, but struggle with continuous factual updates.
How do you build a production-ready RAG pipeline from scratch?
To master how to build a rag pipeline, ingest documents via recursive chunking, generate embeddings using a high-throughput model, index vectors in ChromaDB, run hybrid dense-sparse search, apply cross-encoder reranking, and pass prioritized chunks to an LLM.
What chunk size yields the highest retrieval accuracy in Python RAG systems?
A chunk size between 256 and 512 tokens with a 10 to 20 percent overlap offers the optimal balance for most dense embedding models in python rag. Smaller chunks improve retrieval precision, while reranking mitigates the loss of surrounding contextual narrative.
How can engineering teams evaluate RAG retrieval performance objectively?
Engineers evaluate performance through the RAG Triad: context relevance, groundedness, and answer relevance. As covered in this rag system tutorial, frameworks track these metrics using synthetic test sets to calculate retrieval precision and hallucination rates across iterations.
Moving from a basic RAG prototype to a reliable production system demands rigorous engineering across each stage of the data pipeline. As demonstrated, standard vector search alone cannot guarantee accuracy in enterprise systems. Reliable retrieval requires a layered architecture: deterministic text chunking with rich metadata, hybrid scoring combining sparse keyword matching and dense vectors, and precision cross-encoder reranking to ensure context quality before sending tokens to the model context window.
By deploying automated evaluation pipelines that track context relevance, groundedness, and latency budgets, engineering teams can iterate safely without blind spot regressions. Use the zero-dependency and modular code examples provided in this guide as architectural blueprints. Continuously measure chunking boundaries against your retrieval precision, monitor drift, and maintain high standards for the context admitted into your generation endpoints.