
Fine-tuning massive foundation models has historically required multi-GPU clusters and weeks of compute time. By freezing pre-trained weights and injecting small, trainable decomposition matrices, engineers can now adapt models with minimal memory footprints. This shift has fundamentally changed the economics of model deployment in 2026.
This article provides an engineering-first breakdown of LoRA low rank adaptation of large language models. We move beyond theory to cover implementation patterns, rank selection strategies, and the resource-efficiency benchmarks necessary for production-grade AI systems.
Foundational Mechanics of LoRA in Deep Learning
At the center of LoRA in deep learning is the hypothesis that weight updates during model adaptation have a low intrinsic rank. In a standard transformer layer, weights are represented by large matrices W. During full fine-tuning, every parameter in W is updated, leading to a massive gradient calculation and memory overhead.
LoRA constrains this update by representing the change in weights, ΔW, as a product of two smaller matrices: A and B. If W is d x d, we decompose ΔW into d x r and r x d, where r is significantly smaller than d. Because r << d, the number of trainable parameters drops by orders of magnitude.
Engineering Insight: The choice of rank
racts as a capacity knob. A higher rank allows the model to capture more complex domain shifts but increases the VRAM footprint during training.
[Pre-trained Weights W (Frozen)] + [Low-Rank Update ΔW = BA]The LoRA Finetuning Paper: Origins and Mathematical Proof
The LoRA finetuning paper established that we do not need to update the entire parameter space to achieve state-of-the-art performance. The research demonstrated that the residual learning process is highly efficient when constrained to low-rank subspaces.
Core Validation Checklist:
- Evidence of rank-deficiency in weight updates during fine-tuning.
- Proof that performance remains comparable to full fine-tuning across GLUE benchmarks.
- Analysis of parameter efficiency compared to adapter-based methods which introduce latency.
- Verification that inference latency is zero because matrices can be merged with the original weights.
Implementation Framework for LoRA Machine Learning Pipelines
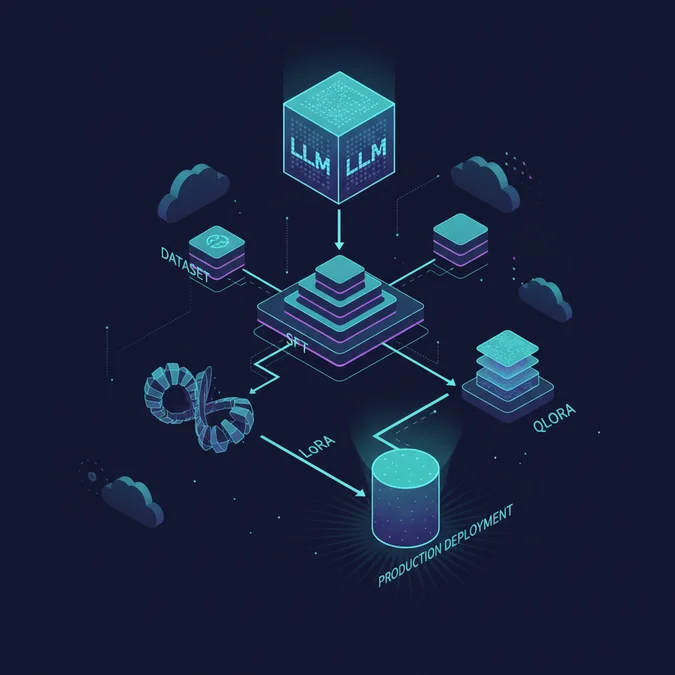
In 2026, implementing LoRA machine learning pipelines requires leveraging the peft library from Hugging Face. This library abstracts the decomposition process, allowing for seamless integration with bitsandbytes for quantization (QLoRA).
- Load the base model in 4-bit or 8-bit precision to minimize VRAM usage.
- Configure the
LoraConfigobject to specify target modules (e.g. q_proj, v_proj). - Wrap the model with the
get_peft_modelutility to inject adapter layers. - Run the training loop with optimized gradient accumulation.
from peft import get_peft_model, LoraConfig
from transformers import AutoModelForCausalLM

model = AutoModelForCausalLM.from_pretrained("meta-llama/Llama-3", load_in_4bit=True)
config = LoraConfig(r=16, lora_alpha=32, target_modules=["q_proj", "v_proj"], lora_dropout=0.05)
model = get_peft_model(model, config)
model.print_trainable_parameters()
Comparative Taxonomy: LoRA vs Full Fine-Tuning
Choosing between LoRA low rank adaptation of large language models and full fine-tuning depends on your available hardware and task complexity. The following table illustrates the trade-offs in a production context.
| Metric | Full Fine-Tuning | LoRA | QLoRA |
|---|---|---|---|
| VRAM Usage | Extremely High | Moderate | Low |
| Training Speed | Slow | Fast | Moderate |
| Storage Cost | Full Model Copy | Adapter Only (MBs) | Adapter Only (MBs) |
| Inference Latency | Baseline | Zero (Merged) | Zero (Merged) |
Factors That Affect Development Cost
- Model parameter count
- Target rank (r) value
- GPU instance hours
- Dataset size and complexity
Costs scale linearly with the number of trainable parameters injected and the total compute time required for convergence.
Frequently Asked Questions
What is the primary benefit of LoRA low rank adaptation of large language models?
LoRA reduces the number of trainable parameters by injecting low-rank matrices into transformer layers. This allows engineers to fine-tune massive models on consumer-grade hardware while maintaining performance levels nearly identical to full fine-tuning, significantly lowering memory requirements and storage costs.
How does LoRA machine learning differ from standard approaches?
Unlike standard fine-tuning which updates all model weights, LoRA machine learning freezes pre-trained weights and only trains small adapter matrices. This modular approach preserves the original model integrity while enabling efficient domain-specific adaptation without the massive computational overhead of full parameter updates.
Why is the original LoRA finetuning paper essential reading?
The LoRA finetuning paper provides the mathematical framework for low-rank decomposition. It demonstrates that weight updates during adaptation have a low intrinsic rank, justifying the use of projection matrices to capture the majority of model adaptation without the need for full weight retraining.
Where is LoRA in deep learning most effectively applied?
LoRA in deep learning is most effective for adapting large foundation models to specific downstream tasks. It is widely used in 2026 for building specialized agents, fine-tuning LLMs on proprietary datasets, and enabling rapid iterative experimentation where hardware resources are limited.
LoRA has effectively democratized LLM fine-tuning, turning previously impossible tasks into standard engineering workflows. By mastering rank selection and proper adapter merging, teams can maintain high model performance while drastically reducing infrastructure spend.
As you scale these pipelines, prioritize monitoring for catastrophic forgetting and validate your adapter weights against the base model before deploying to production environments.