
A production Java service stalls under load not because the JVM lacks compute efficiency, but because traditional thread-per-request architectures exhaust operating system threads during blocking I/O calls. For over a decade, Java microservices carried the baggage of bloated enterprise containers, heavy memory footprints, and fragile coordination tooling like Eureka and Hystrix. In modern distributed systems, these legacy patterns have been superseded by lightweight runtimes, event backplanes, and low-overhead language primitives.
Designing resilient, high-throughput microservices in 2026 requires standardizing on Java 21, Spring Boot 3.3+, Quarkus, and container-native runtimes. By taking advantage of Project Loom virtual threads, decoupled event streams, and sub-millisecond serialization protocols like gRPC, engineering teams can achieve orders-of-magnitude improvements in concurrency without migrating to complex reactive frameworks.
This architectural guide details the engineering standards required to build, orchestrate, and observe modern Java microservices at scale. We walk through runtime selection, transactional consistency patterns, fault tolerance configurations, and distributed tracing setups built specifically for production Kubernetes environments.
Core System Topology and Modern Java Microservices Architecture
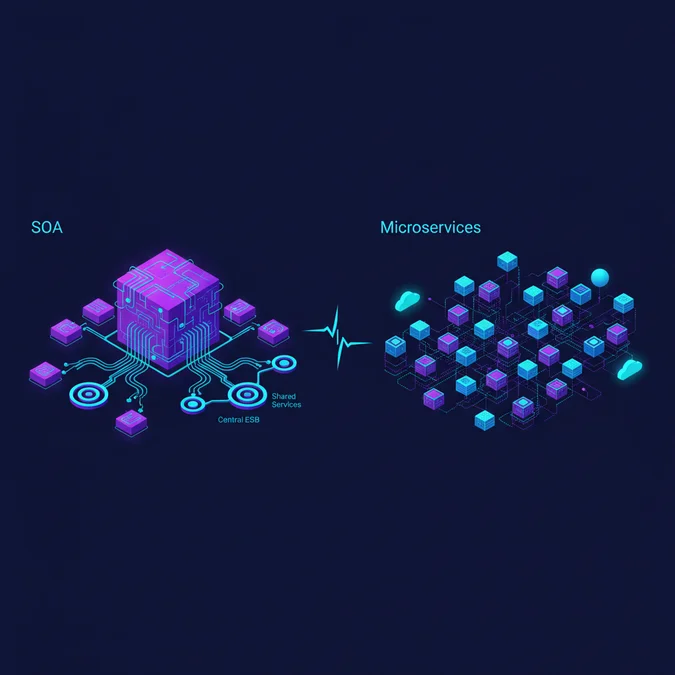
Modern java microservices diverge sharply from the distributed monoliths that characterized early cloud migrations. Rather than carving an application into dozens of arbitrary network hops that share a monolithic database, modern systems align strictly with domain boundaries using Martin Fowler’s bounded context pattern. Each microservice maintains complete encapsulation over its private data store, exposing state strictly through explicit synchronous contracts or asynchronous event streams.
In high-throughput environments, the topology centers on stateless compute tiers decoupled from stateful storage layers, communicating across dedicated internal networks managed via ingress gateways and event brokers.
+-----------------------------------------------------------------------------------+| Kubernetes Cluster |+-----------------------------------------------------------------------------------+| || +-------------------+ mTLS / HTTP/2 +-----------------------------+ || | API Gateway | ------------------------> | Order Service (Java 21) | || | (Spring Cloud GW) | | - Spring Boot 3.3 | || +-------------------+ | - Virtual Threads Enabled | || | +-----------------------------+ || | | || | mTLS / HTTP/2 | PostgreSQL || v v || +-------------------+ gRPC / Protobuf +-----------------------------+ || | Inventory Service | <------------------------ | Local Database (RDBMS) | || | (Quarkus 3.x) | | Outbox Events Table | || +-------------------+ +-----------------------------+ || | | || | PostgreSQL | Debezium CDC || v v || +-------------------+ +-----------------------------+ || | Inventory Store | | Apache Kafka Cluster | || +-------------------+ +-----------------------------+ || |+-----------------------------------------------------------------------------------+Implementing an effective microservices architecture java stack requires replacing deprecated Netflix OSS components with modern, standardized alternatives. Zuul has been replaced by Spring Cloud Gateway or Envoy, Ribbon client-side load balancing is replaced by Spring Cloud LoadBalancer or native Kubernetes CoreDNS routing, and Hystrix circuit breaking is superseded by Resilience4j.
| Architecture Dimension | Legacy Java Architecture (Java 8/11) | Modern Architecture (Java 21 / 2026) |
|---|---|---|
| Concurrency Model | Platform OS Threads (1:1 with OS kernel) | Virtual Threads (M:N carrier scheduling) |
| Service Discovery | Netflix Eureka / HashiCorp Consul daemon | Kubernetes CoreDNS and Service abstraction |
| Inter-Service Protocol | Synchronous JSON over HTTP/1.1 | gRPC / Protobuf and Asynchronous Kafka Events |
| Data Consistency | Dual writes or Two-Phase Commit (2PC / XA) | Transactional Outbox via Change Data Capture |
| Fault Tolerance | Netflix Hystrix (Thread Isolation) | Resilience4j Bulkheads and TimeLimiter |
| Telemetry Collection | Log parsing / Spring Cloud Sleuth | OpenTelemetry (OTel) / Micrometer Tracing |
Architectural Rule: Service-to-service communication paths must enforce strong network contracts. Edge ingress traffic should use REST with OpenAPI schemas or GraphQL, while internal east-west traffic between critical microservices must prioritize binary gRPC or event-driven Kafka topics to minimize serialization overhead and network latency.
Runtime Selection: Spring Boot 3, Quarkus, and Micronaut for Micro Web Services Java
When selecting a framework for micro web services java, architectural trade-offs revolve around memory footprint, cold-start latency, throughput under load, and developer ergonomics. The emergence of GraalVM Native Image compilation has redefined the viability of Java in serverless and auto-scaling environments, making startup time competitive with Go and Rust.
However, the introduction of Virtual Threads in Java 21 altered the runtime trade-off landscape. By abstracting blocking thread pools at the JVM level, standard JVM execution can rival the raw concurrency of reactive paradigms without sacrificing linear, step-by-step code structure or native tooling.
| Metric / Characteristic | Spring Boot 3.3+ (Standard JVM) | Spring Boot 3.3+ (GraalVM Native) | Quarkus 3.x (GraalVM Native) | Micronaut 4.x (GraalVM Native) |
|---|---|---|---|---|
| Cold Start Latency | 850 ms – 1.8 s | 45 ms – 75 ms | 15 ms – 35 ms | 20 ms – 40 ms |
| Base Memory (RSS) | 240 MB – 380 MB | 65 MB – 95 MB | 28 MB – 45 MB | 32 MB – 55 MB |
| Peak Throughput (I/O Bound) | 92,000 req/sec | 88,000 req/sec | 98,000 req/sec | 94,000 req/sec |
| Build / Packaging Time | 12 seconds | 185 seconds | 95 seconds | 110 seconds |
| Reflection / Dynamic Proxying | Full dynamic support | Requires AOT metadata | Build-time generated | Compile-time generated (APT) |
| Target Environment | Long-running containers | Scale-to-zero / KNative | Edge compute & Serverless | Microservices & Serverless |
Engineers often default to GraalVM native images purely for low cold-start numbers. However, compiling via native image disables JVM dynamic profile-guided optimizations (PGO) unless enterprise build tools are licensed. For standard microservices running continuously on Kubernetes clusters, running OpenJDK 21 on standard HotSpot with Virtual Threads enabled routinely matches or outperforms GraalVM native throughput under sustained load while cutting build times by 90%.
Choose Quarkus or Micronaut when deploying serverless functions, KNative scale-to-zero workloads, or running edge infrastructure where cold-start latency under 50ms and memory footprints below 50MB are mandatory. For enterprise core platforms with extensive library ecosystems and continuous uptime, Spring Boot 3.3+ on Java 21 provides optimal balance.
Building a Spring Boot Microservices Example: Order and Inventory Flow
A realistic spring boot microservices example demonstrates high-performance, non-blocking execution using modern Spring Boot 3.3+ patterns. In this scenario, an Order Service accepts an incoming purchase request, stores the order locally, and validates product availability by issuing a declarative HTTP call to an external Inventory Service.
Instead of relying on classic blocking thread pools or switching to Project Reactor’s Mono and Flux, we configure Spring Boot to delegate all incoming web requests to Java 21 virtual threads, allowing synchronous execution to scale to tens of thousands of concurrent connections.
Step 1: Configure Virtual Threads in Spring Boot
Ensure the Java 21 baseline is active and configure the embedded Tomcat server to spin up a virtual thread for every incoming HTTP request. Add the following parameter to your application.yml:
spring: application: name: order-service threads: virtual: enabled: trueserver: port: 8081 tomcat: threads: max: 200 # Serves as upper carrier limit; virtual threads handle concurrencyStep 2: Define Domain Models Using Java Records
Modern java microservices example implementations should leverage immutable record types instead of verbose Lombok annotations or boilerplate getters and setters. This eliminates mutable state bugs and reduces memory allocations.
package com.example.orderservice.domain;import java.math.BigDecimal;import java.util.UUID;public final class OrderContracts { public record CreateOrderRequest( UUID customerId, String sku, int quantity, BigDecimal unitPrice ) {} public record OrderResponse( UUID orderId, UUID customerId, String status, BigDecimal totalAmount ) {} public record InventoryCheckResponse( String sku, boolean available, int currentStock ) {}}Step 3: Define the Declarative HTTP Client
Spring Boot 3 introduces the HttpInterfaces client abstraction, replacing OpenFeign with native declarative HTTP clients backed by the non-blocking RestClient.
package com.example.orderservice.client;import com.example.orderservice.domain.OrderContracts.InventoryCheckResponse;import org.springframework.web.bind.annotation.PathVariable;import org.springframework.web.service.annotation.GetExchange;import org.springframework.web.service.annotation.HttpExchange;@HttpExchange("/api/v1/inventory")public interface InventoryClient { @GetExchange("/{sku}") InventoryCheckResponse checkStock(@PathVariable("sku") String sku);}Step 4: Implement Controller and Service Workflow
The controller routes incoming requests directly to the service layer, where blocking operations execute on virtual threads without thread-pinning concerns.
package com.example.orderservice.controller;import com.example.orderservice.client.InventoryClient;import com.example.orderservice.domain.OrderContracts.*;import org.slf4j.Logger;import org.slf4j.LoggerFactory;import org.springframework.http.HttpStatus;import org.springframework.http.ResponseEntity;import org.springframework.web.bind.annotation.*;import java.util.UUID;@RestController@RequestMapping("/api/v1/orders")public class OrderController { private static final Logger log = LoggerFactory.getLogger(OrderController.class); private final InventoryClient inventoryClient; public OrderController(InventoryClient inventoryClient) { this.inventoryClient = inventoryClient; } @PostMapping public ResponseEntity<OrderResponse> createOrder(@RequestBody CreateOrderRequest request) { log.info("Processing order on thread: {}", Thread.currentThread()); // Synchronous HTTP call executes seamlessly on a Virtual Thread InventoryCheckResponse stock = inventoryClient.checkStock(request.sku()); if (!stock.available() || stock.currentStock() < request.quantity()) { log.warn("Insufficient inventory for SKU: {}", request.sku()); return ResponseEntity.status(HttpStatus.CONFLICT).build(); } UUID orderId = UUID.randomUUID(); OrderResponse response = new OrderResponse( orderId, request.customerId(), "CONFIRMED", request.unitPrice().multiply(java.math.BigDecimal.valueOf(request.quantity())) ); return ResponseEntity.status(HttpStatus.CREATED).body(response); }}Distributed Consistency: Transactional Outbox and Microservices Examples
The biggest failure mode in real-world microservices examples is attempting to maintain data consistency across distributed boundaries using dual-write architectures. When an Order Service inserts a record into its relational database and immediately makes a network call to publish a message to Apache Kafka, one of those operations will eventually fail. If the network drops before Kafka acknowledges the publish, the database contains uncommitted business state; if the database transaction fails to commit, downstream services process phantom events.
Distributed two-phase commits (XA/2PC) are non-viable at scale due to latency, lock contention, and poor fault tolerance across cloud environments. The industry-standard solution for a production micro service example is the Transactional Outbox Pattern paired with Change Data Capture (CDC).
[HTTP Request] ---> (Order Service Application) | | 1. Begin Local DB Transaction v+-------------------------------------------------------------+| RDBMS (PostgreSQL) || || +-----------------------+ +-------------------------+ || | orders | | outbox_events | || |-----------------------| |-------------------------| || | id: UUID (PK) | | id: UUID (PK) | || | status: VARCHAR | | aggregate_type: VARCHAR | || | total: NUMERIC | | payload: JSONB | || +-----------------------+ +-------------------------+ || | | || +--- Both Committed Atomically --+ |+-------------------------------------------------------------+ | | 2. Read WAL Logs v +--------------------+ | Debezium CDC Engine| +--------------------+ | | 3. Publish Stream v +--------------------+ | Apache Kafka Topic | +--------------------+Production Implementation Checklist
- Atomic Local Write: Always write the business entity and the corresponding integration event into the same relational database transaction.
- Immutable Schema: Treat outbox event payloads as append-only records containing fully serialized JSON or Avro representations.
- Log-Based CDC: Avoid polling tables with
SELECT.. FOR UPDATE. Polling induces database CPU spikes and table bloat. Use Debezium to stream PostgreSQL write-ahead logs (WAL) straight to Kafka. - Consumer Idempotency: Guarantee that all consumer services implement idempotent event handling using an idempotency key (such as
event_id) backed by a unique database constraint.
Transactional Service Layer Implementation
package com.example.orderservice.service;import com.fasterxml.jackson.databind.ObjectMapper;import org.springframework.jdbc.core.JdbcTemplate;import org.springframework.stereotype.Service;import org.springframework.transaction.annotation.Transactional;import java.time.Instant;import java.util.Map;import java.util.UUID;@Servicepublic class OrderCommandService { private final JdbcTemplate jdbcTemplate; private final ObjectMapper objectMapper; public OrderCommandService(JdbcTemplate jdbcTemplate, ObjectMapper objectMapper) { this.jdbcTemplate = jdbcTemplate; this.objectMapper = objectMapper; } @Transactional public UUID createOrderWithOutbox(UUID customerId, String sku, int quantity) { UUID orderId = UUID.randomUUID(); UUID eventId = UUID.randomUUID(); // 1. Insert into primary domain table jdbcTemplate.update( "INSERT INTO orders (id, customer_id, sku, quantity, status) VALUES (?????)", orderId, customerId, sku, quantity, "CREATED" ); // 2. Prepare event payload Map<String, Object> eventPayload = Map.of( "orderId", orderId.toString(), "customerId", customerId.toString(), "sku", sku, "quantity", quantity, "timestamp", Instant.now().toString() ); try { String json = objectMapper.writeValueAsString(eventPayload); // 3. Insert into outbox table in the SAME transaction boundary jdbcTemplate.update( "INSERT INTO outbox_events (id, aggregate_type, aggregate_id, type, payload) VALUES (?????:jsonb)", eventId, "ORDER", orderId.toString(), "ORDER_CREATED", json ); } catch (Exception e) { throw new IllegalStateException("Failed to serialize outbox event", e); } return orderId; }}Resiliency Mechanics: Configuring a Fault-Tolerant Sample Microservice in Java
When microservices execute hundreds of remote network calls per second, downstream degradation can exhaust upstream thread pools and trigger cascading system failures. Building a resilient sample microservice in java requires implementing deterministic circuit breaking, adaptive rate limiting, and explicit bulkhead isolation.
Resilience4j has become the standard fault tolerance library for modern Java services, offering lightweight functional composition without the heavy background threads required by older tools.
| Resiliency Pattern | Purpose | Target Metric / Trigger | Fallback Behavior |
|---|---|---|---|
| Circuit Breaker | Halt requests to degraded downstreams | Failure rate exceeds 50% over sliding window | Return cached data or graceful error |
| TimeLimiter | Prevent thread holding on stalled I/O | Request execution time > 1500 ms | Trigger timeout exception immediately |
| ThreadPoolBulkhead | Isolate resource exhaustion across domains | Queue capacity reached limit (e.g. 50 requests) | Fast-fail downstream without starving callers |
| Retry | Recover from transient network blips | HTTP 503 or SocketTimeoutExceptions | Exponential backoff with jitter |
Configuring Resilience4j Declaratively
In your Spring Boot application.yml, define the circuit breaker parameters. This configuration creates a sliding window that monitors the last 10 remote invocations, tripping open if half of them fail or exceed latency thresholds:
resilience4j: circuitbreaker: instances: inventoryServiceBreaker: sliding-window-type: COUNT_BASED sliding-window-size: 10 minimum-number-of-calls: 5 failure-rate-threshold: 50 slow-call-rate-threshold: 50 slow-call-duration-threshold: 1000ms wait-duration-in-open-state: 10000ms permitted-number-of-calls-in-half-open-state: 3 automatic-transition-from-open-to-half-open-enabled: true timelimiter: instances: inventoryServiceBreaker: timeout-duration: 1500msAnnotated Service Layer with Fallback Handling
The service wraps the external integration point with the @CircuitBreaker annotation, catching transport failures and redirecting callers to an isolated fallback method:
package com.example.orderservice.service;import com.example.orderservice.client.InventoryClient;import com.example.orderservice.domain.OrderContracts.InventoryCheckResponse;import io.github.resilience4j.circuitbreaker.annotation.CircuitBreaker;import org.slf4j.Logger;import org.slf4j.LoggerFactory;import org.springframework.stereotype.Service;@Servicepublic class ResilientInventoryService { private static final Logger log = LoggerFactory.getLogger(ResilientInventoryService.class); private final InventoryClient inventoryClient; public ResilientInventoryService(InventoryClient inventoryClient) { this.inventoryClient = inventoryClient; } @CircuitBreaker(name = "inventoryServiceBreaker", fallbackMethod = "inventoryFallback") public InventoryCheckResponse checkInventoryWithProtection(String sku) { return inventoryClient.checkStock(sku); } public InventoryCheckResponse inventoryFallback(String sku, Throwable exception) { log.warn("Inventory service call failed for SKU: {}. Circuit breaker triggered fallback. Error: {}", sku, exception.getMessage()); // Degraded response: Assume out of stock or route to queue for manual fulfillment return new InventoryCheckResponse(sku, false, 0); }}Distributed Tracing and Observability with OpenTelemetry and Kubernetes
In an ecosystem of hundreds of interconnected Java processes, debugging latency bottlenecks or isolated 500 errors requires unified distributed context propagation. Legacy tools like Spring Cloud Sleuth have been replaced by the OpenTelemetry (OTel) standard, managed natively via the Micrometer Tracing bridge in modern Spring runtimes.
Context propagation works by attaching standardized W3C Trace Context headers (such as traceparent and tracestate) to every outgoing HTTP or gRPC request. Kubernetes sidecars or internal daemons collect these traces and ship them directly to Grafana Tempo, Jaeger, or Datadog.
# OpenTelemetry Collector Sidecar for Kubernetes PodspecapiVersion: apps/v1kind: Deploymentmetadata: name: order-service namespace: productionspec: replicas: 3 template: metadata: labels: app: order-service spec: containers: - name: order-service image: internal-registry.io/apps/order-service:3.3.0 env: - name: MANAGEMENT_OTLP_TRACING_ENDPOINT value: "http://localhost:4318/v1/traces" - name: MANAGEMENT_TRACING_SAMPLING_PROBABILITY value: "0.10" # Sample 10% of production traffic resources: limits: memory: "512Mi" cpu: "1000m" requests: memory: "256Mi" cpu: "250m" - name: otel-collector image: otel/opentelemetry-collector-contrib:0.95.0 args: ["--config=/etc/otel/config.yaml"] volumeMounts: - name: otel-config-vol mountPath: /etc/otel volumes: - name: otel-config-vol configMap: name: otel-collector-configWithin the Java codebase, Micrometer exposes low-overhead span management without tying the domain architecture directly to vendor SDKs.
package com.example.orderservice.telemetry;import io.micrometer.tracing.Span;import io.micrometer.tracing.Tracer;import org.slf4j.Logger;import org.slf4j.LoggerFactory;import org.springframework.stereotype.Component;@Componentpublic class PaymentTelemetryManager { private static final Logger log = LoggerFactory.getLogger(PaymentTelemetryManager.class); private final Tracer tracer; public PaymentTelemetryManager(Tracer tracer) { this.tracer = tracer; } public void recordPaymentSpan(String transactionId, Runnable operation) { Span customSpan = this.tracer.nextSpan().name("execute-payment").tag("transaction.id", transactionId); try (Tracer.SpanInScope ws = this.tracer.withSpan(customSpan.start())) { log.info("Executing payment logic inside distributed trace span"); operation.run(); } catch (Exception ex) { customSpan.error(ex); throw ex; } finally { customSpan.end(); } }}Production Tip: Always set dynamic tracing sampling rates in high-throughput environments. Sampling 100% of requests in a cluster serving 50,000 req/sec creates severe I/O backpressure and inflates telemetry storage costs. Configure
MANAGEMENT_TRACING_SAMPLING_PROBABILITYto sample between 5% and 10% under normal operation, scaling dynamically to 100% only for specific debugging contexts or non-200 HTTP responses.
Frequently Asked Questions
What distinguishes modern Java microservices from legacy service architectures?
Modern java microservices use Java 21 Virtual Threads to achieve high concurrency with standard imperative code, replacing heavy OS thread pools. They favor lightweight runtimes like Quarkus or Spring Boot 3, GraalVM native binaries, and event backplanes instead of enterprise application servers.
How do you handle distributed transactions across Java microservices?
In microservices architecture java, distributed transactions avoid two-phase commits due to latency and locking bottlenecks. Production systems implement the Transactional Outbox pattern, where local database transactions write events to an outbox table, subsequently published to brokers like Apache Kafka.
Which Java framework provides the fastest startup and lowest memory footprint?
For micro web services java, Quarkus and Micronaut compiled with GraalVM Native Image provide startup times under 50 milliseconds and base memory footprints below 40 megabytes. Spring Boot 3 with GraalVM support offers comparable metrics, though Quarkus leads slightly in build-time dependency injection.
How do Virtual Threads impact Spring Boot microservice throughput?
Virtual Threads decouple Java threads from operating system carrier threads. In a spring boot microservices example with blocking I/O, enabling Virtual Threads allows services to handle tens of thousands of concurrent requests without thread pool exhaustion or switching to reactive paradigms.
Building resilient, enterprise-grade Java microservices in 2026 demands a clean departure from the heavyweight, reflection-heavy practices of the past decade. By standardizing on Java 21 virtual threads, engineering teams can build high-throughput, imperative network services that match the performance of reactive architectures without the associated code complexity. Pairing these runtimes with event-driven data streaming, transactional outbox patterns, and declarative fault tolerance creates distributed systems that scale predictably under peak loads.
As you evaluate your current architecture, begin by auditing downstream dependencies and eliminating dual-write vulnerabilities. Transition your core services toward modern container-native foundations to ensure low-latency operations, unified observability, and rapid disaster recovery across distributed deployments.