
Failure Mode and Effects Analysis (FMEA) in software development is an inductive, structured methodology used by backend engineers to identify potential failure points across services, assess their systemic severity, determine likelihood of occurrence, evaluate observability detection gaps, and calculate a Risk Priority Number to guide architectural hardening before deployment.
FMEA cannot automatically locate runtime race conditions, rewrite brittle logic, or replace automated fuzzing and stress testing. If engineering teams apply it as a bureaucratic checkbox without coupling it to code-level safeguards and telemetry, the process produces static documentation that drifts from code realities. When adapted to modern software, FMEA operates as a pre-implementation stress model for complex distributed dependencies, database state machines, and microservice failure domains.
Backend systems frequently collapse under non-linear failure scenarios: cascading timeouts, database connection pool exhaustion, uncaught serialization mismatches, and unhandled deadlocks. This guide dissects how to adapt traditional hardware reliability engineering into an operational, code-level framework across backend stacks, including decoupled enterprise platforms and Laravel systems.
Deconstructing Software FMEA: Terminology and Mathematical Mechanics
Failure Mode and Effects Analysis originates in aerospace and defense, where physical component wear is predictable. Software failure modes diverge sharply from mechanical systems because code does not experience physical degradation. Instead, software failure modes stem from unanticipated state interactions, asynchronous drift, saturation thresholds, and unhandled edge boundary exceptions.
To execute a software FMEA, teams systematically quantify risk across three core vectors scored from 1 to 10:
- Severity (S): The operational impact on system integrity, data correctness, and client operations. A 1 indicates an unnoticeable cosmetic degradation, while a 10 signifies irrecoverable database corruption or persistent silent data loss.
- Occurrence (O): The statistical frequency or probability of a specific defect, race condition, or saturation event surfacing under typical or peak operational traffic.
- Detection (D): The inverse capacity of automated tests, monitoring, tracing, and health checks to identify and surface the failure before it compromises production workloads. A 1 represents immediate circuit breaker interception with automated rollbacks, while a 10 means the system silently yields bad outputs without triggering a single log entry.
The standard product of these three metrics is the Risk Priority Number (RPN):
RPN = Severity (S) × Occurrence (O) × Detection (D)RPN values scale theoretically from 1 to 1000. In strict enterprise environments, any failure mode yielding an RPN exceeding 120, or an individual Severity score of 9 or 10 regardless of total RPN, requires mandatory architectural mitigation before code passes peer review.
Adapting Hardware FMEA to Distributed Software Architectures
Traditional hardware FMEA operates under the Single Point Failure (SPF) assumption, asserting that multiple unrelated physical failures rarely strike concurrently. In distributed software, this assumption falls apart completely. A single degraded downstream dependency, such as an external third-party webhook receiver or a slow Elasticsearch index, rapidly cascades into upstream pool starvation, memory bloat, and socket exhaustion.
Software FMEA models must shift focus from isolated physical component failure to boundary interfaces. The critical interfaces comprise:
- Network and RPC boundaries: Latency inflation, payload truncation, DNS timeouts, and half-open TCP connections.
- Persistence and State interfaces: Pessimistic locking limits, transaction isolation levels, connection starvation, and queue lag.
- Execution contexts: Garbage collection pauses, thread pool saturation, memory leaks within long-running workers, and unhandled serialization variants.
Engineers analyzing complex cloud systems must apply lessons from modern low-level architectural primitives to ensure the system gracefully tolerates thread and memory exhaustion instead of terminating ungracefully.
Step-by-Step Execution of a Software FMEA Workshop
Conducting a productive software FMEA requires a disciplined protocol that avoids degenerating into an unfocused architecture critique. The optimal time to execute an FMEA is during the technical design phase, directly after architectural schema and sequence diagrams are drafted, but prior to implementation.
- Decompose the Subsystem: Map the target microservice, feature, or background pipeline into discrete units: HTTP ingestion, validation, persistence, asynchronous dispatch, and egress integrations.
- Brainstorm Failure Modes: For each unit, catalog every conceivable way it can fail to fulfill its design contract. Do not just ask ‘what if it crashes?’; ask ‘what if it returns correct data 4000ms too late?’ or ‘what if it duplicates processing during a network retry?’
- Map the Effects: Determine downstream consequences. Does the failure mode bubble up to end users as an HTTP 500 error, trigger cascading retries, or corrupt ledger balances?
- Identify Root Causes: Isolate the underlying mechanism, such as unindexed relational queries, lack of idempotency keys, or unbounded in-memory buffers.
- Score S, O, and D: Reach engineering consensus on numeric metrics based on standardized internal team rubrics.
- Prescribe Remediations: Assign engineering counter-actions (circuit breakers, dead letter queues, rate limiters, fallback models) directly to the architecture specification.
The Software FMEA Scoring Matrix
Subjective scoring leads to inconsistent RPN values across distributed engineering teams. Establishing concrete rubrics anchored in measurable system metrics stabilizes evaluations.
| Score | Severity (S) Metric | Occurrence (O) Probability | Detection (D) Capability |
|---|---|---|---|
| 1 | No client impact; minor debug noise. | < 0.001% of requests; rare edge condition. | Caught automatically in unit tests during CI build. |
| 2-3 | Minor latency increase; non-blocking telemetry loss. | 0.01% – 0.1%; isolated edge input. | Caught by integration tests or static analysis. |
| 4-6 | Degraded UX; non-critical background jobs delayed. | 0.5% – 2%; occurs under peak traffic spikes. | Caught by staging chaos tests or synthetic APM monitors. |
| 7-8 | Critical path degraded; partial read/write downtime. | 5% – 10%; routine bug or resource pinch. | Triggers production alert after customer impact begins. |
| 9-10 | Unrecoverable data loss; security breach; persistent corruption. | > 20%; structural architecture vulnerability. | Completely silent; identified solely via customer escalation. |
Engineering standards should prohibit merging code with any item exhibiting a Detection rating higher than 7, as high detection scores indicate observability blind spots.
FMEA in Practice: Resilient Payment Gateway Integration
Consider an enterprise checkout service interfacing with a third-party payment provider. Without rigorous failure mode analysis, engineers frequently code against the happy path, neglecting complex failure mechanics. Below is an architectural failure breakdown for an outbound payment dispatch:
| Failure Mode | Potential Effect | Cause | S | O | D | RPN | Recommended Mitigation |
|---|---|---|---|---|---|---|---|
| Gateway Read Timeout (504) | Double-billing customer via automated retry. | Network partition after gateway captured funds. | 9 | 4 | 8 | 288 | Deterministic idempotency keys with distributed lock. |
| Webhooks Arrive Out of Order | Order stuck in Pending state or fulfilled prematurely. | Asynchronous messaging race conditions. | 7 | 6 | 6 | 252 | State machine version constraints and payload timestamps. |
| DB Connection Pool Exhaustion | All backend endpoints drop incoming traffic. | Payment worker blocks DB connection during long HTTP call. | 8 | 5 | 5 | 200 | Release DB connections before initiating outbound HTTP. |
The highest initial vulnerability here is the gateway timeout (RPN 288). While occurrence is moderate, the severity of charging customers twice coupled with the difficulty of detecting whether the external provider executed the transaction yields an intolerable failure profile.
Implementing Architectural Mitigations in Code
Translating an FMEA finding into code requires addressing the specific root cause and detection gap directly. Below is a production-grade implementation addressing the gateway timeout failure mode using deterministic idempotency, distributed locking, and resilient transaction isolation in PHP/Laravel.
<php

declare(strict_types=1);

namespace App\Services;

use App\Exceptions\PaymentFailedException;
use App\Models\Order;
use Illuminate\Support\Facades\Cache;
use Illuminate\Support\Facades\Http;
use Illuminate\Support\Facades\Log;
use Illuminate\Support\Str;
use Throwable;

final class ResilientPaymentProcessor
{
 private const LOCK_TTL_SECONDS = 30;
 private const HTTP_TIMEOUT_SECONDS = 5;

 public function process(Order $order): bool
 {
 // Generate deterministic idempotency key to prevent double-billing
 $idempotencyKey = (string) Str:uuid();
 $lockKey = 'payment_lock_'. $order->id;

 // Acquire exclusive distributed lock on the order resource
 $lock = Cache:lock($lockKey, self:LOCK_TTL_SECONDS);

 if (!$lock->get()) {
 Log:warning('Concurrent payment attempt detected and throttled', ['order_id' => $order->id]);
 return false;
 }

 try {
 // Refresh order state inside lock boundary to prevent race updates
 $order->refresh();
 if ($order->isPaid()) {
 return true;
 }

 // Execute outbound network call with strict bounds to prevent thread hang
 $response = Http:timeout(self:HTTP_TIMEOUT_SECONDS)
 ->withHeaders([
 'Idempotency-Key' => $idempotencyKey,
 ])
 ->post('https://api.paymentprovider.internal/v1/charges', [
 'order_id' => $order->id,
 'amount_cents' => $order->total_cents,
 ]);

 if ($response->successful()) {
 $order->markAsPaid($response->json('charge_id'));
 return true;
 }

 Log:error('Gateway returned non-success response', [
 'order_id' => $order->id,
 'status' => $response->status(),
 'body' => $response->body(),
 ]);

 throw new PaymentFailedException('Gateway rejected transaction.');
 } catch (Throwable $e) {
 // Telemetry catch ensures D score improves from silent failure to immediate alert
 Log:critical('Payment processing exception surfaced', [
 'order_id' => $order->id,
 'exception' => $e->getMessage(),
 'trace' => $e->getTraceAsString(),
 ]);

 throw $e;
 } finally {
 $lock->release();
 }
 }
}
This implementation addresses three distinct aspects of the FMEA table: the distributed lock eliminates the race condition (lowering Occurrence), the deterministic UUID header forces gateway-level idempotency (mitigating Severity), and structured JSON logging with critical severity flags ensures observability monitors trigger within seconds (lowering Detection from 8 to 2).
FMEA for Relational Database Persistence and Migrations
Backend developers often treat the database as an infallible persistence engine, ignoring database-level failure modes that yield catastrophic cascading system outages. Database schemas and execution plans must be analyzed under the FMEA lens during architecture planning.
Deadlocks and Locking Escalations
Concurrent updates against unindexed foreign keys or out-of-order bulk updates force relational databases (such as PostgreSQL or MySQL) to escalate row-level locks to table-wide exclusive metadata locks. If a high-throughput endpoint triggers this, the worker pool backs up entirely within seconds, dropping subsequent requests.
Migration Safety on Multi-Million Row Tables
Running an unhedged ALTER TABLE ADD COLUMN DEFAULT or creating an unindexed foreign key directly blocks table writes on systems with large datasets. To evaluate these issues during testing, teams should establish reliable baseline environments using efficient database population techniques before running destructive schema migrations in staging environments.
Mitigating these failure modes involves mandating non-blocking schema migration patterns, applying lock timeouts on all migration scripts, and ensuring transaction boundaries remain brief and free of outbound network requests.
Failure Modes in Asynchronous Job Queues and Event Workers
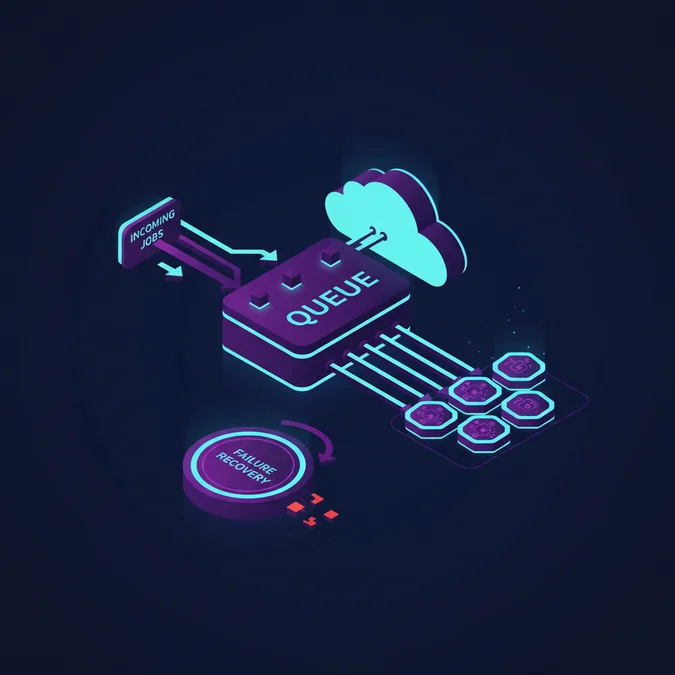
Decoupling workload components via asynchronous message brokers (Redis, RabbitMQ, Amazon SQS) is a standard architectural approach. However, message queues introduce a unique set of failure modes that require defensive handling.
- Poison Pill Payloads: A job payload containing unexpected data shapes causes the worker to throw an uncaught exception, return the job to the queue, and trigger an infinite failure loop that stalls the entire worker queue.
- Worker Memory Degradation: Long-running daemon workers (such as Laravel queue workers or Node.js background workers) executing thousands of jobs frequently suffer from minor memory leaks or uncollected static variables. Over time, the worker process exhausts its memory limit, terminating mid-job during database mutations.
- Queue Backpressure Saturation: When message ingestion outpaces consumption rate, Redis or RabbitMQ instances can exhaust RAM allocations, resulting in eviction policies purging unconsumed operational events.
FMEA mitigations require setting hard retry ceilings (such as maximum 3 attempts), maintaining explicit Dead Letter Queues (DLQ) with automated alerting, and configuring workers to self-terminate and recycle after processing a set threshold of jobs or megabytes.
Observability as an Architectural Failure Mitigator
A critical metric within software FMEA is the Detection (D) score. An application architecture can tolerate an edge failure with moderate occurrence if the mean time to detect (MTTD) approaches zero seconds. Conversely, a failure mode with low severity can compromise systems if it runs silently for weeks.
Improving detection requires shifting from passive log aggregation to active semantic instrumentation:
- Distributed Tracing Contexts: Inject W3C Trace Context headers (
traceparent) across every inter-service HTTP request and asynchronous job payload. This guarantees that when a failure manifests, developers trace the execution timeline from ingress down to persistence. - Dead Man’s Snitches: Relying solely on alerts for failure occurrences creates a critical blind spot: what if the alerting service or daemon worker crashes entirely? Implement heartbeats for recurring background tasks that alert on absence of execution.
- Dynamic Health Checks: A health check endpoint that only returns
HTTP 200 OKwithout testing actual database read/write availability and cache connectivity provides false positives, keeping compromised containers active in the load balancer pool.
Continuous FMEA: Integrating Risk Analysis into Modern CI/CD
FMEA should not remain a static spreadsheet created during project conception and forgotten as the codebase evolves. Modern engineering pipelines can enforce failure mode mitigations through automated code gates.
Teams can translate FMEA mitigation policies into CI verification steps:
- Static Analysis for Detection Holes: Configure tools like PHPStan, Psalm, or ESLint at maximum strictness to prohibit empty
catchblocks, unhandled promises, and untyped method returns that conceal runtime errors. - Schema Migration Linters: Integrate schema checks into PR validation pipelines to catch unsafe migrations (such as adding columns without algorithms that avoid table locks) before code reaches staging.
- Automated Contract Testing: Use Pact or OpenAPI contract tests to identify breaking API changes at build time, preventing serialization mismatches between separate deployments.
- Chaos Injection Gates: In staging environments, run chaos routines that simulate network latency spikes, database disconnects, and worker crashes to empirically confirm that fallback mechanisms engage under pressure.
FMEA Comparison Against Chaos Engineering and Threat Modeling
Engineering teams frequently confuse FMEA with other defensive analysis methodologies, including Threat Modeling and Chaos Engineering. While they complement one another, their analytical objectives and lifecycles diverge.
| Dimension | Software FMEA | Threat Modeling (STRIDE) | Chaos Engineering |
|---|---|---|---|
| Primary Focus | Functional reliability, edge cases, stability. | Security exploits, trust boundaries, malicious actors. | Empirical validation of distributed system resilience. |
| Phase Applied | Design and planning phase (Pre-code). | Architecture and code review phase. | Staging and production environments (Post-deploy). |
| Methodology | Inductive, analytical risk quantification (RPN). | Deductive categorisation of vulnerabilities. | Active runtime fault injection experiments. |
| Primary Output | Architectural safeguards and telemetry requirements. | Security controls, encryption, authorization rules. | Empirical incident mitigation verification. |
FMEA establishes the theoretical hypotheses of failure modes and prescribes safeguards. Threat modeling evaluates the system against active human adversaries. Chaos Engineering subsequently introduces controlled real-world failures into production environments to confirm that the FMEA mitigations function as designed.
Pitfalls and Anti-Patterns in Software FMEA Implementation
Adopting FMEA without pragmatic discipline can introduce team frictions and counterproductive practices. Engineers should watch for several common implementation traps:
The Bureaucratic Spreadsheet Trap
When teams require exhaustive 80-row FMEA spreadsheets for minor bug fixes or low-risk CRUD features, developers quickly experience process fatigue. Reserve full FMEA workshops for critical systemic shifts: core database redesigns, architectural decoupling, payment gateways, and authentication state transitions.
Optimism Bias in Detection Scoring
Engineers often assume that because an exception handler exists, the Detection score should sit at 1 or 2. An exception caught and logged to an unindexed file without active APM threshold alerting or on-call paging has a true Detection score of 7 or 8. Assess Detection by confirming whether an on-call engineer would be notified within five minutes of the event occurring.
Ignoring Operational Maintenance Failure Modes
Analysis must extend beyond pure runtime code execution. It must encompass deployment and operational routines: failed rollbacks, schema migrations across blue-green deployments, cache invalidation stampedes during cold boots, and secrets rotation interruptions.
Architectural Foundation Directory
Establishing disciplined reliability frameworks across your engineering organization requires mastering both core language idioms and infrastructure patterns.
Explore our complete Laravel, Basics directory for more guides.
Failure Mode and Effects Analysis bridges the gap between theoretical architecture plans and chaotic production realities. Quantifying failure via Severity, Occurrence, and Detection metrics enables backend teams to systematically de-risk complex systems long before shipping code to production. Building reliable architectures requires recognizing that failures will happen, and engineering the system so that failures remain isolated, observable, and recoverable.
Prioritize high-RPN failure paths by deploying distributed locks, circuit breakers, and bounded retry strategies. Treat telemetry as a core architectural tier rather than a post-launch add-on. When failure analysis becomes a natural step in the engineering design cycle, system stability stops being a matter of good fortune and becomes an intentional engineering discipline.