
A Laravel job queue offloads resource-heavy tasks, such as third-party API calls, document rendering, and email dispatching, from the primary HTTP request lifecycle to an asynchronous background worker pool. This architectural separation guarantees sub-100ms HTTP response times, isolates synchronous web traffic from network latency, and prevents database thread exhaustion under peak user loads.
Many engineering teams operate under the misconception that adopting background queues automatically eliminates performance bottlenecks. In production environments, improperly configured background workers simply shift load away from Nginx and PHP-FPM directly onto your persistence layer and message brokers. Without strict rate limits, deterministic timeouts, and disciplined serialization boundaries, a high-volume job queue can trigger severe database deadlocks, Redis memory exhaustion, and cascading downstream microservice outages.
Scaling background processing demands a clear understanding of queue drivers, serialization mechanics, memory management, and deterministic error handling. Transitioning tasks from synchronous controller code into distributed background jobs requires deliberate trade-offs between processing latency, infrastructure complexity, and system reliability.
Understanding the Asynchronous Processing Lifecycle
When a web client issues a request to a Laravel application, the web server executes code within the limits of PHP-FPM process pools. Any external dependency invoked synchronously, such as an S3 file upload, a Stripe billing call, or a PDF generation routine, ties up that dedicated worker thread for the entire network round trip. Under moderate traffic, this synchronous blocking exhausts available process slots, leading to HTTP 504 gateway timeouts and dropped connections.
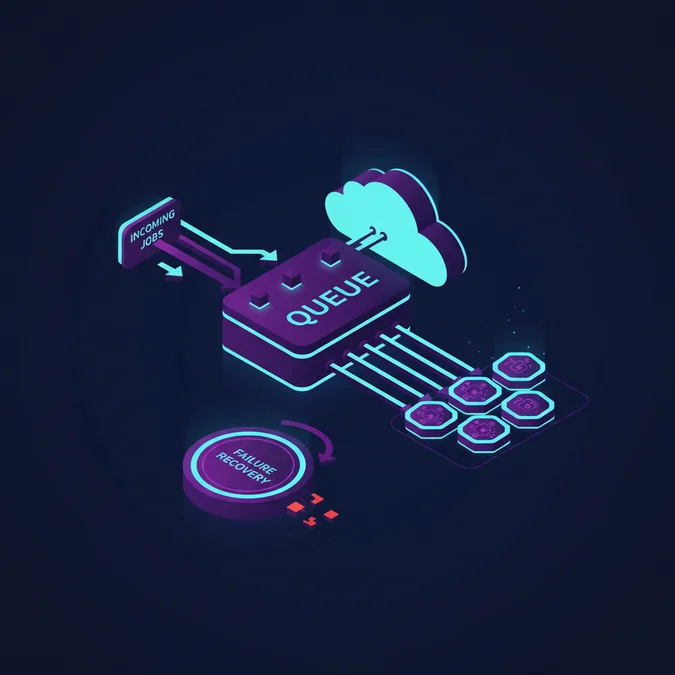
The Laravel job queue decouples task declaration from task execution. When code calls the dispatch() method on a job class, the framework does not run the job logic. Instead, it serializes the job class instance into a standardized JSON payload and pushes that payload into a broker, such as Redis, Amazon SQS, or a relational database table. The web worker immediately returns an HTTP response to the client, keeping average response times well within strict performance targets.
In the background, independent CLI daemon processes running php artisan queue:work poll the queue broker, claim payloads atomically, deserialize the class metadata, resolve necessary container dependencies, and execute the job’s handle() method. This separation insulates synchronous user traffic from transient network failures, computational surges, and slow third-party service responses.
Driver Selection: Redis vs Amazon SQS vs Database
Selecting an appropriate queue driver establishes the throughput ceiling and recovery profile of an engineering infrastructure. Laravel natively supports several queue drivers through a unified interface, but each driver involves distinct operational trade-offs across storage latency, visibility management, and message throughput.
| Driver | Throughput (Ops/Sec) | Horizontal Scaling Complexity | Persistence & Durability | Operational Overhead |
|---|---|---|---|---|
| Database (MySQL/PostgreSQL) | Low (100 – 500) | Low | ACID Compliant (Disk) | Low (Uses existing DB) |
| Redis | Very High (5,000 – 20,000+) | Medium (Sentinel / Cluster) | Configurable (AOF/RDB in-memory) | Medium (Requires RAM tuning) |
| Amazon SQS | High (Scales dynamically) | Very Low (Managed Cloud) | Highly Redundant (Multi-AZ) | Low (Managed Service) |
| Beanstalkd | High (1,000 – 3,000) | Medium | Configurable (Disk log) | Medium (Legacy service) |
The relational database driver utilizes your primary application database to track queued tasks via tables such as jobs and failed_jobs. While this eliminates extra infrastructure for early-stage applications, it introduces heavy write lock contention and table fragmentation at scale. Every push, reservation, and deletion requires write queries against the database, competing directly with analytical read queries and transactional business data. Teams evaluating their infrastructure footprint often compare these dynamics when reviewing broader enterprise application architectures.
Redis functions entirely in-memory, delivering single-digit millisecond latency for pop and push operations. It supports deep concurrency and high throughput, making it ideal for systems running thousands of micro-jobs per minute. However, Redis queues reside in operational memory. If your Redis node exhausts its allocated memory budget or lacks Append-Only File (AOF) persistence, abrupt server reboots can drop payloads.
Amazon SQS offers a fully managed, serverless model with near-infinite auto-scaling. It removes worker contention management and server patching entirely, but introduces outbound HTTP network latency for every queue poll operation. Choosing between Redis and SQS often hinges on whether your priority is raw microsecond processing speeds or managed, zero-maintenance queue persistence.
Job Serialization and Payload Boundaries
When a job class is queued, Laravel leverages PHP serialization to capture class properties. A common pitfall in production systems involves passing bloated, deeply nested Eloquent model instances directly into the job constructor. Passing entire models balloons the JSON payload size inside your queue broker, increasing network transfer latency and memory consumption across your worker cluster.
To mitigate this, Laravel jobs use the SerializesModels trait. When present, the serializer strips away active database connections, cached model relationships, and loaded attribute arrays, storing only the model class name and its primary key in the payload. Upon execution, the worker uses those identifiers to re-query the model fresh from the database inside the daemon process.
<php

namespace App\Jobs;

use App\Models\Invoice;
use Illuminate\Bus\Queueable;
use Illuminate\Contracts\Queue\ShouldQueue;
use Illuminate\Foundation\Bus\Dispatchable;
use Illuminate\Queue\InteractsWithQueue;
use Illuminate\Queue\SerializesModels;

class FinalizeInvoiceJob implements ShouldQueue
{
 use Dispatchable, InteractsWithQueue, Queueable, SerializesModels;

 // Rely on SerializesModels to store only the identifier in the queue
 public function __construct(public Invoice $invoice)
 {
 // Avoid eager loading relationships here; load them inside handle()
 }

 public function handle(): void
 {
 // Model is automatically refetched fresh from the database
 if ($this->invoice->is_settled) {
 return;
 }

 $this->invoice->markAsSettled();
 }
}
This design introduces a critical operational reality: state can change between the moment a job is dispatched and the moment it is deserialized and executed by a worker. Stale state issues occur when an entity updates or drops out of the database during that intervening window. If the entity is deleted before the job executes, deserialization fails, throwing a ModelNotFoundException unless the property is typed as nullable or marked with the SerializesAndRestoresModelIdentifiers conventions.
Worker Process Management with Supervisord
A fundamental operational distinction exists between queue:work and queue:listen. The queue:listen command spins up a fresh, isolated PHP-CLI instance for every single job processed. While convenient for local development because it automatically reflects code changes without a restart, it incurs massive OS process overhead that makes it entirely unsuitable for production environments.
Conversely, queue:work boots the Laravel application runtime framework once and retains it in memory across hundreds of successive jobs. This yields exceptional execution speed, but introduces strict architectural constraints. Any memory leaks inside third-party libraries, static variables, or unbounded arrays persist across executions until the worker process terminates. Workers must be actively managed by an external process supervisor such as Supervisord, which monitors daemon health and restarts dead or recycled processes.
[program:laravel-worker]
process_name=%(program_name)s_%(process_num)02d
command=php /var/www/app/artisan queue:work redis --sleep=3 --tries=3 --max-time=3600 --max-jobs=1000 --memory=128
autostart=true
autorestart=true
user=www-data
numprocs=8
redirect_stderr=true
stdout_logfile=/var/log/supervisor/worker.log
stopwaitsecs=3600
Key supervisor and worker directives include:
- –max-time=3600: Instructs the worker to self-terminate after running for one hour, providing a clean baseline reset for internal memory buffers.
- –max-jobs=1000: Gracefully cycles the worker after a deterministic quantity of processed tasks, mitigating undetected memory leaks.
- –memory=128: Ensures the worker aborts execution cleanly if internal process memory exceeds 128 megabytes.
- stopwaitsecs=3600: Directs Supervisord to allow running workers ample time to finish current long-running tasks before issuing a forceful SIGKILL.
Managing Timeouts, Visibility, and Deadlocks
Production queue failures often trace back to a mismatch between job execution timeouts and driver visibility settings. When a background worker picks up a job from a broker like Redis or SQS, the broker does not delete the payload immediately. Instead, it initiates an internal reservation timer known as visibility timeout, controlled in Laravel by the retry_after configuration option in config/queue.php.
If the background worker takes longer to process the job than the duration allocated by retry_after, the queue broker assumes the worker died unexpectedly and releases the job back into the pool. A second worker immediately picks up the exact same job while the first worker is still actively executing it. This scenario causes duplicate execution, split-brain database updates, and potential transaction deadlocks.
| Configuration Directives | Target Layer | Primary Function | Rule of Thumb |
|---|---|---|---|
retry_after |
Queue Broker (config/queue.php) | Duration the broker hides a job from other workers before assuming failure | Must always be strictly greater than --timeout |
--timeout |
CLI Worker Runtime (queue:work) | Maximum seconds an individual job process is allowed to run before receiving SIGALRM | Must be kept lower than retry_after by at least 30-60 seconds |
$timeout |
Job Class Property | Overrides CLI timeout specifically for a single job class implementation | Use for distinct edge-case tasks like large report generation |
To avoid race conditions and duplicated executions, your configuration must enforce this invariant rule: retry_after must always exceed the timeout value by a safe operational margin. If a job is configured with a timeout of 120 seconds, your retry_after setting on that connection must be set to at least 180 seconds. Failing to account for this gap is one of the most frequent causes of duplicate processing in high-concurrency environments.
Failure States, Retries, and Exponential Backoff
Distributed systems must assume eventual failure. External third-party payment gateways experience downtime, external APIs return HTTP 429 rate limit codes, and database nodes fail over. A resilient job implementation uses controlled retry budgets and exponential backoff curves rather than aggressively looping retries that amplify downstream traffic spikes.
By defining the $tries property alongside the backoff() method, developers can instruct Laravel to progressively space out successive execution attempts. This gives upstream systems room to recover without exhausting worker resources on immediate, futile re-runs.
<php

namespace App\Jobs;

use Illuminate\Bus\Queueable;
use Illuminate\Contracts\Queue\ShouldQueue;
use Illuminate\Queue\InteractsWithQueue;
use Throwable;

class SyncVendorRecordsJob implements ShouldQueue
{
 use InteractsWithQueue, Queueable;

 public int $tries = 4;
 public int $maxExceptions = 2;

 // Implement exponential backoff delays in seconds (10s, 60s, 300s)
 public function backoff(): array
 {
 return [10, 60, 300];
 }

 public function handle(): void
 {
 // Execute API synchronization logic
 }

 // Handle definitive task termination after exhausting retry limits
 public function failed(?Throwable $exception): void
 {
 // Log to telemetry or notify internal engineering channels
 }
}
When all designated retries are exhausted, Laravel pushes the execution context, serialized payload, and full stack trace into the failed_jobs database table. This records a verifiable audit trail of unrecoverable failures, allowing engineering teams to run diagnostic post-mortems and replay failed jobs using php artisan queue:retry once upstream dependencies are restored.
Concurrency Control and Mutex Locking
When hundreds of worker processes consume jobs simultaneously, concurrent updates on shared domain resources inevitably cause race conditions. For example, if two separate jobs process billing payments for the exact same customer account simultaneously, the application might issue duplicate invoices or execute double withdrawals.
Instead of relying on fragile application-level checks, Laravel provides a job middleware architecture that natively leverages atomic cache locks (Redis mutexes) to coordinate execution safety across workers.
<php

namespace App\Jobs;

use App\Models\Account;
use Illuminate\Bus\Queueable;
use Illuminate\Contracts\Queue\ShouldQueue;
use Illuminate\Queue\InteractsWithQueue;
use Illuminate\Queue\Middleware\WithoutOverlapping;

class ProcessAccountRebalanceJob implements ShouldQueue
{
 use InteractsWithQueue, Queueable;

 public function __construct(public Account $account)
 {}

 public function middleware(): array
 {
 // Prevent concurrent execution for the same account key for up to 60 seconds
 return [
 (new WithoutOverlapping($this->account->id))
 ->releaseAfter(30)
 ->expireAfter(60)
 ];
 }

 public function handle(): void
 {
 // Rebalancing calculations guaranteed to execute with mutual exclusivity
 }
}
The WithoutOverlapping middleware attempts to acquire an atomic lock using the supplied identifier before invoking handle(). If a second worker attempts to run a job matching that identifier while the lock is active, the middleware releases the second job back onto the queue with a configurable delay, preventing concurrent access without losing the task.
Prioritization, Segregation, and Dedicated Workers
Routing every application job to a single shared queue inevitably causes low-priority, high-volume tasks to block mission-critical workloads. If an application queues 10,000 marketing emails ahead of an account password reset email, the user waiting on that password reset is blocked behind the marketing backlog.
Queue segregation solves this problem by categorizing tasks into dedicated pipelines, such as high, default, and low. Workers are then assigned to service queues in a strict prioritization order.
# Process jobs on 'high' completely before inspecting 'default' or 'low'
php artisan queue:work redis --queue=high,default,low
While priority strings help resolve resource competition, mission-critical environments often require isolated worker pools. Under this topology, an isolated pool of supervisor processes handles only the high queue, while a separate pool handles background data synchronization and reporting. This guarantees that an unexpected surge in reporting requests cannot saturate all available CPU cycles, leaving authentication tasks free to process uninterrupted.
Teams developing fast, reactive administrative panels with dynamic tools like a data administration generator often leverage isolated queue workers to offload data import and export operations without slowing down the primary user interface.
Monitoring, Scaling, and Telemetry via Laravel Horizon
Operating a Redis-based queue infrastructure in high-throughput environments requires direct insight into throughput rates, job wait times, and process allocations. Laravel Horizon provides an operational dashboard and code-driven configuration layer specifically tailored for Redis queues.
Horizon replaces standard command-line queue workers with an intelligent master supervisor. Instead of configuring fixed process counts in Supervisord, Horizon dynamically adjusts worker allocations based on the real-time depth of individual queues, spinning up extra workers during load spikes and terminating them during idle periods.
<php

// config/horizon.php configuration excerpt
'environments' => [
 'production' => [
 'supervisor-primary' => [
 'connection' => 'redis',
 'queue' => ['high', 'default'],
 'balance' => 'auto',
 'autoScalingStrategy' => 'time',
 'minProcesses' => 4,
 'maxProcesses' => 32,
 'balanceMaxShift' => 2,
 'balanceCooldown' => 3,
 'tries' => 3,
 ],
 ],
],
Horizon tracks operational metrics that simple server monitoring tools miss. It measures queue latency, which is the time a job spends waiting in line before a worker picks it up. A queue depth of 500 jobs might not indicate an issue if wait times remain under one second, but a small queue with high latency signals that jobs are processing too slowly and starving downstream operations.
Production Implementation Checklist and Migration Strategy
Moving from synchronous execution to a distributed background queue requires a safe rollout plan to avoid silent payload drops and infrastructure strain. Follow this systematic deployment checklist when rolling out queues in production:
- Audit Payload Boundaries: Verify that no job classes accept raw database connections, binary streams, or oversized models into their constructors. Rely on primary key references managed by the
SerializesModelstrait. - Align Timeouts and Driver Visibility: Ensure that the
retry_aftervalue on your queue connections is configured with a safe operational buffer above worker timeouts across all environments. - Graceful Zero-Downtime Deployments: Ensure your deployment scripts execute
php artisan queue:restartafter new code is published. Because long-running workers store application state in memory, they must exit cleanly so Supervisord can restart them on the newly deployed codebase. - Verify Dead-Letter Infrastructure: Run database migrations to provision the
failed_jobstable, and confirm that an operational notification alerts the team whenever a job exhausts its retry budget. - Isolate High-Priority Workloads: Segment critical tasks into dedicated queues and run isolated supervisor processes to prevent resource starvation during non-critical batch processing runs.
Explore our complete Laravel directory for more architectural deep dives and operational guides: [Explore our complete Laravel, Basics directory for more guides.](/topics/topics-laravel-basics/)
A well-architected Laravel job queue is a fundamental building block of a responsive, resilient application. Offloading slow, blocking tasks from your primary request thread protects application response times and keeps your database connections stable under fluctuating demand.
However, running queues in production demands rigorous configuration around job serialization, worker lifetimes, and execution timeouts. By decoupling critical and non-critical workflows, setting conservative retry budgets, and continuously monitoring queue latency, engineering teams can build reliable background processing systems that scale smoothly as traffic grows.