
Modern production environments demand more than just model deployment; they require a robust, fault-tolerant AI system architecture capable of handling unpredictable request spikes while maintaining strict latency SLAs. When transitioning from prototype to production, engineers often encounter bottlenecks in data orchestration and inference throughput that standard cloud architectures fail to address.
This article provides an engineering blueprint for building scalable, high-performance AI systems. We move beyond theoretical abstractions to examine the critical trade-offs between RAG, fine-tuning, and agentic workflows, providing you with the technical patterns necessary to sustain reliable AI operations at scale.
Core Components and the Modern AI System Architecture
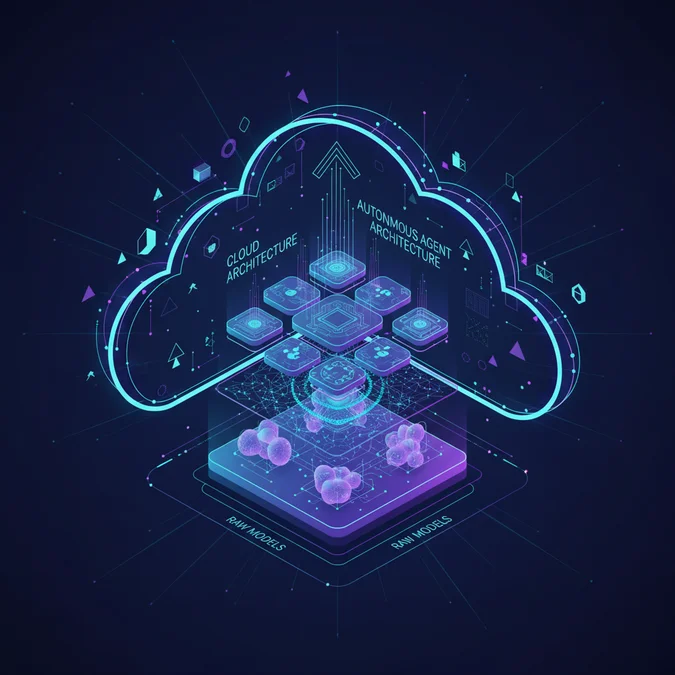
A production-grade AI system architecture is defined by the decoupling of data ingestion, retrieval logic, and model inference. By isolating these layers, teams can scale individual components based on resource consumption rather than scaling the entire monolith.
| Component | Primary Responsibility | Scaling Strategy |
|---|---|---|
| Vector Store | High-speed similarity search | Horizontal sharding |
| Orchestration Layer | Agentic workflow control | Distributed task queues |
| Inference Engine | Model execution | GPU-optimized auto-scaling |
Engineering Note: Always enforce strict separation between your embedding pipeline and your query pipeline to prevent write-heavy indexing from impacting read-heavy inference latency.
Optimizing the Internal AI Structure for Inference
The internal AI structure of your deployment determines how effectively a model processes context. Whether you are using a transformer-based model or a specialized agent, the efficiency of the attention mechanism and KV-caching strategy is paramount.
- Use quantization to reduce model weight memory footprint.
- Implement continuous batching to maximize GPU utilization.
- Configure KV-cache eviction policies to handle long-context windows.
# Example of configuring a high-performance inference engine parameter
config = InferenceConfig(
 quantization="fp8",
 max_batch_size=128,
 kv_cache_strategy="paged_attention",
 enable_speculative_decoding=True
)
Engineering the Architecture of AI for Low-Latency Environments
Designing the architecture of AI for sub-100ms response times requires minimizing data movement across the network. The most successful patterns involve colocating the vector database with the inference compute cluster.
| Metric | Latency (Optimized) | Latency (Standard) |
|---|---|---|
| Retrieval | 15ms | 80ms |
| Inference | 45ms | 250ms |
| Total | 60ms | 330ms |
// Optimized retrieval logic using async/await patterns
async function getContext(query) {
 const vector = await embedder.encode(query);
 return await vectorDB.search(vector, { top_k: 3, latency_budget: "20ms" });
}
Production Resilience and Fault-Tolerant Patterns
Systems fail in production due to model timeouts, downstream API rate limiting, or corrupted vector indexes. Resilience is built through circuit breakers and graceful degradation.
- Implement exponential backoff for all upstream model provider calls.
- Use dead-letter queues for failed agentic tasks.
- Maintain a fallback ‘static’ model response if the primary LLM exceeds the latency budget.
Callout: Observability is not optional. Every inference request must be logged with a trace ID that spans the retrieval, context augmentation, and generation phases.
Frequently Asked Questions
What defines a production-ready ai system architecture?
A production-ready ai system architecture integrates scalable data pipelines, low-latency vector databases, and modular model orchestration. It prioritizes decoupled services, robust error handling, and observability to ensure consistent performance under high-throughput conditions while balancing cost, accuracy, and latency requirements in real-time environments.
How does model selection impact the internal ai structure?
Model selection dictates the internal ai structure by determining the compute, memory, and latency requirements. Opting for fine-tuned small language models often simplifies the architecture compared to massive RAG-based systems, which require complex indexing layers, retrieval logic, and additional caching mechanisms to maintain efficient throughput.
What is the primary challenge when designing the architecture of ai?
The primary challenge in the architecture of ai is balancing the trade-off between inference speed and model reasoning quality. Engineers must design systems that minimize data movement, optimize vector search latency, and implement effective caching strategies to handle production load without sacrificing output reliability.
Building a resilient system requires constant iteration on your architectural patterns. By prioritizing observability and decoupling your inference stack, you can maintain high throughput even as your data complexity grows.
Evaluate your current bottlenecks against the patterns discussed above to ensure your infrastructure is ready for the next phase of your scaling journey.