
In 2026, the bottleneck for generative AI and semantic retrieval is rarely the model inference speed, but rather the efficiency of the underlying vector index. When datasets scale beyond a few million embeddings, performing exhaustive linear scans becomes computationally prohibitive. Engineers must move beyond brute-force similarity search to survive the latency requirements of modern production environments.
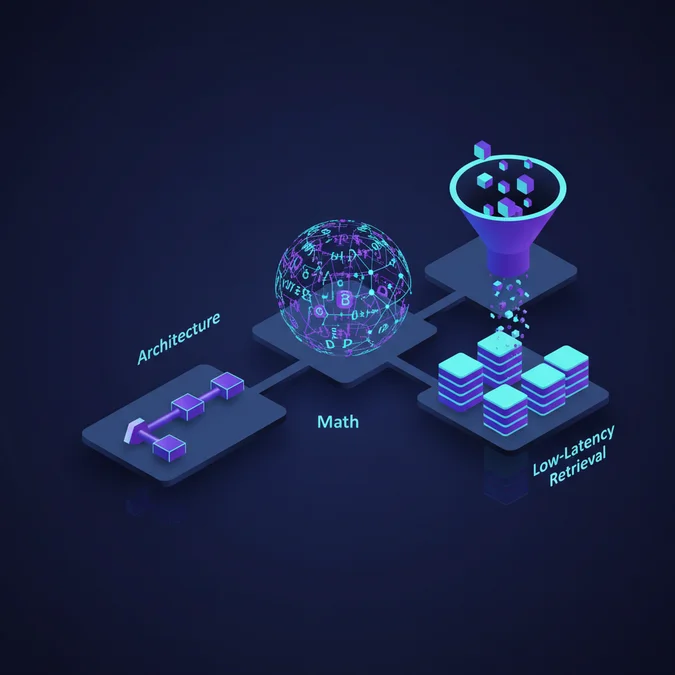
This guide dissects the mechanics of vector indexing, evaluating how different structures manage the high-dimensional search space. We will examine the trade-offs between memory footprint, recall accuracy, and query latency to provide a blueprint for building high-scale retrieval systems.
Foundational Mechanics of the Vector Index
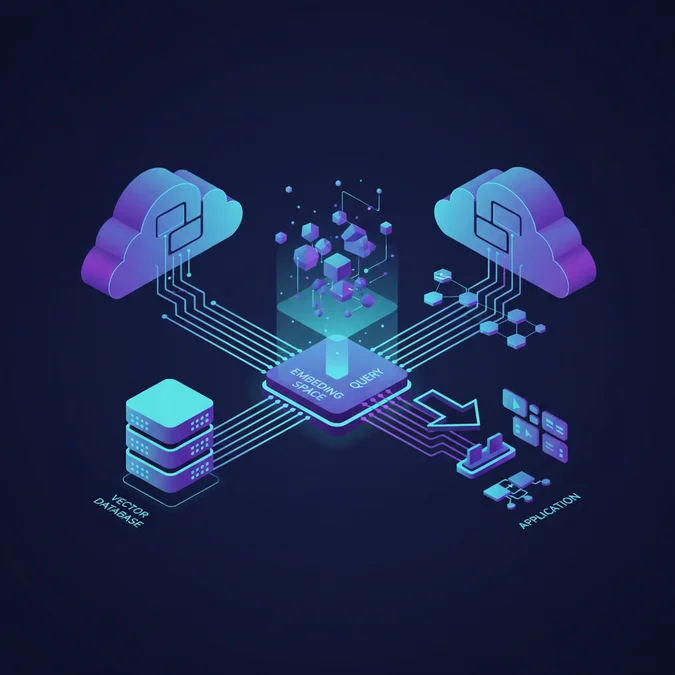
A vector index functions by transforming high-dimensional embedding spaces into navigable data structures. Without an index, finding the nearest neighbors to a query vector requires calculating the Euclidean or Cosine distance against every single record in the database. This O(N) complexity is unsustainable for large-scale production applications.
Technical Insight: The efficacy of a vector index relies on the assumption that semantic similarity correlates with geometric proximity. By grouping these vectors into graph-based or cluster-based structures, we can prune the search space, focusing only on regions likely to contain the optimal results.
The core challenge is the curse of dimensionality. As dimensions increase, the distance between any two points in the space becomes nearly uniform, making traditional spatial indexing methods like KD-trees ineffective. Modern indexing addresses this by utilizing approximate nearest neighbor (ANN) algorithms that prioritize speed over absolute precision.
Taxonomy of Vector Database Indexing Algorithms
Choosing the correct vector database indexing strategy requires understanding the mathematical foundations of common algorithms. The following table contrasts the most widely used approaches in 2026 production systems.
| Algorithm | Primary Mechanism | Memory Usage | Recall Performance |
|---|---|---|---|
| HNSW | Hierarchical Small World Graphs | High | Excellent |
| IVF | Inverted File Clustering | Moderate | Good |
| PQ | Product Quantization | Very Low | Variable |
| Flat | Exhaustive Search | Low | Perfect |
HNSW remains the industry standard for low-latency requirements, trading significant RAM for rapid traversal. Conversely, IVF methods excel when memory is constrained, as they partition the space into Voronoi cells, only searching the most relevant clusters.
Engineering Trade-offs in Vector Search Index Implementation
Implementing a vector search index involves navigating the tension between throughput and accuracy. A common pitfall is over-tuning recall at the expense of system stability. Use the following checklist to evaluate your deployment:
- Memory Budget: Ensure your index fits in RAM. Swapping to disk will cause latency spikes that break real-time SLAs.
- Update Frequency: HNSW is notoriously expensive to update. If your data changes hourly, consider an IVF-based approach or a streaming index implementation.
- Dimensionality: High-dimension vectors (e.g. 1536+) increase the ‘centroid’ count required for IVF, potentially negating speed gains.
The following Python snippet demonstrates a basic FAISS implementation for high-speed indexing:
import faiss
import numpy as np

def create_index(d, nlist=100):
 quantizer = faiss.IndexFlatL2(d)
 index = faiss.IndexIVFFlat(quantizer, d, nlist)
 return index

# Training is required for IVF indexes
index = create_index(128)
index.train(data_subset)
index.add(dataset)
Global Perspectives on Indice Vector Strategies
Deploying an indice vector strategy at scale requires consideration of geographic data residency and hardware acceleration. In 2026, global systems leverage distributed index sharding to maintain sub-millisecond response times across regions.
| Strategy | Application | Hardware Requirement |
|---|---|---|
| Distributed Sharding | Global multi-region clusters | High Network I/O |
| Quantized Compression | Edge deployment | Low RAM |
| GPU Acceleration | High-throughput batch | NVIDIA H100/A100 |
For systems handling billions of vectors, the strategy shifts toward hybrid approaches, combining IVF with Product Quantization to minimize the data footprint while maintaining acceptable recall levels.
Frequently Asked Questions
What is a vector index?
A vector index is a specialized data structure designed to accelerate similarity searches in high-dimensional spaces. By organizing embeddings into geometric structures like graphs or clusters, it allows systems to retrieve relevant data points without performing exhaustive, computationally expensive linear scans across the entire dataset.
How does vector database indexing improve search speed?
Vector database indexing improves speed by partitioning the vector space into manageable regions or hierarchical structures. Algorithms like HNSW or IVF limit the search scope to the most promising candidate vectors, drastically reducing the number of distance calculations required to find the top-k nearest neighbors.
Why use a vector search index for AI applications?
A vector search index is essential for AI applications because it enables real-time retrieval of unstructured data. As models generate massive volumes of embeddings, an index provides the necessary throughput and low latency to power semantic search, recommendation engines, and context-aware generative AI features at scale.
What is the primary function of an indice vector?
The primary function of an indice vector is to map high-dimensional coordinates to a searchable structure that supports fast nearest-neighbor queries. It transforms complex semantic relationships into a format that hardware can process efficiently, ensuring optimal balance between retrieval accuracy and memory usage.
Selecting a vector index is a balance of hardware constraints, update frequency, and recall requirements. There is no one-size-fits-all solution; the most robust systems are those that monitor recall decay over time and adapt their indexing parameters dynamically.
By prioritizing memory management and understanding the limitations of your chosen algorithm, you can build a search architecture capable of handling the demands of modern AI-driven applications.