
A render pipeline is the series of computational and rasterization stages that ingests multidimensional geometry, material configurations, and scene light topologies to produce a two-dimensional raster image on a target framebuffer. Modern real-time graphics architectures balance fixed-function silicon blocks against massively parallel programmable shader stages, orchestrating memory traffic across high-bandwidth on-chip caches and off-chip VRAM.
In production game engines, rendering failures rarely stem from raw arithmetic unit exhaustion alone. Instead, bottlenecks manifest when memory bus saturation, cache line eviction thrashing, excessive CPU draw dispatch overhead, and state-change pipeline bubbles starve the hardware. Transitioning from abstract engine scripting down to physical silicon requires understanding how high-level scene representations decompose into hardware command lists.
This technical breakdown traces graphics pipeline execution from fundamental silicon hardware blocks to high-level game engine abstractions, evaluating architectural trade-offs across forward, deferred, and clustered shading paradigms, custom Scriptable Render Pipeline implementations, and modern compute-driven mesh shader workflows.
Hardware Anatomy of the Modern Rendering Pipeline
At the physical silicon layer, a modern graphics processing unit (GPU) does not treat geometry as continuous mathematical surfaces. It schedules discrete thread groups across arrayed execution units, alternating between fixed-function logic blocks and general-purpose compute hardware. Understanding the hardware render pipeline requires tracking how data transitions between programmable cores and hardwired silicon stages.
+-----------------------------------------------------------------------------------+
| GPU Silicon Pipeline |
+-----------------------------------------------------------------------------------+
| [Fixed-Function] Input Assembler (VRAM Buffer Fetch & Index Decoding) |
| | |
| [Programmable] Vertex Shader (Transform to Clip Space, Attribute Packing) |
| | |
| [Programmable] Tessellation & Geometry Shaders (Optional Primitive Expansion) |
| | |
| [Fixed-Function] Tessellator / Primitive Assembler & Viewport Clipper |
| | |
| [Fixed-Function] Hierarchical-Z Early Depth Test & Triangle Setup |
| | |
| [Fixed-Function] Rasterizer (Scan Conversion & Pixel Interpolation) |
| | |
| [Programmable] Fragment / Pixel Shader (BRDF Evaluation, Texture Fetch) |
| | |
| [Fixed-Function] Late Z/Stencil, Raster Operations (ROP), Color Blending |
+-----------------------------------------------------------------------------------+
The execution lifecycle of a modern rendering pipeline adheres to a strictly defined progression of stages:
- Input Assembler (Fixed-Function): The GPU reads index and vertex buffers directly from allocated VRAM via a dedicated L2 cache path. It unpacks vertex attributes, resolves index arrays, and organizes raw vertex records into geometric primitives such as triangle lists, strips, or patches.
- Vertex Shader (Programmable): Compute units execute user shader code per vertex. The hardware transforms incoming local space positions into homogeneous clip space using model-view-projection matrices, while populating attribute registers with surface normals, tangents, and texture coordinates.
- Tessellation and Geometry Amplification (Programmable/Fixed-Function): If enabled, the Hull Shader determines subdivision levels, the fixed-function Tessellator produces sub-primitive topologies, and the Domain Shader calculates resulting vertex positions. Optional Geometry Shaders can discard or amplify full primitives, though modern pipelines minimize this stage due to on-chip memory reallocation costs.
- Primitive Assembly and Clipping (Fixed-Function): Coordinates in clip space undergo perspective division to form Normalized Device Coordinates (NDC). Primitives crossing the camera frustum boundary are clipped, while triangles facing away from the viewing vector are discarded via back-face culling logic prior to raster allocation.
- Hierarchical-Z and Triangle Setup (Fixed-Function): The setup engine converts floating-point vertex coordinates into edge equations across discrete pixel grids. Hierarchical-Z units check bounding boxes of incoming primitives against a low-resolution on-chip depth buffer, discarding fully occluded geometry before running pixel shaders.
- Rasterization (Fixed-Function): Scan-conversion hardware samples coverage across the bounding rectangle of each primitive. Sub-pixel coverage masks are evaluated, interpolating perspective-correct vertex attributes across individual fragment candidates.
- Fragment / Pixel Shader (Programmable): Execution units launch lockstep warps or wavefronts corresponding to active fragments. The shader samples texture arrays, evaluates Bidirectional Reflectance Distribution Functions (BRDFs), and outputs final linear color attributes along with optional custom depth outputs.
- Output Merger and ROP Units (Fixed-Function): Raster Operation Processors (ROPs) carry out final depth-stencil validation, alpha blending arithmetic, and sub-pixel coverage resolve before atomic writes push the resulting 32-bit or 64-bit color vectors into physical framebuffer tile memory.
Silicon Reality: Programmable stages run on unified SIMD compute blocks. When a pipeline alternates rapidly between heavily divergent fragment execution and dense vertex transformations, physical wave schedulers can stall if register allocation per thread exceeds architectural register file limits.
Architectural Paradigms: Forward, Deferred, and Clustered Compared
A critical engineering decision in real-time engine design is the selection of the core rasterization render pipeline. The chosen paradigm determines how lighting evaluation scales relative to geometric density, dynamic light volume, and display resolutions such as 4K or ultra-wide formats.
Traditional Forward Rendering evaluates lighting during the initial geometry pass. Each triangle fragment calculates contributions from all affecting light sources directly within its active pixel shader. While forward pipelines maintain a compact memory footprint and support native hardware Multi-Sample Anti-Aliasing (MSAA), dynamic light calculations scale as O(Geometry * Lights), leading to massive overdraw penalties in dense urban or interior scenes.
Deferred Shading separates scene rasterization into two distinct phases. The first geometry pass writes intrinsic material properties (albedo, world-space normal, roughness, metallic, depth) into a set of render targets known as the G-Buffer. The secondary lighting pass then evaluates screen-space lighting against the G-Buffer data. This bounds computational complexity to O(Screen Resolution * Lights). However, the high VRAM bandwidth required to write and read large G-Buffers can saturate mobile and console memory buses, and hardware MSAA becomes technically prohibitive without costly custom resolve passes.
Clustered Deferred and Forward+ architectures address the light scalability problem by subdividing the camera frustum into a three-dimensional grid of spatial clusters (X, Y, and depth-based Z slices). Prior to rasterization, a compute shader bins dynamic lights into these spatial voxels. Fragment shaders query only the exact light list intersecting their specific cluster, combining the low geometric overhead of forward rendering with deferred lighting efficiency.
| Evaluation Metric | Forward Rendering | Traditional Deferred Shading | Clustered Shading (Forward+ / Deferred) |
|---|---|---|---|
| Dynamic Light Scaling | Poor: O(Geometry × Dynamic Lights) | Linear: O(Pixels × Dynamic Lights) | Excellent: O(Geometry × Lights per Cluster) |
| Memory Bandwidth Consumption | Low: Minimal write traffic; single render target | High: Heavy G-Buffer writes and reads (64–128 bpp) | Moderate to High: Dependent on forward or deferred pass variant |
| Hardware MSAA Support | Native: Direct hardware sample evaluation | Extremely complex: Requires manual per-sample G-Buffer resolve | Native if implemented over forward baseline; complex if deferred |
| Material Variation Support | High: Arbitrary shaders per object instance | Constrained: All objects must fit the G-Buffer layout | High: Preserves distinct material models while isolating light loops |
| Transparent Surface Handling | Native: Standard alpha blending in single pass | Broken: Geometry cannot deposit into G-Buffer; needs forward pass | Native: Transparent objects sample identical 3D cluster buffers |
| Tile Cache Friendliness | High: Optimal for mobile tile-based GPUs | Poor: Large buffers spill outside on-chip tile SRAM | High: Clustered forward keeps framebuffers compact |
Engine-Level Abstraction: Deconstructing the Unity Render Pipeline
Modern game engines do not expose raw graphics hardware directly to high-level gameplay code. Instead, engines abstract hardware dispatch behind a unified rendering pipeline framework. In Unity, the Scriptable Render Pipeline (SRP) shifts pipeline scheduling out of closed native C++ binaries into managed C# control loops, giving developers direct control over culling, batch compilation, and render pass submission.
The Unity render pipeline ecosystem provides two primary pre-configured architectures built atop the core SRP API: the Universal Render Pipeline (URP) and the High Definition Render Pipeline (HDRP). URP uses single-pass forward and light-culled forward variants tailored for mobile, XR, and mid-range devices. HDRP utilizes compute-heavy clustered deferred and path-tracing frameworks targeted at modern desktop and console hardware.
using UnityEngine;using UnityEngine.Rendering;public class CustomHardwareRenderPipeline: RenderPipeline { private readonly RenderPipelineAsset configurationAsset; public CustomHardwareRenderPipeline(RenderPipelineAsset asset) { this.configurationAsset = asset; } protected override void Render(ScriptableRenderContext context, Camera[] cameras) { foreach (Camera camera in cameras) { // 1. Configure camera properties and frustum planes context.SetupCameraProperties(camera); CommandBuffer cmd = CommandBufferPool.Get("CustomPass_CameraSetup"); // 2. Clear color and depth targets on active framebuffer cmd.ClearRenderTarget(true, true, Color.black); context.ExecuteCommandBuffer(cmd); CommandBufferPool.Release(cmd); // 3. Execute CPU visibility culling against scene geometry if (!camera.TryGetCullingParameters(out ScriptableCullingParameters cullingParams)) { continue; } CullingResults cullingResults = context.Cull(ref cullingParams); // 4. Configure filtering rules and hardware state sorting var sortingSettings = new SortingSettings(camera) { criteria = SortingCriteria.CommonOpaque }; var drawingSettings = new DrawingSettings(new ShaderTagId("SRPDefaultUnlit"), sortingSettings) { enableInstancing = true, enableDynamicBatching = false }; var filteringSettings = new FilteringSettings(RenderQueueRange.opaque); // 5. Submit draw commands back to ScriptableRenderContext context.DrawRenderers(cullingResults, ref drawingSettings, ref filteringSettings); // 6. Draw skybox and transparent surfaces context.DrawSkybox(camera); // 7. Flush memory queue and signal physical hardware dispatch context.Submit(); } }}The C# code does not immediately issue direct instructions to the GPU driver. Instead, the ScriptableRenderContext serves as an internal buffer queue. The host engine constructs execution dependencies, culls meshes against the view frustum, evaluates spatial shadows, and schedules command buffers. Only when context.Submit() executes does the native engine layer ingest the instructions, performing driver-level validation and populating API-specific hardware ring buffers.
Architecture Tip: Avoid allocating heap memory inside custom SRP render loops. Calling methods that generate temporary arrays inside
Render()triggers managed Garbage Collection (GC) spikes, degrading frametime consistency regardless of raw GPU compute headroom.
The CPU-to-GPU Command Buffer Lifecycle
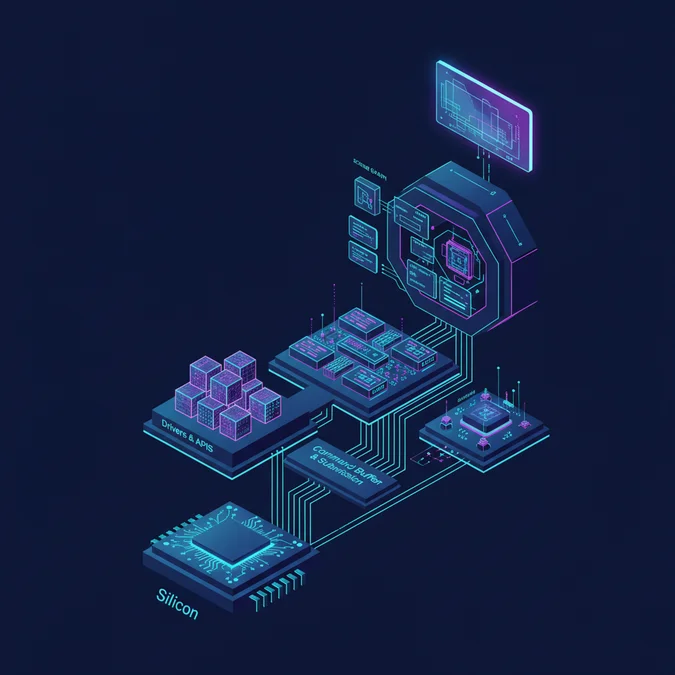
A high-performance render pipeline requires deterministic handoffs between the host CPU and the graphics hardware. When an engine issues a draw call, it does not immediately activate hardware execution units on the GPU silicon. It traverses a structured lifecycle across driver abstractions, system memory rings, and hardware command queues.
- Draw Call Generation: The engine traverses the spatial scene graph, checks bounding hierarchies, and filters visible mesh instances. Materials, shader parameters, dynamic light positions, and matrix buffers are validated on the CPU.
- Command Encoding and Argument Packing: The engine records draw arguments into a Command Buffer via modern graphic APIs (Vulkan, DirectX 12, or Metal). These include base vertex offsets, instance counts, texture descriptors, and pipeline state objects (PSOs).
- Driver Validation and Pipeline State Binding: If using low-overhead explicit APIs, PSO state switches are baked up front. The driver confirms that blend parameters, depth comparisons, rasterizer rules, and binding layouts are valid, avoiding runtime state-checking overhead.
- Ring Buffer Ingestion (Host to Device): The operating system kernel driver maps the command memory blocks into a shared ring buffer. Direct Memory Access (DMA) engines copy constant buffers, transform matrices, and index configurations across the PCI-Express bus directly into VRAM.
- GPU Command Queue Scheduling: The physical GPU firmware command processor consumes data packets sequentially from its hardware queues (Asynchronous Compute Queue, Direct Graphics Queue, or DMA Transfer Queue).
- Workgroup Dispatch and Hardware Execution: The hardware work distributor breaks draw commands down into wavefronts or warps, dispatching thread groups across Compute Units (CUs) or Streaming Multiprocessors (SMs) according to active pipeline states.
Next-Gen Shifts: Compute-Driven Rendering and Mesh Shaders
For decades, the standard hardware rendering pipeline remained tethered to the traditional Input Assembler, Vertex Shader, and Geometry Shader path. In high-density scenes containing tens of millions of micro-triangles, this classic path creates critical CPU bottlenecks. The CPU must organize draw structures, index buffers, and instance lists, while the GPU fixed-function Input Assembler struggles to process millions of small vertex allocations.
Next-generation architectures abandon CPU-directed draw dispatches in favor of fully Compute-Driven Pipelines and Mesh Shader architectures. In a compute-driven paradigm, the CPU records a single indirect draw command: ExecuteIndirect or DrawIndirect. A compute shader takes over host responsibilities on the GPU, evaluating bounding-box frustum intersection, performing occlusion culling via Hierarchical-Z depth pyramids, selecting discrete levels of detail (LOD), and populating indirect draw arguments directly into GPU local memory.
// Modern HLSL Task and Mesh Shader Paradigm#define GROUP_SIZE 32struct MeshletPayload { uint meshletIndices[GROUP_SIZE];};// Task Shader: Evaluates coarse cluster culling on the GPU[numthreads(GROUP_SIZE, 1, 1)]void TaskMain(uint gtid: SV_GroupIndex, uint dtid: SV_DispatchThreadID) { bool isVisible = EvaluateBoundingSphere(dtid); uint waveOffset = WavePrefixCountBits(isVisible); if (isVisible) { payload.meshletIndices[waveOffset] = dtid; } uint totalVisible = WaveActiveCountBits(isVisible); DispatchMesh(totalVisible, 1, 1, payload);}// Mesh Shader: Replaces the Input Assembler and Vertex Shader[numthreads(GROUP_SIZE, 1, 1)][outputtopology("triangle")]void MeshMain( uint gtid: SV_GroupIndex, in payload MeshletPayload payload, out vertices VertexOutput verts[64], out indices uint3 triangles[126]) { uint meshletId = payload.meshletIndices[gtid]; SetMeshOutputCounts(GetVertexCount(meshletId), GetTriangleCount(meshletId)); verts[gtid] = UnpackVertexAttributes(meshletId, gtid); triangles[gtid] = ComputeIndices(meshletId, gtid);}Mesh shaders replace the legacy Vertex, Tessellation, and Geometry shader stages with two streamlined stages: the Task (Amplification) Shader and the Mesh Shader. The task shader evaluates a cluster of primitives (called a meshlet, typically 64 vertices and 126 triangles). If the cluster is outside the frustum or occluded, it is discarded immediately. Surviving meshlets pass directly to the mesh shader, which computes local vertex positions and output topology in local on-chip thread memory before routing fragments to the rasterizer, entirely bypassing the fixed-function input assembly bottleneck.
| Pipeline Attribute | Legacy Fixed-Function Assembly | Task & Mesh Shader Pipeline |
|---|---|---|
| Primitive Culling Granularity | Per-object on CPU; per-triangle post-vertex | Per-cluster (Meshlet) early on GPU silicon |
| CPU Draw Call Overhead | High: Requires per-batch state setup | Minimal: Single indirect compute dispatch |
| Geometry Amplification Efficiency | Poor: Geometry shaders bottleneck cache | High: Task shaders generate meshlets natively |
| Memory Access Pattern | Scattered index buffer fetches across VRAM | Coalesced, linear meshlet reads into on-chip LDS |
| Hardware Availability | Universal (DirectX 9 through 12, Vulkan, Metal) | Modern Hardware (DirectX 12 Ultimate, Vulkan 1.3+) |
Production Profiling and Pipeline Bottleneck Remediation
Optimizing an interactive rendering pipeline requires precise isolation of the bottleneck layer. Graphics pipelines fail under performance pressure across four distinct domains: CPU submission overhead, GPU vertex/geometry limits, fragment rasterization and ALU load, and physical VRAM bandwidth saturation.
Using profiling tools such as RenderDoc, NVIDIA Nsight Graphics, PIX, or AMD Radeon Developer Tool Suite (RDTS), apply this systematic checklist to diagnose and remediate common rendering issues:
- Check CPU/GPU Bound Status First: Determine whether the CPU frame time or GPU frame time dictates framerate. If CPU frame time dominates, optimize draw call counts, enable GPU instancing, or transition repetitive scene loops to compute-driven indirect drawing.
- Identify and Eliminate Overdraw: Overdraw occurs when a single pixel fragment runs its pixel shader multiple times within a single frame. Sort opaque geometry front-to-back to leverage hardware Early-Z rejections. For forward pipelines, consider a minimal Depth Pre-Pass to establish depth bounds prior to heavy lighting evaluation.
- Analyze VRAM Bandwidth Utilization: Memory bandwidth saturation occurs when high-resolution framebuffers, uncompressed textures, or multi-sampled targets exhaust the physical memory interface. Enforce modern block compression (BC7 on PC/console, ASTC on mobile), avoid redundant multi-pass blits, and merge separate G-Buffer layers where precision allows.
- Alleviate Fragment ALU Pressure: If the GPU core execution units are saturated with complex math, optimize branching paths within shader code. Replace costly dynamic branches with material variants, calculate complex lighting values in local tangent space, and precompute mathematical constants inside compute passes.
- Inspect Texture Cache Hit Rates: Poor texture cache locality causes execution warps to stall waiting for VRAM data. Verify that all runtime textures feature fully generated mipmap chains and use anisotropic filtering judiciously.
- Mitigate Pipeline State Object (PSO) Stalls: Excessive runtime driver validation creates frame stutter. Pre-warm and compile all PSOs during engine initialization or level load to prevent driver compilation spikes during gameplay.
Optimization Rule: Never optimize fragment shaders when profiling tools reveal execution pipeline stalls caused by texture cache misses. Addressing cache locality and mipmap settings often resolves the apparent ALU bottleneck without modifying mathematical algorithms.
Frequently Asked Questions
What is the primary function of a render pipeline?
A render pipeline is the sequence of steps that ingests 3D geometric data and transforms it into a 2D pixel image on a display. It coordinates CPU draw commands, GPU geometry processing, rasterization, and pixel shading.
How does the Unity render pipeline differ from a raw graphics API?
A raw graphics API like Vulkan or DirectX 12 exposes bare-metal GPU control, whereas the Unity render pipeline provides high-level abstractions for culling, batching, and pass scheduling via C# scripting, translating engine scenes into low-level graphics commands automatically.
When should an engine team transition from forward to deferred rendering?
An engine should switch to deferred rendering when dynamic light count scales past dozens per scene, because deferred rendering decouples geometry complexity from lighting calculations, decoupling shading cost from scene vertex count at the cost of higher memory bandwidth.
How do mesh shaders change the classic rendering pipeline?
Mesh shaders replace the fixed-function vertex fetching, vertex shader, and hull/domain/geometry stages with a flexible, compute-like programming model. They operate on compact meshlets directly on the GPU, drastically reducing CPU indexing overhead and improving geometric culling efficiency.
What are critical engineering considerations for unity rendering pipeline?
When implementing unity rendering pipeline, prioritize deterministic execution, rigorous error handling, observability metrics, and strict security isolation to maintain production reliability and eliminate latency bottlenecks.
A high-performance render pipeline depends on a balanced, synchronized data flow between host software and underlying hardware silicon. From the initial index fetch in the Input Assembler to early depth culling, parallel fragment dispatch, and compute-driven meshlet amplification, modern real-time rendering demands architectural awareness across every layer of the hardware-software stack.
As game engine architectures shift processing from CPU control loops into GPU-driven compute passes and mesh shaders, systems engineers must design flexible abstraction layers. Whether tuning a custom Scriptable Render Pipeline in Unity or writing bare-metal command allocators in Vulkan, success lies in honoring physical hardware constraints: minimizing memory bus pressure, optimizing cache locality, and keeping GPU execution units saturated with clean, parallel workloads.