
Data durability in distributed systems is rarely a matter of luck, it is a matter of configuration. In the Apache Kafka ecosystem, the mechanism that prevents total data loss during hardware failure is the replication protocol. Without careful tuning of these underlying primitives, production clusters remain fragile, prone to catastrophic data loss during routine maintenance or unexpected node outages.
This article examines the mechanics of the Kafka replication factor, moving beyond surface-level definitions to explore the interaction between In-Sync Replicas, leader election, and the inevitable performance trade-offs that dictate cluster throughput in 2026. Whether you are managing a single-rack deployment or a multi-region global pipeline, understanding these configurations is the difference between a resilient system and an operational bottleneck.
Kafka Replication Fundamentals: Architecture and Design
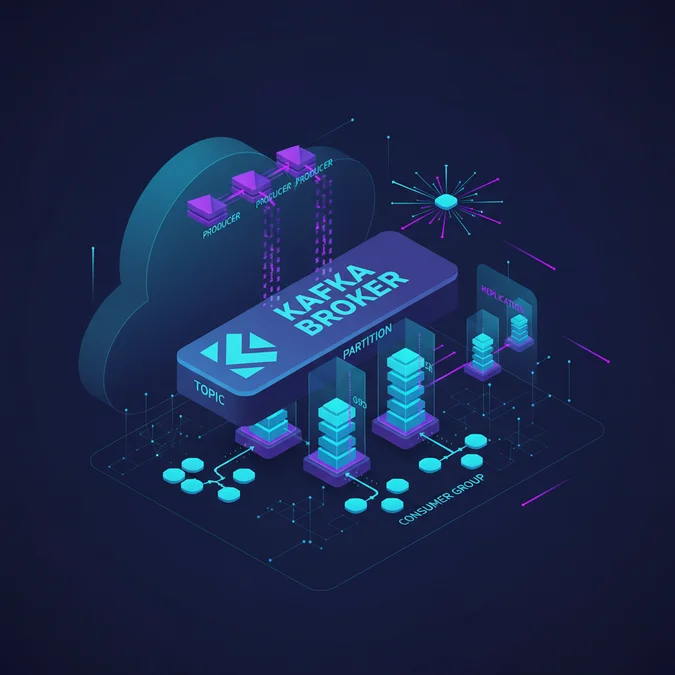
At its core, kafka replication is the process of copying partition logs across multiple brokers to ensure redundancy. Kafka utilizes a leader-follower model where one broker acts as the partition leader, handling all reads and writes, while follower brokers asynchronously or synchronously pull data to maintain parity.
Architectural Note: Kafka does not use a consensus algorithm like Raft for every message; instead, it relies on the concept of ISR (In-Sync Replicas) to determine the subset of followers that are caught up with the leader. This design prioritizes high throughput while maintaining strong consistency guarantees when configured correctly.
The architecture ensures that if a leader fails, the cluster automatically promotes an ISR member to prevent data unavailability.
Understanding the Kafka Replication Factor
The kafka replication factor is a critical configuration parameter that defines the total number of copies maintained for each partition, including the leader itself. Setting this value correctly is the first step toward building a production-ready stream processing pipeline.
| Replication Factor | Failure Tolerance | Storage Overhead | Use Case |
|---|---|---|---|
| 1 | Zero | Low | Non-critical dev/test data |
| 2 | One Broker | Moderate | Low-priority background logs |
| 3 | Two Brokers | High | Standard production SLA |
| 4+ | Three+ Brokers | Very High | Mission-critical, high-availability |
As shown in the table, increasing the factor provides exponential gains in durability but linear increases in resource consumption. A factor of 3 is the industry baseline because it allows for one node to be taken down for maintenance while still retaining a second follower to handle unexpected hardware failures.
Operational Mechanics: ISR and Leader Election
When a leader broker experiences a network partition or hardware crash, the Kafka controller triggers a leader election. The speed and success of this election depend entirely on the health of the ISR set.
- The controller detects the leader failure via Zookeeper or KRaft metadata heartbeat.
- The controller selects a new leader from the current ISR list.
- The new leader begins accepting requests from producers and consumers.
- The remaining brokers update their metadata to point to the new leader.
# Check current ISR status for a specific topic
kafka-topics.sh --bootstrap-server localhost:9092 --describe --topic user-events

# Output snippet:
# Topic: user-events Partition: 0 Leader: 1 Replicas: 1,2,3 Isr: 1,2,3
If the ISR list is empty or smaller than the required min.insync.replicas, the partition becomes unavailable for writes, effectively halting the pipeline to prevent data inconsistency.
Performance Trade-offs: Latency vs Durability
Every increase in replication factor introduces a tax on your hardware. Because the producer must wait for acknowledgment from the ISR set, higher replication increases the round-trip time (RTT) for every produce request.
| Metric | Impact of Higher RF | Root Cause |
|---|---|---|
| Write Latency | Increases | Wait time for follower ACKs |
| Network I/O | Increases | Replication traffic overhead |
| Disk Utilization | Increases | Multiplied log storage |
| Throughput | Decreases | Increased resource contention |
- Checklist for Performance Optimization:
- Ensure network bandwidth supports replication traffic between brokers.
- Use fast NVMe storage to mitigate disk I/O wait times during replication.
- Tune
min.insync.replicasto balance durability against write availability. - Monitor
UnderReplicatedPartitionsmetric to detect performance bottlenecks.
Production Configuration and Monitoring
Managing replicas requires proactive monitoring. A common production failure is the ‘under-replicated partition’ state, which often signals a disk bottleneck or network saturation on follower brokers.
# Monitor under-replicated partitions
kafka-broker-api-versions.sh --bootstrap-server localhost:9092

# Use JMX metrics to track ISR shrinkage
# Metric: kafka.server:type=ReplicaManager,name=UnderReplicatedPartitions- Production Best Practices:
- Always use a replication factor of at least 3 for production topics.
- Implement rack awareness to distribute replicas across physical hardware boundaries.
- Avoid manual reassignment of partitions during peak traffic hours to prevent cluster instability.
- Regularly audit your cluster storage capacity, accounting for the replication factor multiplier.
Frequently Asked Questions
What is the recommended kafka replication factor for production?
For most production environments, a replication factor of 3 is the industry standard. This ensures that the cluster can tolerate the failure of one broker while maintaining at least one follower in sync, providing a balance between high data durability and manageable storage overhead.
How does kafka replication affect cluster throughput?
Kafka replication increases network traffic and disk I/O because every write request must be propagated to follower replicas. Higher replication factors reduce overall write throughput and increase latency, as the producer must wait for acknowledgment from the In-Sync Replicas before the write is considered successful.
Achieving high availability in Kafka is not a set-and-forget task. It requires a deep understanding of how the Kafka replication factor influences the underlying physical infrastructure, from network throughput to disk latency. By prioritizing a replication factor of 3 and maintaining a healthy ISR set, engineering teams can build systems that withstand individual broker failures without compromising data integrity.
As you scale your architecture into 2026, continue to monitor under-replicated partitions as a primary indicator of cluster health. Proactive maintenance and a disciplined approach to rack-aware configuration will ensure your data pipelines remain robust under heavy load.