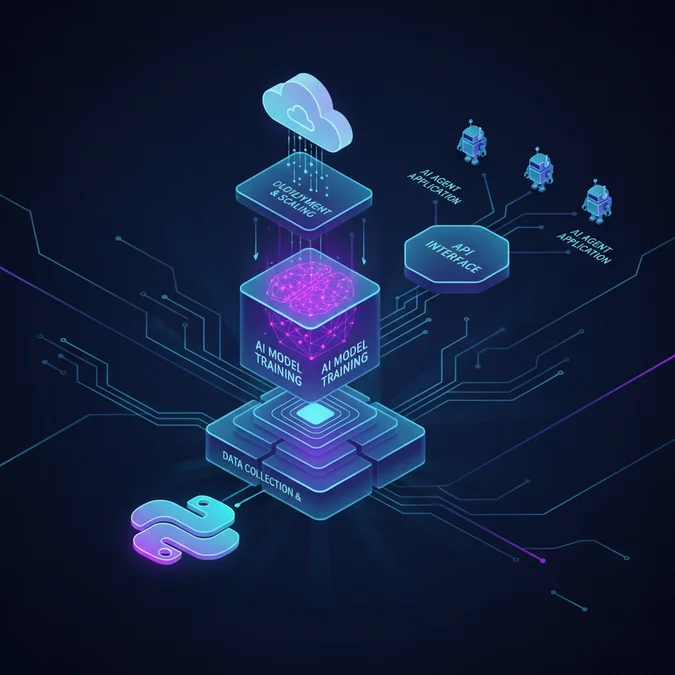

To create an AI agent, you construct a continuous control loop that couples a large language model with structured state management, dynamic tool invocation, and an execution environment. Unlike standard inference calls that map a prompt to a completion in a single round-trip, an autonomous agent iteratively observes environmental inputs, formulates reasoning steps, executes discrete tools, parses deterministic outputs, and halts only when it fulfills a terminal condition or triggers a circuit breaker.
Most production failures occur when development teams treat agents as prompt engineering experiments rather than distributed state machines. Without hard recursion limits, rigorous schema validation, and cycle detection, systems enter runaway tool invocation loops that burn tokens and pollute application state. High-level frameworks often mask these critical failure domains behind brittle abstractions, making real-time debugging nearly impossible under production loads.
This technical guide establishes an engineering blueprint for creating resilient, production-ready AI agents. We dissect bare-metal Python implementations utilizing direct client SDKs, walk step-by-step through building an end-to-end autonomous agent without third-party orchestrators, formalize tool-calling contracts, design hybrid memory architectures, and implement enterprise-grade telemetry and safety controls.
Deconstructing Autonomous Agent Architecture and Topology
Modern autonomous agents operate as state machines driven by a central reasoning engine. At its computational foundation, ai agent design diverges sharply from static sequence-based generative workflows. In a standard chain or sequence, conditional routing is hardcoded by software engineers via deterministic control flows. In contrast, an agent retains dynamic operational autonomy: it inspects its system prompt, evaluates external observations, selects tool calls from an exposed schema registry, and determines its own termination state.
+--------------------------------------------------------------------------+
| USER OBJECTIVE |
+--------------------------------------------------------------------------+
 |
 v
+--------------------------------------------------------------------------+
| REASONING RUNTIME (ORCHESTRATOR) |
| +--------------------+ +-----------------------+ +---------------+ |
| | Short-Term Memory | | System Prompt / State | | Model Context | |
| +--------------------+ +-----------------------+ +---------------+ |
+--------------------------------------------------------------------------+
 | ^
 | Emits Tool Call | Tool Results
 v |
+------------------------------------+ +-----------------------+
| TOOL EXECUTION ENGINE | | OBSERVATION PARSER |
| - Parameter Extraction | | - JSON Validation |
| - Strict Type Validation (Pydantic) | - Error Sanitization|
| - Permission & Budget Checks | | - Context Truncation|
+------------------------------------+ +-----------------------+
 | ^
 +------------------------> [ API / DB / CLI ] ------+
The canonical ai agent pipeline splits operational responsibilities across four distinct layers:
- Cognitive Kernel: The foundational language model responsible for intent disambiguation, planning, and tool argument composition.
- State and Working Memory: The transactional context log preserving user objectives, intermediate scratchpad thoughts, tool execution results, and conversation history.
- Action Execution Engine: The host runtime executing external side effects such as SQL queries, HTTP requests, shell commands, or mathematical compute environments.
- Safety and Telemetry Boundary: The supervisory middleware tracking recursion limits, token consumption, parameter sanity checks, and circuit-breaking logic.
Architectural Rule: Never allow an agent model direct, unmediated write access to sensitive infrastructure. Always isolate tool execution behind an explicit type-validation layer and a role-based execution harness.
Understanding how to use ai agents effectively requires selecting the correct architectural abstraction level for your operational scale. The following decision matrix provides quantitative and architectural criteria for choosing between bare-metal implementations and popular orchestration frameworks.
| Framework / Approach | Invocation Latency Overhead | Memory Footprint | State Machine Observability | Primary Failure Domain | Recommended Production Scale |
|---|---|---|---|---|---|
| Raw Python (Bare Metal) | 0 ms (Direct API) | < 50 MB | Full visibility (Native traces) | Manual state boilerplates | High-throughput, latency-critical systems |
| LangGraph | 5 to 25 ms | 120 to 250 MB | High (Graph-level checkpoints) | Schema migration drift | Complex cyclic state machines |
| CrewAI | 40 to 120 ms | 200 to 450 MB | Moderate (Abstracted events) | Runaway agent-to-agent chatter | Collaborative multi-role prototypes |
| AutoGen | 30 to 90 ms | 180 to 400 MB | Moderate to Low | Non-deterministic routing loops | Research and parallel simulation networks |
Environment Setup and Foundational Requirements for Python Agents
To build a robust agent runtime, you must establish an isolated Python environment that guarantees deterministic dependencies and strict type checking. Exploring how to set up an ai agent begins with configuring strict validation libraries alongside asynchronous model clients.
When mastering how to set up ai development environments, relying on system-level packages invites dependency pollution. We enforce Python 3.11 or 3.12 to take advantage of modernized typing features, structural pattern matching, and optimized asynchronous task execution. This structured approach simplifies how to build ai agents for beginners while retaining enterprise engineering standards.
# Initialize project directory and virtual environment
mkdir agent-runtime-core && cd agent-runtime-core
python3.12 -m venv.venv
source.venv/bin/activate

# Install core dependencies with strict pin-compatible constraints
pip install --upgrade pip
pip install openai==1.40.0 pydantic==2.8.2 python-dotenv==1.0.1 structlog==24.4.0 tenacity==9.0.0
Your local runtime configuration requires an isolated environment file. Create a .env file containing your operational credentials and execution bounds:
# Model Provider Configuration
OPENAI_API_KEY="sk-proj-production-key-here"
OPENAI_MODEL_NAME="gpt-4o"

# Operational Bounds
AGENT_MAX_RECURSION_STEPS=10
AGENT_TOTAL_TOKEN_BUDGET=15000
AGENT_TIMEOUT_SECONDS=45.0
LOG_LEVEL="INFO"
Environment Setup Checklist
- Virtual Environment: Dedicated Python virtual environment activated (Python 3.11+).
- Schema Enforcers: Pydantic v2 installed to guarantee sub-millisecond parameter validation.
- Resilience Tooling: Tenacity configured for retrying model connection failures and transient HTTP drops.
- Structural Logger: Structlog configured to emit structured JSON traces for ingestion into centralized logging pipelines.
- Secret Management: Environment variables isolated from version control via
.gitignorerules.
Tutorial: Build an Autonomous Agent from Scratch in Python
This section provides a complete, bare-metal implementation demonstrating how to create an ai agent without high-level wrapper frameworks. You will understand how to make an ai agent by building a transparent Reason-Action (ReAct) loop that relies exclusively on Python standard libraries, the OpenAI client SDK, and Pydantic.
In this comprehensive ai agent tutorial, we deconstruct the core mechanics so you understand exactly how to build ai agents from scratch. Learning how to create an ai agent from scratch equips software engineers with direct visibility into every model transition, eliminating the hidden latency and black-box abstractions typical of third-party wrappers. Let us build ai agent from scratch python code step-by-step.
Step 1: Define Explicit Tool Schemas
Tools are typed functions mapped to standardized JSON schema specifications. We define deterministic tools alongside a centralized execution registry:
import json
from typing import Any, Callable, Dict, List
from pydantic import BaseModel, Field


class WeatherQueryArgs(BaseModel):
 location: str = Field(description="The city name, e.g. London or San Francisco")


class SQLQueryArgs(BaseModel):
 query: str = Field(description="A read-only SQL query to execute against the analytics store")


def get_current_weather(location: str) -> str:
 """Simulated real-time weather observation."""
 normalized = location.strip().lower()
 if "san francisco" in normalized:
 return json.dumps({"temperature": 62, "condition": "Foggy", "unit": "F"})
 elif "london" in normalized:
 return json.dumps({"temperature": 15, "condition": "Rain", "unit": "C"})
 return json.dumps({"temperature": 72, "condition": "Sunny", "unit": "F"})


def execute_analytics_query(query: str) -> str:
 """Simulated isolated database execution tool."""
 query_clean = query.strip().upper()
 if not query_clean.startswith("SELECT"):
 return json.dumps({"error": "SecurityViolation: Only SELECT operations permitted"})
 return json.dumps([{"user_id": 1024, "status": "active", "mrr": 4200.00}])


TOOL_SCHEMAS: List[Dict[str, Any]] = [
 {
 "type": "function",
 "function": {
 "name": "get_current_weather",
 "description": "Retrieve current weather metrics for a specified municipality.",
 "parameters": WeatherQueryArgs.model_json_schema(),
 },
 },
 {
 "type": "function",
 "function": {
 "name": "execute_analytics_query",
 "description": "Execute a validated read-only SQL SELECT query against customer datasets.",
 "parameters": SQLQueryArgs.model_json_schema(),
 },
 },
]

TOOL_REGISTRY: Dict[str, Callable[.. str]] = {
 "get_current_weather": get_current_weather,
 "execute_analytics_query": execute_analytics_query,
}
Step 2: Construct the Stateful ReAct Loop
When building an ai agent in python, the state machine must execute a cyclically bounded operational loop. The agent evaluates the message history, calls the model, detects tool-call requests, dispatches tools via the registry, appends the results to memory, and repeats until the model produces a final natural language conclusion.
import os
from openai import OpenAI
from openai.types.chat import ChatCompletionMessageToolCall

client = OpenAI(api_key=os.environ.get("OPENAI_API_KEY"))

SYSTEM_PROMPT = """You are an autonomous engineering operations agent.
Resolve user inquiries through systematic step-by-step reasoning.
When missing information, call available tools deterministically.
Reflect critically on tool outputs before returning your final answer.
Always output clean, natural responses once you have sufficient context.
"""


def run_react_agent(
 user_goal: str,
 max_recursion_depth: int = 6,
 model: str = "gpt-4o",
) -> str:
 """Execute an end-to-end autonomous agent loop from scratch."""
 messages: List[Dict[str, Any]] = [
 {"role": "system", "content": SYSTEM_PROMPT},
 {"role": "user", "content": user_goal},
 ]

 recursion_depth = 0

 while recursion_depth < max_recursion_depth:
 recursion_depth += 1
 print(f"[Iteration {recursion_depth}] Invoking cognitive model..")

 response = client.chat.completions.create(
 model=model,
 messages=messages,
 tools=TOOL_SCHEMAS,
 tool_choice="auto",
 temperature=0.1,
 )

 message = response.choices[0].message
 tool_calls: List[ChatCompletionMessageToolCall] = message.tool_calls or []

 # Append the assistant's initial response to conversation state
 messages.append(message)

 # Halting Condition: No tool calls requested implies a completed answer
 if not tool_calls:
 print("[Execution Completed] Goal criteria satisfied.")
 return message.content or ""

 # Execute requested tools deterministically
 for call in tool_calls:
 tool_name = call.function.name
 call_id = call.id
 raw_args = call.function.arguments

 print(f" -> Executing Tool: {tool_name} with payload: {raw_args}")

 if tool_name not in TOOL_REGISTRY:
 observation = json.dumps({"error": f"Tool '{tool_name}' not registered"})
 else:
 try:
 parsed_args = json.loads(raw_args)
 observation = TOOL_REGISTRY[tool_name](**parsed_args)
 except Exception as exc:
 observation = json.dumps({"error": f"Execution failure: {str(exc)}"})

 # Feed observation back into context state for the next reasoning step
 messages.append({
 "role": "tool",
 "tool_call_id": call_id,
 "content": observation,
 })

 raise TimeoutError(f"Circuit breaker triggered: recursion exceeded {max_recursion_depth} steps.")


if __name__ == "__main__":
 # Test query demonstrating autonomous multi-step reasoning
 result = run_react_agent(
 "Check if London is colder than San Francisco right now, and check our user database."
 )
 print("\nAgent Output:\n", result)
Step 3: Execution Output and State Flow Trace
When running this transparent ai agent from scratch implementation, the agent iteratively calls each required tool and reasons sequentially before presenting its final output:
[Iteration 1] Invoking cognitive model..
 -> Executing Tool: get_current_weather with payload: {"location":"London"}
 -> Executing Tool: get_current_weather with payload: {"location":"San Francisco"}
 -> Executing Tool: execute_analytics_query with payload: {"query":"SELECT * FROM users LIMIT 1"}
[Iteration 2] Invoking cognitive model..
[Execution Completed] Goal criteria satisfied.

Agent Output:
London is significantly colder (15°C / 59°F with rain) compared to San Francisco (62°F with fog).
Additionally, the query to the user database confirmed active records, including user ID 1024 with a monthly recurring revenue of $4,200.00.
Tool Integration: Building Dynamic Plugins and Schema Interfaces
A production-ready ai agent plugin architecture must decouple business logic from the model orchestration layer. Rather than writing ad-hoc tool bindings inside string templates, modern ai agents implementation mandates strong contracts backed by runtime reflection and error boundaries.
When an agent model receives invalid schema definitions, it is prone to hallucinating required parameters or producing malformed payloads. To prevent this, software systems implement decorator-based registries that extract JSON schemas dynamically from Python docstrings and Pydantic types.
import functools
import inspect
from typing import Any, Callable, Dict, Type
from pydantic import BaseModel, create_model

class PluginRegistry:
 def __init__(self):
 self._tools: Dict[str, Callable] = {}
 self._schemas: Dict[str, Dict[str, Any]] = {}

 def register(self, pydantic_schema: Type[BaseModel]):
 """Decorator to register deterministic tools with Pydantic validation."""
 def decorator(func: Callable):
 tool_name = func.__name__
 self._tools[tool_name] = func
 self._schemas[tool_name] = {
 "type": "function",
 "function": {
 "name": tool_name,
 "description": inspect.getdoc(func) or "No documentation provided.",
 "parameters": pydantic_schema.model_json_schema(),
 },
 }
 @functools.wraps(func)
 def wrapper(*args, **kwargs):
 return func(*args, **kwargs)
 return wrapper
 return decorator

 def get_tool_specs(self) -> list:
 return list(self._schemas.values())

 def execute(self, tool_name: str, raw_arguments_json: str) -> str:
 """Executes a tool with strict payload validation and isolated error boundaries."""
 if tool_name not in self._tools:
 return json.dumps({"status": "error", "message": f"Plugin {tool_name} not found"})
 try:
 args_dict = json.loads(raw_arguments_json)
 func = self._tools[tool_name]
 result = func(**args_dict)
 return json.dumps({"status": "success", "data": result})
 except json.JSONDecodeError:
 return json.dumps({"status": "error", "message": "Malformed JSON arguments payload"})
 except Exception as err:
 return json.dumps({"status": "error", "message": f"Plugin execution failure: {str(err)}"})

# Example Usage of Structured Plugin Registry
registry = PluginRegistry()

class FileReadInput(BaseModel):
 filepath: str

@registry.register(FileReadInput)
def safe_file_reader(filepath: str) -> str:
 """Safely reads plain text from a sandboxed local file directory."""
 if "." in filepath or filepath.startswith("/"):
 raise PermissionError("Path traversal prohibited by sandboxing policy.")
 return f"Contents of {filepath}: production_metrics_ok=True"
Security Principle: Always treat LLM-generated arguments as unvalidated user input. Execute file, database, or API calls under isolated permissions with sandbox validation before touching infrastructure.
Grounding and Behavioral Tuning: Memory Systems and RAG
When engineers investigate how to train an ai agent, they frequently confuse fine-tuning model weights with runtime architectural steering. In production engineering, fine-tuning modifies tone, stylistic patterns, and baseline compliance. However, learning how to train an agent dynamically requires grounding: feeding the agent deterministic working memory, conversation state, and semantic retrieval-augmented generation (RAG).
Agents require a multi-tiered memory hierarchy to reason coherently over long conversations without blowing past context window limitations:
from typing import List, Dict
import time

class AgentWorkingMemory:
 """Hierarchical buffer managing conversation context and episodic summarization."""
 def __init__(self, max_context_messages: int = 10):
 self.system_prompt: Dict[str, str] = {"role": "system", "content": ""}
 self.short_term_history: List[Dict[str, str]] = []
 self.max_context_messages: int = max_context_messages
 self.episodic_archive: List[Dict[str, Any]] = []

 def set_system_identity(self, identity: str):
 self.system_prompt["content"] = identity

 def append(self, role: str, content: str):
 self.short_term_history.append({"role": role, "content": content})
 if len(self.short_term_history) > self.max_context_messages:
 self._evict_and_archive()

 def _evict_and_archive(self):
 """Evicts oldest interaction step to long-term archive to prevent token blowouts."""
 evicted = self.short_term_history.pop(0)
 self.episodic_archive.append({
 "timestamp": time.time(),
 "message": evicted
 })

 def assemble_context(self, retrieved_knowledge: str = "") -> List[Dict[str, str]]:
 """Compiles the complete dynamic prompt payload with retrieved grounding facts."""
 active_prompt = dict(self.system_prompt)
 if retrieved_knowledge:
 active_prompt["content"] += f"\n\n[RETRIEVED RUNTIME CONTEXT]\n{retrieved_knowledge}"
 return [active_prompt] + self.short_term_history
The table below summarizes the trade-offs between dynamic memory grounding patterns and parametric model fine-tuning when tailoring agent behavior:
| Tuning Dimension | Parametric Fine-Tuning (LoRA / SFT) | Dynamic RAG & External Vector Store | In-Memory Context Scratchpads |
|---|---|---|---|
| Update Latency | Hours to days (Recompilation) | Sub-second (Index write) | Instantaneous (In-memory stack) |
| Hallucination Risk | Moderate to High | Extremely Low (Explicit sources) | Zero (Deterministic state) |
| Token Overhead | Zero tokens used in context | 500 to 2,000 tokens per call | Variable (Grows linearly) |
| Primary Use Case | Domain vocabulary, dialect, and formatting | Real-time proprietary data retrieval | Multi-step ReAct reasoning tracking |
Engineering Production Custom AI Software and Enterprise Safeguards
When transitioning from prototypes to custom ai software, the operational risk shifts from model reasoning accuracy to operational reliability. When building applications with ai agents, teams inevitably face real-world failure modes: non-terminating ping-pong loops, catastrophic token depletion, hallucinated external tool parameters, and upstream API outages.
This ai agent development guide specifies the technical safeguards required to deploy mission-critical agents without human monitoring.
import time
from typing import Any, Dict

class AgentCircuitBreaker:
 """Guards runtime resources against runaway recursive loops and token exhaustions."""
 def __init__(
 self,
 max_steps: int = 8,
 max_tokens_budget: int = 12000,
 timeout_seconds: float = 30.0,
 ):
 self.max_steps = max_steps
 self.max_tokens_budget = max_tokens_budget
 self.timeout_seconds = timeout_seconds
 self.reset()

 def reset(self):
 self.step_count = 0
 self.accumulated_tokens = 0
 self.start_time = time.time()

 def record_step(self, token_usage_increment: int):
 """Asserts boundary limits at every iteration step of the execution loop."""
 self.step_count += 1
 self.accumulated_tokens += token_usage_increment
 elapsed = time.time() - self.start_time

 if self.step_count > self.max_steps:
 raise SystemError(f"Circuit Breaker: Iteration limit exceeded ({self.max_steps})")
 if self.accumulated_tokens > self.max_tokens_budget:
 raise SystemError(f"Circuit Breaker: Token budget depleted ({self.accumulated_tokens})")
 if elapsed > self.timeout_seconds:
 raise TimeoutError(f"Circuit Breaker: Runtime deadline exceeded ({elapsed:1f}s)")
Production Safeguards Matrix
| Failure Mode | Root Cause | Deterministic Mitigation | Telemetry Metric |
|---|---|---|---|
| Ping-Pong Recursion | Tool yields partial error; agent retries identical inputs | Cycle detection algorithm (Arg hash matching) | agent.cycles.detected |
| Context Window Blowout | Verbose database outputs injected directly into memory | Observation summarizer / truncator pipeline | agent.tokens.input_count |
| Parameter Hallucination | Missing schema attributes or loose JSON types | Strict Pydantic type validation with automatic schema reprompting | agent.tools.validation_errors |
| Orphaned Background Tasks | Long-running sub-agent worker hangs without emitting event | Hard thread timeouts with asynchronous cancellation tokens | agent.execution.timeouts |
Production Deployment Checklist
- Recursion Boundaries: Implement hard limits to terminate any agent loop exceeding 8 to 10 iterations.
- Budget Trackers: Enforce strict per-request token consumption budgets to prevent sudden cloud cost spikes.
- Structured Tracing: Capture every prompt, tool parameter, execution response, and timing metric using OpenTelemetry standards.
- Sandboxed Execution: Ensure code execution or shell plugins run within restricted Docker containers or gVisor microVMs.
- Fallback Fallthroughs: Route execution to a human-in-the-loop queue whenever an agent exhausts retry budgets.
Frequently Asked Questions
How hard is it to build an AI agent?
Building a basic proof-of-concept AI agent requires under 100 lines of Python code using standard LLM API tool-calling features. However, developing production-ready systems with state persistence, deterministic tool validation, graceful error recovery, and strict token cost controls requires advanced systems engineering.
What is the difference between an AI workflow and an autonomous AI agent?
An AI workflow executes predefined, hardcoded conditional steps where the path is deterministic. In contrast, an autonomous AI agent dynamically decides which actions to take, selects its own tools sequentially, inspects execution output, and loops until it satisfies a high-level objective.
Should you build an AI agent from scratch or use frameworks like LangGraph?
Building from scratch using bare Python provides granular debugging control and zero dependency overhead. Frameworks like LangGraph, AutoGen, or CrewAI become advantageous when orchestrating complex multi-agent graphs, state rollbacks, human-in-the-loop approvals, and distributed asynchronous memory layers.
How do you prevent an AI agent from entering infinite execution loops?
Prevent runaway agent execution by enforcing strict recursion limits, hard budget constraints on token usage, deterministic timeout windows, and cycle detection algorithms that identify repetitive failed tool invocations before triggering an automatic circuit breaker.
Creating high-performance AI agents requires treating cognitive architectures as distributed systems. By building a transparent ReAct loop from scratch in Python, validating tool interfaces with strict Pydantic models, and implementing hard circuit breakers, you eliminate the fragility inherent in high-level wrapper frameworks. Robust agents are defined not by the models driving them, but by the systemic safeguards, deterministic memory hierarchies, and error-recovery patterns that govern their execution.
Begin by implementing bare-metal control loops on well-defined internal tasks with narrow operational scopes. Once your schema validation boundaries, retry policies, and structured telemetry are stable in staging, scale your architecture toward complex multi-agent graphs and persistent vector storage networks.