
A custom game engine requires an explicit contract with underlying system hardware: deterministic instruction timing, contiguous memory layout, and deterministic GPU resource barrier synchronization. When commercial engines stutter under non-linear memory access patterns or force unwanted runtime overhead onto your simulation, building a bespoke engine layer becomes the only architectural path that offers total control over CPU cache lines and draw-call dispatch pipelines.
Most failed engine attempts collapse under the weight of classical object-oriented anti-patterns: scattered dynamic allocations, deep polymorphic class hierarchies, and unbuffered render API state mutations. Writing an engine in modern C++20 demands abandoning these conventions in favor of Data-Oriented Design (DOD), linear frame arenas, compile-time metadata reflection, and decoupled render graphs targeting explicit graphic backends like Vulkan and DirectX 12.
This systems programming architecture guide details the core components required to construct an engine from the metal up. We will trace the hardware abstraction layer, build a deterministic accumulator-based tick loop, implement zero-allocation custom memory arenas, structure an Entity Component System (ECS) based on sparse sets, and establish a high-throughput modern frame graph pipeline.
Architectural Topology: How Are Game Engines Made Under the Hood?
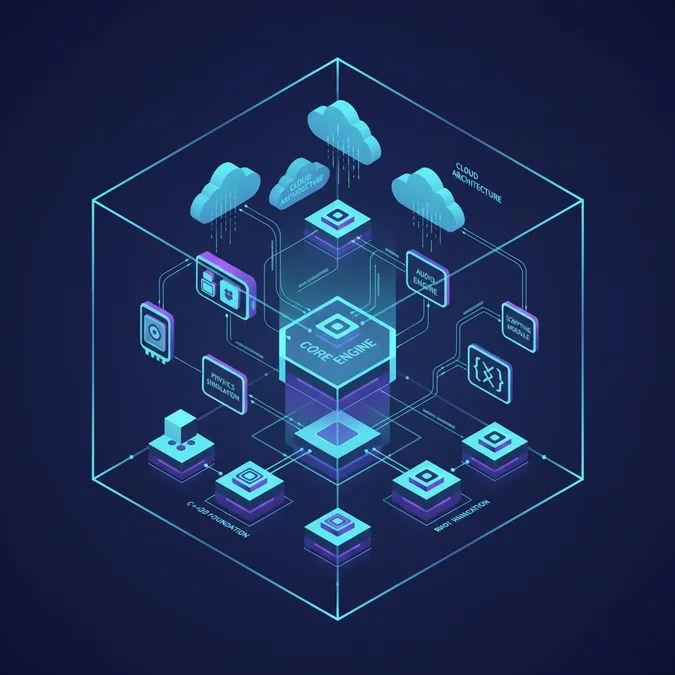
When analyzing how are game engines made, the fundamental architectural boundary separates game-agnostic systems from domain-specific game simulation code. A modern engine is not a massive monolithic executable; it is an orchestrated collection of decoupled static or dynamic libraries bound together by a deterministic lifecycle manager.
+-----------------------------------------------------------------+
| Gameplay Systems / Scripting |
+-----------------------------------------------------------------+
| Scene Graph / ECS | Physics Simulation | Audio Engine |
+-----------------------------------------------------------------+
| Resource & Asset Cache |
+-----------------------------------------------------------------+
| Render Graph / Frame Graph Pipeline Dispatcher |
+-----------------------------------------------------------------+
| Platform Abstraction (PAL) | Memory Arenas | Task Scheduler / Job System |
+-----------------------------------------------------------------+
| Operating System & Hardware Layer |
+-----------------------------------------------------------------+
Solid game engine design balances vertical integration with horizontal module independence. The Platform Abstraction Layer (PAL) normalizes system calls, OS-level windowing, file I/O operations, and hardware-level thread affinity across Windows, Linux, and custom embedded platforms. Operating above the PAL, the Engine Core provides fundamental data structures, memory arenas, SIMD-aligned math libraries, and asynchronous job schedulers that completely sidestep runtime dependencies on the C++ Standard Template Library (STL).
Modern game engine architecture strictly decouples simulation frequency from frame rendering frequency. Game state updates remain purely deterministic, advancing at a fixed frequency, while the graphics module interpolates between current and previous frame transforms as fast as GPU presentation allows.
| Engine Subsystem | Primary Architectural Pattern | L1/L2 Cache Strategy | Typical Execution Budget (60 FPS) |
|---|---|---|---|
| Core Platform & OS | Hardware Abstraction Layer (PAL) | Thread-local storage, warm stack buffers | 0.15 ms |
| Memory Management | Linear Arenas, Pool Allocators | Contiguous 64-byte aligned blocks | 0.05 ms |
| Entity Component System | Sparse Sets / SoA Chunks | Sequential linear reads, prefetch buffers | 1.50 ms |
| Physics Integration | Sub-stepping Sweep / Spatial Hash | Broadphase bounding volume BVH | 4.00 ms |
| Render Graph Engine | Acyclic Graph, Command List Queues | Pooled barrier nodes, descriptor staging | 2.50 ms (CPU recording) |
To prevent architectural rot, inter-module communication must rely on handle-based referencing rather than direct pointer linking. Storing integer IDs (such as 32-bit entity IDs or 64-bit asset GUIDs) guarantees memory relocation safety, facilitates effortless network serialization, and avoids dangling pointer bugs during mass entity deallocations.
Platform Layer and Deterministic Loop: How to Program a Game Engine Core
When examining how to program a game engine core, the heartbeat of the architecture is the main loop. Naive approaches rely on variable delta times (dt) passed straight to movement and integration formulas. This introduces non-deterministic physics bugs, floating-point drift, and erratic gameplay behavior tied directly to fluctuating render frame rates.
Production engines deploy an accumulator-based fixed-timestep game loop. The simulation advances in deterministic temporal slices (e.g. 60 Hz or 120 Hz), while the render pipeline records an alpha interpolation coefficient representing leftover accumulator time to eliminate visible visual judder.
Avoid calculating delta time inside your render loop. Isolate your physics update completely inside a discrete accumulator loop, and treat rendering strictly as a read-only interpolation stage between two cached simulation states.
#include <chrono>
#include <thread>
#include <cstdint>

struct TransformState {
 float x{0.0f};
 float y{0.0f};
};

class EngineCore {
public:
 static constexpr double FIXED_TIMESTEP = 1.0 / 60.0;
 static constexpr double MAX_ACCUMULATOR_FRAME = 0.25; // Prevents spiral of death

 void Run() {
 using Clock = std:chrono:steady_clock;
 auto previous_time = Clock:now();
 double accumulator = 0.0;

 bool is_running = true;
 while (is_running) {
 auto current_time = Clock:now();
 std:chrono:duration<double> elapsed = current_time - previous_time;
 previous_time = current_time;

 double frame_time = elapsed.count();
 if (frame_time > MAX_ACCUMULATOR_FRAME) {
 frame_time = MAX_ACCUMULATOR_FRAME;
 }
 accumulator += frame_time;

 PollPlatformEvents(is_running);

 // Fixed-rate deterministic integration
 while (accumulator >= FIXED_TIMESTEP) {
 m_previous_state = m_current_state;
 SimulatePhysicsFixedStep(m_current_state, FIXED_TIMESTEP);
 accumulator -= FIXED_TIMESTEP;
 }

 // Sub-frame interpolation factor
 const float alpha = static_cast<float>(accumulator / FIXED_TIMESTEP);
 TransformState interpolated_state = BlendStates(m_previous_state, m_current_state, alpha);

 RenderFrame(interpolated_state);
 }
 }

private:
 TransformState m_previous_state{};
 TransformState m_current_state{};

 void PollPlatformEvents(bool& running) {
 // Platform Abstraction Layer (PAL) window event pumps
 }

 void SimulatePhysicsFixedStep(TransformState& state, double dt) {
 state.x += static_cast<float>(10.0 * dt);
 }

 TransformState BlendStates(const TransformState& a, const TransformState& b, float alpha) {
 return TransformState{
 a.x + (b.x - a.x) * alpha,
 a.y + (b.y - a.y) * alpha
 };
 }

 void RenderFrame(const TransformState& render_state) {
 // Issue draw commands using interpolated coordinates
 }
};
This implementation preserves deterministic physics ticks while ensuring smooth rendering regardless of whether the display monitor operates at 60 Hz, 144 Hz, or 240 Hz.
Memory Subsystems: Eliminating Heap Fragmentation with Arenas and Pools
Engine crashes and frame hitching trace back to a common culprit: unconstrained allocations via malloc, free, or C++ default operators new and delete during active gameplay loops. General-purpose heap managers encounter system calls, mutex locking, and heap fragmentation over extended runtime sessions. Understanding how to build a game engine means building custom memory allocators tailored specifically to data lifetimes.
Game engines rely on three dominant allocation tiers:
- Linear Frame Arenas: Monotonically advancing bump allocators for per-frame scratch buffers, command packets, and ephemeral transform calculations. Memory is freed in a single operation at the end of the frame by resetting the offset pointer to zero.
- Pool Allocators: Fixed-size node managers ideal for entities, particle nodes, audio instances, and physics contacts. Pool allocators offer O(1) allocation and deallocation without memory fragmentation.
- Zone/Heap Arenas: Persistent, multi-megabyte blocks reserved during level transitions for enduring world geometry and persistent assets.
#include <cstddef>
#include <cstdint>
#include <new>
#include <utility>

class LinearFrameArena {
public:
 explicit LinearFrameArena(size_t capacity)
: m_capacity(capacity), m_offset(0) {
 m_buffer = new uint8_t[capacity];
 }

 ~LinearFrameArena() {
 delete[] m_buffer;
 }

 LinearFrameArena(const LinearFrameArena&) = delete;
 LinearFrameArena& operator=(const LinearFrameArena&) = delete;

 void* Allocate(size_t size, size_t alignment = alignof(std:max_align_t)) {
 size_t current_address = reinterpret_cast<size_t>(m_buffer + m_offset);
 size_t padding = (alignment - (current_address % alignment)) % alignment;

 if (m_offset + padding + size > m_capacity) {
 return nullptr; // Out of scratch space in this frame
 }

 m_offset += padding;
 void* ptr = m_buffer + m_offset;
 m_offset += size;
 return ptr;
 }

 template <typename T, typename.. Args>
 T* New(Args&&. args) {
 void* memory = Allocate(sizeof(T), alignof(T));
 if (!memory) return nullptr;
 return new (memory) T(std:forward<Args>(args)..);
 }

 void Reset() noexcept {
 m_offset = 0; // Immediate bulk reclamation in O(1)
 }

 [[nodiscard]] size_t GetAllocatedBytes() const noexcept { return m_offset; }
 [[nodiscard]] size_t GetCapacity() const noexcept { return m_capacity; }

private:
 uint8_t* m_buffer{nullptr};
 size_t m_capacity{0};
 size_t m_offset{0};
};
Adopting linear memory management requires enforcing strict memory design practices throughout your engine team:
- [ ] Zero dynamic heap calls (
malloc,new,std:vectorresizes) executed inside the fixed simulation or render pipelines. - [ ] Pre-allocate persistent engine pools during initial boot configuration based on target platform specifications.
- [ ] Align every allocation boundary to 16, 32, or 64 bytes to guarantee support for vectorization via AVX2 or AVX-512 instructions.
- [ ] Reclaim per-frame temporary allocations via single pointer-resets at frame boundaries.
- [ ] Monitor total arena utilization using diagnostic markers to detect buffer saturation before deployment.
Data-Oriented Scene Management: How to Create a Game Engine ECS
When learning how to create a game engine, the classic approach involves building an object-oriented scene graph where an abstract base GameObject inherits from dozens of interfaces like IRenderable, IUpdatable, and ICollidable. In practice, this pattern scatters heap allocations and triggers pointer-chasing across the CPU cache, inducing crippling cache misses.
Data-Oriented Design (DOD) prioritizes hardware cache locality by grouping component data contiguously in memory. Entity Component Systems (ECS) discard deep polymorphic hierarchies entirely:
- Entities: Lightweight 32-bit or 64-bit integer handles containing an index and a generation counter.
- Components: Pure Plain Old Data (POD) structs containing zero polymorphic behavior or dynamic dispatch logic.
- Systems: Stateless functions that process packed, contiguous arrays of matching component types inside sequential loops.
| Metric / Pattern | Polymorphic Scene Graph (OOP) | Sparse Set ECS (DOD) | Archetype ECS (DOD) |
|---|---|---|---|
| Memory Layout | Fragmented heap pointers | Paged component arrays | Contiguous archetype tables |
| L1 Cache Efficiency | Low (frequent cache thrashing) | High (dense payload iterations) | Maximum (zero stride waste) |
| Entity Mutation Cost | Low (pointer reassignment) | O(1) add/remove component | Medium (chunk migration required) |
| Iteration Speed | Slow (virtual function overhead) | Very fast | Blazing (ideal for SIMD pipelines) |
| Structural Complexity | Low | Medium | High |
A Sparse Set architecture provides an optimal balance between structural simplicity, rapid iterations, and constant-time entity additions and removals.
#include <vector>
#include <cstdint>
#include <cassert>

using Entity = uint32_t;
constexpr Entity NULL_ENTITY = 0xFFFFFFFF;

struct PositionComponent {
 float x, y, z;
};

struct VelocityComponent {
 float vx, vy, vz;
};

template <typename T>
class ComponentPool {
public:
 void Insert(Entity entity, const T& component) {
 if (entity >= m_sparse.size()) {
 m_sparse.resize(entity + 1, NULL_ENTITY);
 }
 assert(m_sparse[entity] == NULL_ENTITY && "Component already exists on entity");

 m_sparse[entity] = static_cast<Entity>(m_dense.size());
 m_dense.push_back(entity);
 m_data.push_back(component);
 }

 void Remove(Entity entity) {
 assert(entity < m_sparse.size() && m_sparse[entity]!= NULL_ENTITY);

 Entity index_to_remove = m_sparse[entity];
 Entity last_entity = m_dense.back();
 T last_data = m_data.back();

 // Swap and pop to keep memory packed contiguously
 m_dense[index_to_remove] = last_entity;
 m_data[index_to_remove] = last_data;
 m_sparse[last_entity] = index_to_remove;

 m_dense.pop_back();
 m_data.pop_back();
 m_sparse[entity] = NULL_ENTITY;
 }

 T* GetData(Entity entity) {
 if (entity < m_sparse.size() && m_sparse[entity]!= NULL_ENTITY) {
 return &m_data[m_sparse[entity]];
 }
 return nullptr;
 }

 [[nodiscard]] size_t Size() const noexcept { return m_data.size(); }
 T* RawData() noexcept { return m_data.data(); }

private:
 std:vector<Entity> m_sparse; // Maps Entity ID -> Dense Index
 std:vector<Entity> m_dense; // Maps Dense Index -> Entity ID
 std:vector<T> m_data; // Contiguous component storage
};

// Stateless cache-friendly movement system
void MovementSystem(ComponentPool<PositionComponent>& positions,
 ComponentPool<VelocityComponent>& velocities,
 float dt) {
 PositionComponent* pos_array = positions.RawData();
 VelocityComponent* vel_array = velocities.RawData();
 const size_t total = positions.Size();

 // Direct linear traversal: zero virtual dispatches, prefetch-friendly
 for (size_t i = 0; i < total; ++i) {
 pos_array[i].x += vel_array[i].vx * dt;
 pos_array[i].y += vel_array[i].vy * dt;
 pos_array[i].z += vel_array[i].vz * dt;
 }
}
Graphics Pipeline Integration: Building a Render Graph for Modern APIs
Legacy game engine design layered immediate-mode OpenGL rendering calls directly within gameplay classes. When studying how to make a game engine compatible with modern graphics standards (Vulkan, DirectX 12, Metal), this coupling breaks down entirely. Modern graphics interfaces function as asynchronous low-level command processors requiring manual memory management, explicit resource barriers, pipeline state caches, and ring-buffered descriptor sets.
The modern architectural solution is a Render Graph (also known as a Frame Graph). Instead of immediately recording GPU draw calls, your engine constructs a high-level Directed Acyclic Graph (DAG) during the scene evaluation pass. Each render node declares its explicit resource inputs and outputs.
+-----------------------------------------------------------+
| Render Graph Compiler |
+-----------------------------------------------------------+
| 1. Cull Unreferenced Passes (Dead-Code Stripping) |
| 2. Calculate Physical Image/Buffer Lifetimes |
| 3. Deduce Optimal Memory Aliasing (Transient Overlaps) |
| 4. Generate Minimal Vulkan Pipeline Barriers & Stages |
+-----------------------------------------------------------+
 |
 v
+-----------------------------------------------------------+
| Hardware Execution Submission |
+-----------------------------------------------------------+
| Pass A: Depth Pre-Pass --> Transition to READ |
| Pass B: G-Buffer Base --> Color Write |
| Pass C: Deferred Compute --> Storage Image Transition |
| Pass D: Post-Processing --> Swapchain Presentation |
+-----------------------------------------------------------+
Building a render graph decouples pipeline pass definitions from hardware-specific synchronization. The engine automatically aggregates barriers, overlaps memory allocations for transient textures, and eliminates passes that do not contribute to the final swapchain render target.
#include <string>
#include <vector>
#include <functional>
#include <memory>

using ResourceHandle = uint32_t;

enum class ResourceAccessPattern {
 RenderTargetWrite,
 DepthWrite,
 ShaderReadSampled,
 ComputeStorageWrite
};

struct RenderPassNode {
 std:string name;
 std:vector<std:pair<ResourceHandle, ResourceAccessPattern>> inputs;
 std:vector<std:pair<ResourceHandle, ResourceAccessPattern>> outputs;
 std:function<void()> execution_callback;
};

class RenderGraph {
public:
 RenderPassNode& AddPass(std:string name) {
 return m_nodes.emplace_back(RenderPassNode{std:move(name), {}, {}, nullptr});
 }

 void CompileAndExecute() {
 // 1. Traverse nodes and identify transient resource dependencies
 // 2. Insert Vulkan pipeline barriers: vkCmdPipelineBarrier2KHR
 // 3. Dispatch recorded command buffers cleanly across thread workers
 for (const auto& pass: m_nodes) {
 ExecutePassBarriers(pass);
 if (pass.execution_callback) {
 pass.execution_callback();
 }
 }
 }

private:
 std:vector<RenderPassNode> m_nodes;

 void ExecutePassBarriers(const RenderPassNode& pass) {
 // Resolve pipeline layouts, layout transitions, and hazard synchronizations
 }
};
By building your engine around a Render Graph, your simulation codebase remains completely insulated from vendor-specific graphics calls, enabling support for multi-platform backends without architecture rewrites.
Benchmarking and Verification: Systems Profiling Checklist
A custom engine is only as effective as its worst frame spike. Ensuring steady 60 FPS (16.66 ms) or 120 FPS (8.33 ms) targets requires profiling CPU time budgets, memory allocations, and GPU command submissions continuously during development.
| Engine Stage | Budget Target (60 FPS) | Critical Metric | Common Failure Point |
|---|---|---|---|
| Input & Platform Dispatch | < 0.20 ms | Event polling latency | Message pump blocking on system calls |
| Simulation & Physics | < 5.00 ms | Sub-step iteration count | Unbounded collision pairs, BVH degradation |
| ECS System Iterations | < 2.00 ms | L1 data cache misses | Scattered components, pointer indirection |
| Render Graph Recording | < 3.00 ms | Command list CPU cycles | Redundant state bindings, pipeline swaps |
| GPU Presentation Wait | < 6.46 ms | Swapchain acquisition | GPU-bound fragment shader loads or V-Sync lock |
Integrate instrumental profiling tools like Tracy Profiler directly into your foundational platform layer from day one. Marking scopes across worker threads reveals queue stalls, thread contention, and cache thrashing before they solidify into systemic architectural problems.
- [ ] Tracy Profiler or Superluminal hooks installed across every core system tick and command queue.
- [ ] Custom allocators instrumented to trigger assertions if an allocation occurs within hot per-frame code loops.
- [ ] Memory high-water marks and arena capacities logged and tracked after major scene transitions.
- [ ] Fixed simulation ticks isolated and verified against floating-point drift across both Clang and MSVC toolchains.
- [ ] Render graph verified via the Vulkan Validation Layers with zero synchronization hazard warnings.
- [ ] Stress-test benchmark scenes executing 50,000 dynamic components to validate data-oriented throughput under peak loads.
Frequently Asked Questions
What programming language is best when learning how to make a game engine?
C++ remains the industry standard when learning how to make a game engine due to fine-grained memory control, zero-cost abstractions, and direct hardware API support. Rust is an increasingly viable alternative offering memory safety guarantees without garbage collection pauses, while Zig provides lightweight systems-level control.
How long does it take to program a custom game engine?
A functional 2D engine with windowing, rendering, and input takes approximately one to three months when learning how to program a game engine. A production-ready 3D engine with Vulkan rendering, ECS, and custom memory management typically requires one to two years of focused systems engineering effort.
Why should engineers choose custom game engine design over Unity or Unreal?
Custom game engine design eliminates unnecessary runtime bloat, guarantees deterministic simulation, and offers total control over memory layouts and hardware scheduling. It suits specialized performance profiles, proprietary toolchains, custom hardware targets, and deep foundational systems programming education.
Is it realistic for an indie developer to build a modern game engine?
Yes, provided the scope is strictly constrained to the needs of a specific game. Learning how to build a game engine with a targeted 2D or streamlined 3D feature set avoids the general-purpose complexity of commercial tools while delivering superior runtime efficiency and zero licensing fees.
Building a high-performance game engine from scratch requires rejecting high-level dynamic abstractions in favor of deterministic hardware alignment. By constructing an accumulator-based platform loop, using custom linear memory arenas to eliminate heap thrashing, leveraging cache-coherent Entity Component Systems, and sequencing modern GPU passes via an explicit Render Graph, you build an architecture capable of sustained frame rates and predictable throughput.
Begin your engine with a minimal platform abstraction, a linear scratch allocator, and a solid logging harness. Isolate each subsystem with strict compile-time boundaries, profile every millisecond of execution time, and extend your custom toolchain deliberately around the technical requirements of your project.