
When architecting high-throughput data pipelines, the choice between traditional message queuing and distributed event streaming often creates a significant bottleneck in long-term system evolution. Engineers frequently struggle to reconcile the strict transactional requirements of legacy brokers with the massive, append-only throughput of modern streaming platforms. Understanding the fundamental mechanics of how these systems handle state is critical for avoiding architectural rework in production.
This article cuts through the noise, providing a technical breakdown of the performance trade-offs, operational overhead, and implementation patterns required to choose between Apache MQ and Kafka in 2026. By focusing on commit log semantics versus ephemeral queue delivery, we aim to provide a definitive framework for your next infrastructure decision.
Architectural Foundations: Message Queue vs Kafka Logic
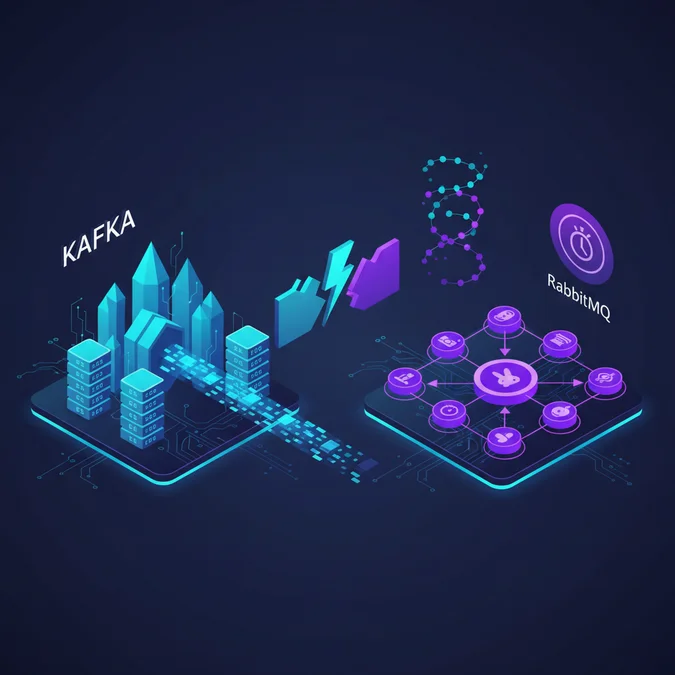
The distinction between message queue vs kafka lies in their core data structures. Traditional message queues, such as ActiveMQ or IBM MQ, function as smart brokers designed for point-to-point delivery and transactional integrity. Their primary objective is the reliable hand-off of individual messages from a producer to a single consumer, followed by immediate deletion upon acknowledgment.
In contrast, Kafka operates as a distributed, partition-aware commit log. It does not delete messages upon delivery; instead, it persists them for a configurable retention period, allowing multiple consumers to read the same data at their own pace.
| Feature | Traditional Message Queue | Apache Kafka |
|---|---|---|
| Data Storage | Ephemeral (Broker-resident) | Persistent (Distributed Log) |
| Delivery Pattern | Point-to-Point / Pub-Sub | Pub-Sub (Log-based) |
| Consumer State | Managed by Broker | Managed by Client (Offsets) |
| Throughput | Moderate (High latency per msg) | High (Sequential I/O) |
Performance Benchmarks: Apache MQ vs Kafka Throughput
When evaluating apache mq vs kafka under high-velocity ingestion, the primary differentiator is how each system interacts with disk I/O. Kafka leverages the OS page cache and sequential disk writes, allowing it to handle millions of events per second with minimal latency overhead. Traditional MQ systems often incur performance penalties due to the overhead of per-message acknowledgment cycles and complex transaction logs.
| Metric | ActiveMQ (Standard) | Kafka (KRaft Mode) |
|---|---|---|
| Latency (p99) | ~10-50ms | ~2-5ms |
| Throughput (msg/sec) | 10k – 50k | 1M+ |
| Scaling | Vertical / Complex Cluster | Horizontal (Partitioning) |
| Backpressure | Broker-side Flow Control | Consumer-side Pull Model |
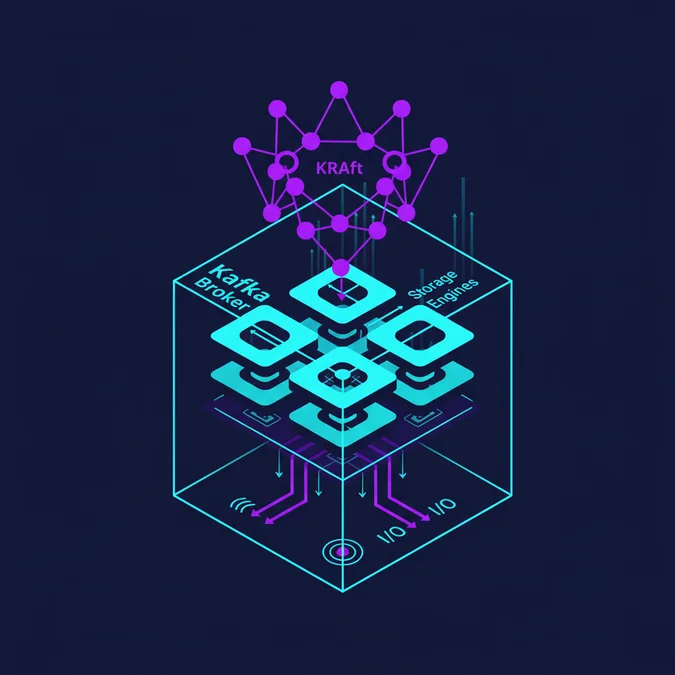
In 2026, the shift toward KRaft mode has removed the dependency on Zookeeper, significantly reducing the metadata latency that previously hampered Kafka cluster recovery times. This makes Kafka significantly more performant for horizontal scaling scenarios compared to legacy MQ configurations.
Code Implementation: Side by Side Kafka MQ Patterns
Implementing kafka mq patterns requires a fundamental shift in mindset from imperative command-based delivery to declarative log-based processing. The following examples illustrate the difference in how producers interact with each system.
// Traditional MQ: Sending a message with acknowledgment
MessageProducer producer = session.createProducer(queue);
TextMessage message = session.createTextMessage("Event Payload");
producer.send(message); // Wait for broker ack

// Kafka: Appending to a partition log
ProducerRecord<String, String> record = new ProducerRecord<>("events", "key", "payload");
producer.send(record, (metadata, exception) -> {
 if (exception == null) System.out.println("Offset: " + metadata.offset());
}); // Non-blocking async append
Note that the Kafka pattern is inherently asynchronous. Consumers in Kafka are responsible for maintaining their own offset pointers, whereas MQ consumers are passive recipients of push-based deliveries.
Production Decision Matrix: Choosing the Right Tool
Deciding between mq vs kafka should be driven by the specific requirements of your event pipeline. Use this checklist to validate your architecture:
- Transactional Integrity: Do you require JTA/XA transactions across multiple resources? Use an MQ.
- Message Replayability: Do you need to re-process historical data after a bug fix? Use Kafka.
- Ordering Requirements: Kafka guarantees order only within a partition. If you need global ordering across thousands of consumers, MQ patterns may be simpler to implement.
- Throughput Volume: For millions of events per second, Kafka is the industry standard for 2026.
- Retention Policies: Does the data need to live for days or weeks? Kafka’s tiered storage is built for this; MQ systems will choke on large message backlogs.
Factors That Affect Development Cost
- Operational overhead of cluster management
- Storage costs for long-term message retention
- Network egress requirements for cross-region replication
- Licensing and support models for enterprise distributions
Cost varies significantly based on whether you opt for self-managed open-source deployments or fully managed cloud-native services.
Frequently Asked Questions
Is Kafka technically a message queue?
While Kafka functions as a distributed event streaming platform, it can perform message queue tasks. Unlike a traditional message queue vs kafka implementation, Kafka persists data to a distributed log, allowing for message replayability and multi-consumer support, whereas traditional queues typically delete messages after successful delivery.
When should I prefer Apache MQ over Kafka?
You should prefer Apache MQ when your architecture requires strict transactional integrity, complex routing patterns, or simple point-to-point communication. It excels in environments where low latency for individual messages is prioritized over the massive, high-throughput batch processing capabilities that define the Kafka ecosystem.
What is the primary difference in message delivery for these systems?
The core difference lies in storage. MQ systems focus on ephemeral message passing and acknowledgment cycles. Kafka uses a commit log architecture, meaning messages are stored on disk for a retention period, enabling consumers to track their own offsets and re-read historical data as needed.
Which system is easier to manage in a cloud-native environment?
Kafka is generally better suited for cloud-native environments due to its partition-based scalability and KRaft-based management. While MQ systems are reliable, they often require more manual effort to scale horizontally compared to the elastic nature of modern Kafka deployments using tiered storage.
The choice between Apache MQ and Kafka is not about which tool is better, but about which paradigm matches your data lifecycle requirements. If your workload involves complex routing, strict transactional hand-offs, and relatively low throughput, traditional MQ systems remain highly effective. However, for modern, event-driven architectures that demand high throughput, horizontal scalability, and the ability to replay historical data, Kafka has become the de facto standard.
As you move to production, ensure that your consumer groups are properly sized and that your partition strategy aligns with your throughput goals. For teams managing Kafka at scale, adopting KRaft and leveraging cloud-native tiered storage will significantly reduce operational friction in 2026.