
A Kafka broker is an event streaming server engineered to ingest, persist, and distribute high-throughput record streams via append-only commit logs. Rather than managing volatile consumer state in application memory, each broker delegates data caching directly to the operating system page cache, dispatching sequential byte buffers across network sockets with kernel-level zero-copy efficiency.
When an unoptimized cluster encounters a spike of hundreds of thousands of concurrent writes, misconfigured network threads, suboptimal segment rollover limits, or JVM garbage collection pauses can cascade into broker-wide request queue starvation. Understanding the underlying internal mechanisms of the broker is what separates unstable clusters from resilient, low-latency streaming infrastructure capable of sustaining millions of events per second.
This architectural breakdown explores how a modern broker operates under the hood. We dissect the request pipeline, physical log segment mechanics, zero-copy data transfer, partition replication lifecycles, KRaft metadata quorums, and the concrete kernel configurations required to operate high-throughput clusters in 2026.
Kafka Broker Architecture and Distributed Topology
At its physical layer, an Apache kafka broker operates as an independent node within a coordinated cluster. Rather than acting as a compute-heavy application server, the broker is designed around a singular, highly optimized design principle: sequential disk I/O combined with stateless client interaction. The broker does not track which individual consumer has read which message; instead, consumers maintain their own positional state through committed offsets stored in an internal topic.
To handle thousands of concurrent client connections without saturating system threads, the broker relies on a non-blocking Java NIO network pipeline centered on a Reactor pattern. An Acceptor thread listens for incoming TCP handshakes and distributes connections across a pool of network processor threads (configured via num.network.threads). These network threads read raw data frames off the wire, parse them into discrete request objects, and place them into a centralized, bounded request queue.
+-----------------------------------------------------------------------------------+
| KAFKA BROKER NODE |
| |
| +-------------------+ +--------------------------------------------------+ |
| | Acceptor Thread | ---> | Network Threads (num.network.threads) | |
| +-------------------+ +--------------------------------------------------+ |
| | |
| v |
| +------------------------+ |
| | Request Queue (FIFO) | |
| +------------------------+ |
| | |
| v |
| +-----------------------------------------------------------------------------+ |
| | I/O Worker Threads (num.io.threads) | |
| | Reads/Writes to Storage Engine, ISR Verification, Purgatory Scheduling | |
| +-----------------------------------------------------------------------------+ |
| | |
| v |
| +-----------------------------------------------------------------------------+ |
| | Storage Engine (OS Page Cache <---> Segment Logs.log /.index /.timeindex) | |
| +-----------------------------------------------------------------------------+ |
+-----------------------------------------------------------------------------------+
From the request queue, a separate pool of I/O worker threads (governed by num.io.threads) unqueues incoming operations. These operations range from ProduceRequest and FetchRequest to cluster metadata inquiries. If an operation requires waiting, such as a produce request with acks=all awaiting acknowledgment from follower replicas, the I/O thread offloads the request to a hierarchical timing wheel known as the Purgatory. This unblocks the I/O worker immediately, enabling the broker to maintain high throughput even under slow network or disk conditions.
The separation of network I/O from storage I/O prevents slow disk access or replica latency from halting socket read/write operations, guaranteeing that request latency stays deterministic across heterogeneous client workloads.
The table below summarizes the core internal subsystems operating within every active broker process:
| Subsystem | Primary Configuration Parameter | Core Function | Performance Bottleneck |
|---|---|---|---|
| Socket Acceptor & Processors | num.network.threads |
TCP termination, frame serialization, deserialization | CPU context switching, epoll saturation |
| Request Channel | queued.max.requests |
Bounded FIFO queue buffering requests for workers | Heap memory exhaustion if queue fills |
| I/O Worker Pool | num.io.threads |
Executes storage commits and manages partition logic | Disk I/O latency, lock contention |
| Delayed Operation Purgatory | Internal Watcher | Maintains asynchronous uncommitted request state | JVM heap footprint under replica lag |
| Replica Manager | replica.fetcher.threads |
Coordinates leader tracking and follower fetch loops | Inter-broker network saturation |
| Log Manager | log.dirs |
Active segment rollover, retention, index flushes | File descriptor limits, I/O IOPS limits |
Cluster Coordination: Managing Partitions Across Multiple Kafka Brokers
When scalable data streams exceed the storage or compute capacity of a single machine, topic partitions are distributed horizontally across multiple kafka brokers. Each topic is partitioned into an ordered, immutable sequence of records, and each individual partition is replicated across a designated set of nodes defined by the replication factor.
For every partition, one broker is elected as the Leader, while all remaining assignees become Followers. Clients write solely to and (by default) read solely from the partition leader. Followers function as internal consumers: they issue continuous FetchRequest calls over internal network listeners to synchronize data sequentially from the leader log onto their local disks.
| Partition State Attribute | Role in Cluster Coordination | Operational Threshold |
|---|---|---|
| Leader Broker | Serves read and write operations; maintains High Watermark | Fails over to follower within milliseconds upon heartbeat loss |
| In-Sync Replicas (ISR) | Set of active brokers fully caught up to the leader log end offset | Dropped if lag exceeds replica.lag.time.max.ms (default: 30000) |
| Log End Offset (LEO) | Highest record offset written to the physical segment files | Advances immediately upon local leader write completion |
| High Watermark (HW) | Highest offset replicated to all members of the ISR | Only records below HW are visible to consumer clients |
A follower is designated as an In-Sync Replica (ISR) as long as it continuously fetches records within the interval defined by replica.lag.time.max.ms. If a follower broker undergoes a hardware fault, disk stall, or network partition, the leader ejects the failing node from the ISR pool. Once ejected, produce requests with acks=all continue processing unhindered, provided the number of remaining ISR members satisfies min.insync.replicas.
When engineering clusters across distributed cloud regions or on-premises availability zones, rack awareness prevents catastrophic failure scenarios. By configuring broker.rack on each node, the cluster partition allocator ensures that partition replicas are distributed across physically isolated infrastructure racks or data center zones.
- Check broker failure domains: Ensure all instances assigned to a common virtualization rack or availability zone share an identical
broker.rackproperty inserver.properties. - Validate replica distribution: Use administrative tooling to verify that no individual partition has both its leader and secondary replicas positioned on the same physical fault domain.
- Enforce minimum in-sync limits: Set
min.insync.replicas=2alongsidereplication.factor=3so writes are rejected if double-broker failures drop active replicas below data safety baselines. - Prevent unclean elections: Verify that
unclean.leader.election.enableremains set tofalsein production to eliminate silent data loss during multi-broker drops.
Under the Hood: Log Segments, Indices, and Zero-Copy I/O Mechanics
The storage layout of a broker avoids random disk operations by organizing partition data into sequential, append-only log segments. A partition directory on disk consists of multiple segment files, each composed of a base data file (.log), an offset-to-physical-position index (.index), and a timestamp-to-offset index (.timeindex).
Data is written exclusively to the currently open active segment. When this segment reaches the maximum byte limit (log.segment.bytes, defaulting to 1GB) or time threshold (log.roll.hours), the broker rolls the segment, closes it to future writes, and creates a new active file. Because older segments are completely immutable, they can be compacted or deleted during retention cleanup cycles without acquiring write locks on incoming message flows.
/var/lib/kafka/data/telemetry-events-0/ (Topic: telemetry-events, Partition: 0)
├── 00000000000000000000.index (Sparse offset index)
├── 00000000000000000000.log (Physical commit log: offsets 0 to 418902)
├── 00000000000000000000.timeindex (Sparse timestamp index)
├── 00000000000000418903.index (Active segment sparse index)
├── 00000000000000418903.log (Active commit log receiving appends)
├── 00000000000000418903.timeindex (Active segment timestamp index)
└── leader-epoch-checkpoint (Tracks partition leader transition boundaries)
Rather than recording an index entry for every individual message, the broker utilizes sparse memory-mapped indices. By default (governed by index.interval.bytes=4096), an entry is written to the .index file only after every 4KB of raw log data. To locate an arbitrary offset, the broker conducts a fast binary search over the memory-mapped index to identify the nearest physical byte offset, followed by a minimal sequential scan through the .log file.
When a consumer fetches data, traditional application servers read the data from disk into a kernel buffer, copy it into user-space application memory, copy it back into a kernel socket buffer, and finally push it out to the network interface card (NIC). This path incurs four context switches and three memory copies.
TRADITIONAL APPLICATION I/O (4 context switches, 3-4 memory copies):
Disk -> OS Page Cache -> JVM User Space -> Socket Buffer -> NIC Buffer

KAFKA ZERO-COPY SENDFILE (2 context switches, 0 CPU user-space copies):
Disk -> OS Page Cache -----------------------------------> NIC Buffer
 (via DMA Transfer)
Kafka bypasses this latency through the Linux sendfile() system call, implemented in Java via FileChannel.transferTo(). This mechanism allows the broker to transfer bytes directly from the OS page cache to the network protocol engine via direct memory access (DMA), eliminating memory duplication into the JVM heap entirely.
By bypassing the JVM heap during read operations, brokers completely evade garbage collection overhead during message delivery, allowing read performance to scale linearly with the network interface bandwidth.
The following configuration sample illustrates segment sizing and index controls in server.properties:
# Storage Segment and Index Mechanics
log.segment.bytes=1073741824
log.roll.hours=168
log.index.interval.bytes=4096
log.index.size.max.bytes=10485760

# OS Page Cache Flush Policy (rely on OS background writeback for performance)
log.flush.interval.messages=9223372036854775807
log.flush.interval.ms=9223372036854775807
log.flush.scheduler.interval.ms=2000
Consensus Evolution: KRaft Metadata Quorum vs ZooKeeper Coordination
Historically, Kafka clusters relied on an external Apache ZooKeeper quorum to track cluster membership, elect partition leaders, and maintain access control lists (ACLs). This bifurcated architecture introduced severe operational bottlenecks: metadata changes required dual synchronization between the ZooKeeper ensemble and the active cluster controller, leading to state desynchronization, slow broker restart cycles, and hard limits on total partition counts per cluster.
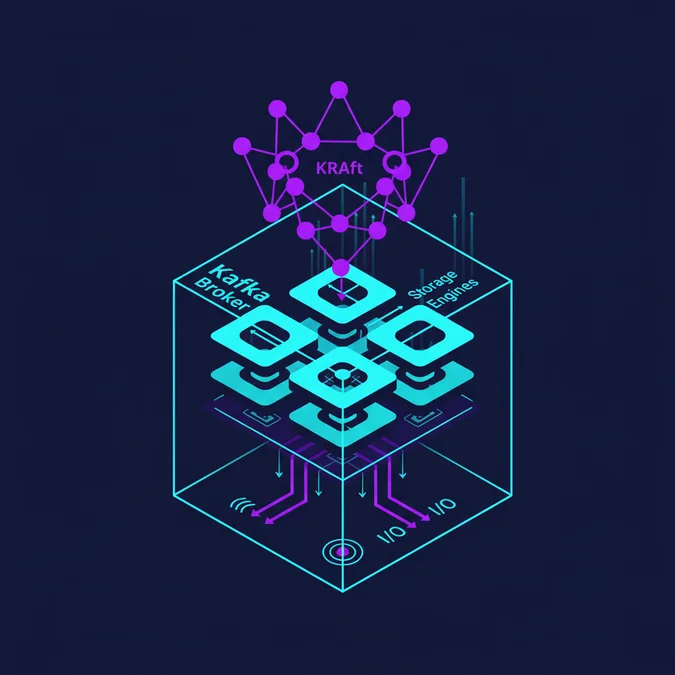
With the standardization of KRaft (Kafka Raft Metadata Mode), metadata management is integrated directly within the brokers themselves. Instead of external watch nodes, cluster state is logged as a specialized internal, replicated topic named @metadata. A designated subset of brokers act as the KRaft Controller Quorum, utilizing an event-driven consensus state machine based on the Raft algorithm.
| Architectural Vector | ZooKeeper-Based Coordination | KRaft Consensus Quorum (Modern Standard) |
|---|---|---|
| Metadata Storage | External hierarchical znodes | Internal append-only @metadata partition log |
| Controller Architecture | Single elected broker with external watches | Active Controller Leader backed by hot-standby Quorum |
| Partition Scaling Limits | Approximately 200,000 partitions per cluster | 1,000,000+ partitions per cluster |
| Failover Recovery Time | Tens of seconds to minutes while scanning znodes | Sub-second failover via in-memory log replay |
| Security Footprint | Dual security models (ZooKeeper SASL/Digest + Kafka) | Unified Kafka protocol listeners and mTLS validation |
| External Dependencies | Requires dedicated JVM fleet running ZooKeeper | Zero external processes; self-contained broker runtime |
In KRaft mode, the Active Controller ingests metadata alterations, appends them to the active metadata log, and replicates records across the standby controllers. All regular brokers poll the Active Controller using standard Fetch requests, continuously applying state increments directly into an in-memory cache.
Because state changes are propagated as deterministic record streams, controller failover no longer requires rebuilding cluster state by scanning external directory structures. The new controller leader merely validates its existing replicated in-memory log snapshot and resumes immediate command execution, lowering failover times from minutes to sub-second windows.
Production Hardware Sizing and server.properties Configuration Blueprint
Operating Kafka brokers in production environments requires deliberate hardware capacity planning. Sizing a broker must balance three distinct layers: disk I/O characteristics, physical network interface limits, and RAM allocation split between the JVM heap and the Linux kernel page cache.
A widespread anti-pattern is assigning large JVM heaps to Kafka brokers. Because brokers rely on the kernel page cache for zero-copy read paths, large heap sizes waste physical memory and trigger disruptive Stop-The-World garbage collection cycles. A production heap allocation of 6GB to 8GB utilizing the G1 garbage collector is sufficient for almost all production workloads, with the remaining 85% or more of system RAM reserved for the kernel page cache.
To size disk throughput per broker, apply the following formula to account for consumer replication and producer fan-out:
Total Broker Disk Write Throughput = Target Ingestion Rate * Replication Factor
Total Broker Network Ingress = Target Ingestion Rate + Inter-Broker Replica Ingress
Total Broker Network Egress = (Target Ingestion Rate * Active Consumers) + Replica Egress
Below is a production-grade server.properties blueprint engineered for high-throughput, low-latency deployments:
# ==============================================================================
# KRAFT IDENTITY & ROLES (Node acting as both Broker and Controller)
# ==============================================================================
node.id=1
process.roles=broker,controller
controller.quorum.voters=1@kafka1.internal:9093,2@kafka2.internal:9093,3@kafka3.internal:9093

# ==============================================================================
# SOCKET & THREADING POOLS
# ==============================================================================
listeners=PLAINTEXT://kafka1.internal:9092,CONTROLLER://kafka1.internal:9093
inter.broker.listener.name=PLAINTEXT
controller.listener.names=CONTROLLER

num.network.threads=8
num.io.threads=16
queued.max.requests=10000
socket.send.buffer.bytes=1048576
socket.receive.buffer.bytes=1048576
socket.request.max.bytes=104857600

# ==============================================================================
# STORAGE, REPLICATION & ISR
# ==============================================================================
log.dirs=/var/lib/kafka/data-nvme
num.partitions=8
default.replication.factor=3
min.insync.replicas=2
replica.lag.time.max.ms=30000
replica.fetch.max.bytes=5242880
replica.fetch.response.max.bytes=10485760

# ==============================================================================
# LOG SEGMENTATION & RETENTION
# ==============================================================================
log.segment.bytes=1073741824
log.retention.hours=72
log.retention.check.interval.ms=300000
log.cleaner.enable=true
log.cleaner.threads=4
Follow this deployment sequence to prepare the operating system and initialize the node runtime:
- Tune kernel virtual memory: Modify
/etc/sysctl.confby settingvm.swappiness=1andvm.dirty_ratio=40alongsidevm.dirty_background_ratio=10to force proactive background page cache flushes without blocking synchronous write routines. - Set filesystem mount options: Mount non-volatile memory (NVMe) solid-state storage with the
XFSfilesystem using thenoatimeflag to prevent metadata write overhead whenever log segments are read by consumers. - Increase OS file descriptor limits: Set
nofilelimits to at least1000000in/etc/security/limits.conf, because each partition segment, index, and incoming network connection occupies a distinct file handle. - Configure JVM parameters: Export
KAFKA_JVM_PERFORMANCE_OPTS="-Xms8g -Xmx8g -XX:+UseG1GC -XX:MaxGCPauseMillis=20 -XX:InitiatingHeapOccupancyPercent=45"prior to daemon execution. - Format the KRaft storage directory: Generate a cluster UUID using
kafka-storage.sh random-uuid, then runkafka-storage.sh format -t <cluster-uuid> -c /etc/kafka/server.propertiesbefore booting the service.
Triage Runbook: Under-Replicated Partitions and Storage Saturation
When operating a production broker fleet, automated health checks must monitor for two primary incident classes: Under-Replicated Partitions (URPs) and local disk exhaustion. An Under-Replicated Partition indicates that one or more follower brokers have dropped out of the ISR, reducing redundancy and threatening cluster durability.
To locate under-replicated partitions rapidly across the cluster, execute the Kafka topics administrative script with the under-replicated filter flag:
/opt/kafka/bin/kafka-topics.sh \
 --bootstrap-server kafka1.internal:9092 \
 --describe \
 --under-replicated-partitions
If specific partitions appear persistently, evaluate the network bandwidth between the leader broker and the assigned followers, check for garbage collection pauses on follower nodes, and verify broker logs for disk write timeout warnings (such as CorruptRecordException or I/O disk stall).
If a single broker experiences an unplanned local disk saturation event (>90% capacity), immediate action is required to avoid an unrecoverable crash of the storage engine. Execute this dynamic configuration command to reduce the retention window on the highest-volume topics residing on the saturated node:
# Temporarily reduce retention to 12 hours on high-throughput ingress topics
/opt/kafka/bin/kafka-configs.sh \
 --bootstrap-server kafka1.internal:9092 \
 --entity-type topics \
 --entity-name telemetry-events \
 --alter \
 --add-config retention.ms=43200000

# Trigger immediate retention evaluation cycle
/opt/kafka/bin/kafka-topics.sh \
 --bootstrap-server kafka1.internal:9092 \
 --topic telemetry-events \
 --alter \
 --config segment.ms=3600000
Follow this triage checklist during broker operational anomalies:
- Inspect file descriptor exhaustion: Run
lsof -p $(pgrep -f kafka) | wc -lto verify that the broker process has not reached the operating system file handle cap. - Analyze JVM pause cycles: Cross-reference the broker’s JMX metric
java.lang:type=GarbageCollector,name=G1 Young Generationto ensure stop-the-world pauses are remaining under 50ms. - Track Request Handler idle ratio: Monitor
kafka.server:type=KafkaRequestHandlerPool,name=RequestHandlerAvgIdlePercent. If this metric drops below 0.3 (30% idle), scale upnum.io.threadsor add brokers. - Review network processor queues: Track
kafka.network:type=RequestChannel,name=RequestQueueTimeMs. Spikes above 100ms indicate network thread pool saturation or client packet serialization stalls. - Graceful decommissioning: Before terminating a problematic broker, trigger partition reassignments using
kafka-reassign-partitions.shto shift replica loads cleanly to alternative nodes without dropping cluster ISR counts below safe thresholds.
Frequently Asked Questions
What is the primary role of an Apache Kafka broker?
An Apache Kafka broker is a server node responsible for ingesting, storing, and serving record streams. It writes records to append-only disk segments, manages topic partition leadership, serves consumer fetch requests, and participates in cluster replication protocols.
How do multiple Kafka brokers balance topic partition loads?
Multiple Kafka brokers distribute partition replicas across the cluster using round-robin assignment and rack awareness algorithms. Each partition has one leader broker handling read and write requests, while follower brokers asynchronously pull data to maintain in-sync replica status.
How much RAM does a Kafka broker require in production?
A production Kafka broker typically runs with a modest 6GB to 8GB JVM heap to minimize garbage collection pauses. Remaining host memory (32GB to 128GB+) is dedicated entirely to the OS page cache for zero-copy read caching.
How does a Kafka broker implement zero-copy data transfers?
Kafka brokers use the Linux sendfile() system call. This transmits data directly from the kernel page cache to the network socket descriptor, bypassing JVM heap allocations and context switches between kernel space and user space.
A Kafka broker is far more than a simple messaging queue. By relying on append-only segment storage, memory-mapped sparse indices, and the Linux kernel zero-copy sendfile pipeline, brokers turn physical hardware into high-throughput, low-latency streaming infrastructure. The elimination of ZooKeeper in favor of native KRaft metadata consensus further strengthens resilience, enabling sub-second controller failovers and multi-million partition scale.
Achieving predictable production stability demands that engineering teams move beyond default settings. Sizing JVM heaps conservatively to give physical memory back to the OS page cache, configuring robust network and I/O thread worker pools, and enforcing rack-aware partition allocation guarantees that your cluster can absorb severe hardware faults without dropping events or violating service level agreements.