
A production marketing script connected to an unconstrained foundation model burns through $40,000 in ad spend within three hours because a loose prompt misinterpreted a seasonal bidding parameter. The failure stems from treating a generative text model as an operational engine. Wrapping an LLM in a single completion call lacks the state persistence, deterministic validation, and failure-domain isolation required to operate inside live revenue channels.
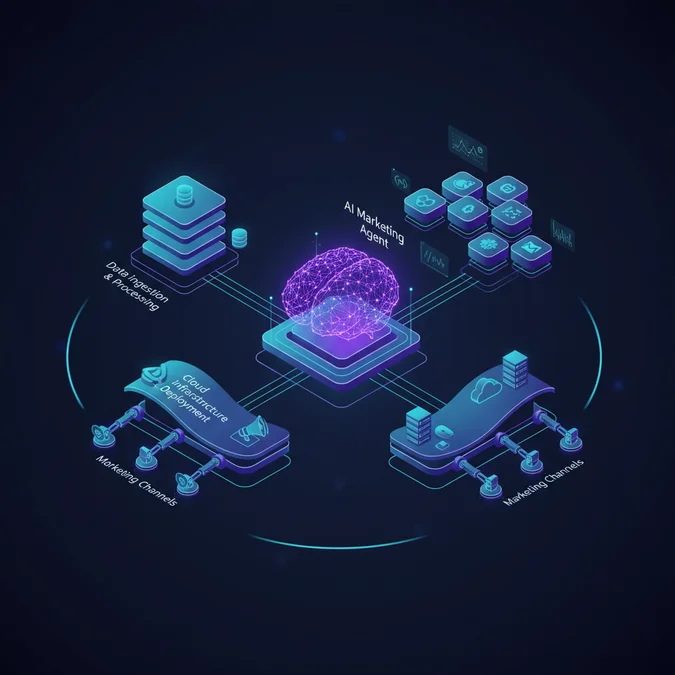
An autonomous ai marketing agent is fundamentally different from a text generator. Rather than producing creative drafts in isolation, a production-grade agent operates as a stateful, goal-seeking system that consumes streaming telemetry from customer relationship management (CRM) systems, audits conversion attribution, plans execution sequences, and invokes external advertising APIs through deterministic interfaces. When telemetry deviates from historical distribution envelopes, the system triggers internal correction loops or halts execution before corrupting campaign performance.
This architectural reference details how engineering teams design, evaluate, and deploy autonomous multi-agent systems across digital marketing stacks. We examine cyclical orchestration patterns using LangGraph, explore schema-enforced tool execution, define deterministic human-in-the-loop guardrails, and benchmark reliability metrics across complex enterprise environments in 2026.
Architectural Taxonomy: Static LLMs vs Autonomous AI Marketing Agents
The distinction between static LLM wrappers, trigger-action workflow automation, and autonomous agents is frequently obscured by superficial software marketing. In production, these three approaches occupy distinct architectural tiers characterized by differing state dynamics, feedback mechanisms, and failure modes.
Deterministic trigger-action workflows (such as legacy Zapier or webhook automations) execute hardcoded conditional logic: if event A occurs, execute action B. They provide near-zero execution drift but cannot interpret unstructured signals, navigate shifting channel environments, or formulate novel intermediate steps. Static LLM wrappers introduce natural language generation to those workflows, passing prompt strings to an inference endpoint and piping raw textual responses downstream. However, they remain feed-forward systems incapable of self-evaluating execution output or correcting faulty intermediate reasoning.
A true ai marketing agent combines dynamic goal planning, long-term state persistence, external tool access, and an explicit evaluation-reflection loop. The agent accepts an objective (such as “reduce cost per acquisition on low-performing ad sets by 15% without sacrificing weekly conversion volume”), queries analytics infrastructure, identifies candidate cohorts, generates experimental collateral, runs sanity checks against enterprise brand policies, submits mutation payloads to programmatic ad networks, and monitors resulting telemetry to adjust tactics dynamically.
+-----------------------------------------------------------------------------------+
| AUTONOMOUS AGENT RUNTIME |
| |
| +---------------------+ +--------------------+ +----------------+ |
| | Telemetry & Ingestion| -----> | Planner / Router | <----> | Shared Memory | |
| | (Webhooks, Pub/Sub) | | (ReAct Loop) | | (Redis/Vector) | |
| +---------------------+ +---------+----------+ +----------------+ |
| | |
| v |
| +--------------------+ |
| | Deterministic Tool | |
| | Execution Bus | |
| +---------+----------+ |
| | |
| +-------------------------+-------------------------+ |
| v v |
| +-------------------+ +-------------------+ |
| | Ad Platform API | | Schema & Budget | |
| | (Meta / Google) | | Guardrail Check | |
| +-------------------+ +-------------------+ |
+-----------------------------------------------------------------------------------+
The table below contrasts the technical characteristics of these three implementation paradigms across critical production dimensions:
| Capability Dimension | Trigger-Action Automation | Static LLM Prompt Wrapper | Autonomous AI Marketing Agent |
|---|---|---|---|
| Control Flow | Static directed acyclic graphs (DAGs) with hardcoded branches | Single-turn request/response inference pipeline | Cyclic state graph with dynamic runtime branch resolution |
| State Management | Stateless or linear transactional database updates | Stateless per inference call | Persistent, multi-turn memory combining Redis key-values and vector embeddings |
| Tool Calling Mechanism | Fixed API connectors via static payloads | Text extraction via regex or loose JSON generation | Typed function schemas with pydantic validation and deterministic retry nodes |
| Self-Correction | None: raises unhandled exception or terminates | None: relies on downstream user to spot hallucinations | Autonomous reflection loops with intermediate state re-planning |
| Failure Impact Profile | Silent logical failure if input schemas change | High hallucination rate and downstream brand drift | Bounded by deterministic policy interceptors and budget throttles |
Production Reality: An autonomous agent should never possess unchecked permission to alter live campaign states without schema-level constraints. Any tool call modifying budgets, audiences, or creative assets must be filtered through a deterministic runtime validator that sits outside the agent model context.
Comparative Taxonomy: AI Agents for Digital Marketing Across the Stack
Enterprise marketing operations cannot be managed by a monolithic model instance. Effective implementations decompose growth operations into specialized ai agents for digital marketing, where each node fulfills a distinct operational remit with bounded permissions, purpose-built context windows, and isolated failure modes.
By distributing responsibilities across audience discovery, creative generation, performance attribution, and budget reallocation, teams preserve operational control. If an attribution agent encounters a corrupted telemetry stream, its failure remains contained within the data transformation pipeline without triggering erratic bidding adjustments in the ad management layer.
| Agent Archetype | Primary Inputs | Tool Integrations | Execution Output | Primary Failure Modes |
|---|---|---|---|---|
| Audience Discovery Agent | First-party CRM data, lakehouse clickstreams, vector user embeddings | Snowflake SQL, BigQuery, Pinecone, Segment CDP | Dynamic cohort definitions and lookalike seed clusters | Semantic drift in audience clustering; privacy token leakage |
| Asset Generation Agent | Brand vector guidelines, asset libraries, historical performance metadata | Stable Diffusion, headless Figma API, Claude Sonnet, Runway | Channel-formatted creative variants and copy sets | Brand voice hallucination; non-compliant claims; token truncation |
| Dynamic Attribution Agent | MTA log streams, ad-server click logs, post-purchase survey payloads | dbt transformations, DuckDB, Google Analytics Admin API | Channel efficiency scores and incremental lift calculations | Attribution lag; multi-touch attribution bias; corrupted UTM parsing |
| Budget Allocation Agent | Marginal CPA, ROAS thresholds, attribution scores, real-time bid logs | Meta Marketing API, Google Ads API, TikTok Ads SDK | JSON-RPC bid adjustment payloads and budget allocations | Bidding runaway; high-frequency parameter thrashing; budget drain |
To orchestrate these specialized nodes, organizations use hierarchical supervisor-worker architectures. A supervisor agent periodically samples marketing performance against quarterly benchmarks, calculates resource allocation across channels, and issues bounded tasks to sub-agents. The sub-agents complete their tasks, execute local sanity checks, and return deterministic result payloads to the supervisor for reconciliation.
Core Mechanics: Implementing Multi-Agent Workflows with LangGraph
Constructing reliable multi-agent systems requires cyclical execution graphs capable of maintaining durable state, pausing for validation, and iterating on flawed outputs. LangGraph provides an ideal framework for this pattern, modeling agent interactions as state machines composed of discrete nodes and conditional edges.
Below is a production-grade Python implementation of an autonomous lead-scoring and personalized outreach pipeline. The graph ingests raw lead signals from a CRM webhook, qualifies the lead against explicit corporate criteria, drafts tailored collateral if the lead is valid, and routes the draft to a safety validation node before triggering an email delivery API.
import os
from typing import Dict, List, Literal, TypedDict
from pydantic import BaseModel, Field, EmailStr
from langgraph.graph import StateGraph, END
from langchain_core.messages import BaseMessage, HumanMessage, SystemMessage
from langchain_openai import ChatOpenAI

# Define strictly typed state schema
class MarketingAgentState(TypedDict):
 lead_id: str
 lead_email: str
 lead_company: str
 lead_notes: str
 qualification_score: int
 qualification_reasoning: str
 draft_subject: str
 draft_body: str
 safety_passed: bool
 revision_count: int
 error_log: List[str]

# Define output schemas for structured tool calls
class LeadQualificationOutput(BaseModel):
 score: int = Field(.. ge=0, le=100, description="ICP qualification score 0-100")
 is_qualified: bool = Field(.. description="True if score >= 70")
 reasoning: str = Field(.. description="Concrete reasoning based on ICP parameters")

class ContentSafetyOutput(BaseModel):
 approved: bool = Field(.. description="True if content adheres strictly to brand voice")
 feedback: str = Field(default="", description="Specific corrections required if rejected")

# Initialize model instances with temperature=0 for deterministic outputs
model = ChatOpenAI(model="gpt-4o-mini", temperature=0.0)

def qualify_lead_node(state: MarketingAgentState) -> Dict:
 """Evaluates inbound lead context against ICP criteria."""
 prompt = f"""Evaluate this lead for our B2B SaaS platform:
 Company: {state['lead_company']}
 Notes: {state['lead_notes']}
 Determine qualification based strictly on enterprise value potential."""

 evaluator = model.with_structured_output(LeadQualificationOutput)
 result: LeadQualificationOutput = evaluator.invoke([
 SystemMessage(content="You are an objective lead scoring engine. Score 0-100."),
 HumanMessage(content=prompt)
 ])

 return {
 "qualification_score": result.score,
 "qualification_reasoning": result.reasoning,
 "revision_count": 0
 }

def draft_outreach_node(state: MarketingAgentState) -> Dict:
 """Generates personalized message grounded in company context."""
 prompt = f"""Write a tailored outreach email to {state['lead_company']}.
 Context: {state['lead_notes']}
 Reasoning: {state['qualification_reasoning']}
 Keep it under 150 words and do not make fabricated product claims."""

 response = model.invoke([
 SystemMessage(content="You are an expert enterprise outbound copywriter."),
 HumanMessage(content=prompt)
 ])

 return {
 "draft_subject": f"Strategic alignment for {state['lead_company']}",
 "draft_body": response.content
 }

def safety_audit_node(state: MarketingAgentState) -> Dict:
 """Audits drafted email against brand and legal guidelines."""
 prompt = f"""Verify compliance for outreach draft:
 Subject: {state['draft_subject']}
 Body: {state['draft_body']}
 Rules: No false guarantees, professional tone, clear opt-out language."""

 auditor = model.with_structured_output(ContentSafetyOutput)
 result: ContentSafetyOutput = auditor.invoke([
 SystemMessage(content="You are an unyielding compliance and brand officer."),
 HumanMessage(content=prompt)
 ])

 return {
 "safety_passed": result.approved,
 "revision_count": state.get("revision_count", 0) + 1,
 "error_log": state.get("error_log", []) if result.approved else state.get("error_log", []) + [result.feedback]
 }

# Routing functions
def route_after_qualification(state: MarketingAgentState) -> Literal["draft_outreach", "__end__"]:
 if state["qualification_score"] >= 70:
 return "draft_outreach"
 return END

def route_after_safety(state: MarketingAgentState) -> Literal["draft_outreach", "__end__"]:
 if state["safety_passed"]:
 return END
 if state["revision_count"] >= 3:
 # Abort circuit breaker to avoid infinite loops
 return END
 return "draft_outreach"

# Graph Assembly
workflow = StateGraph(MarketingAgentState)
workflow.add_node("qualify_lead", qualify_lead_node)
workflow.add_node("draft_outreach", draft_outreach_node)
workflow.add_node("safety_audit", safety_audit_node)

workflow.set_entry_point("qualify_lead")
workflow.add_conditional_edges("qualify_lead", route_after_qualification)
workflow.add_edge("draft_outreach", "safety_audit")
workflow.add_conditional_edges("safety_audit", route_after_safety)

compiled_agent = workflow.compile()
Operational Stages of the Graph Pipeline
- State Ingestion: The incoming webhook payload is validated against a typed schema before the graph executes, preventing malformed CRM payloads from causing edge-case failures.
- Deterministic ICP Scoring: The evaluation node uses structured outputs constrained by Pydantic models. This guarantees typed primitives rather than ambiguous natural language strings.
- Gated Branching: Unqualified leads drop cleanly to the graph terminal, conserving token spend and preventing outreach noise.
- Adversarial Compliance Review: The system isolates content drafting from content auditing. The safety node evaluates drafts against strict compliance criteria without sharing generation bias.
- Circuit-Breaker Loops: If a safety audit fails, the graph cycles back for revision, capped by a hard threshold (3 attempts) to prevent runaway execution costs.
Evaluation Criteria: Selecting the Most Reliable AI Agent for Digital Marketing
Deploying autonomous systems across mission-critical acquisition funnels demands rigorous evaluation. Selecting the most reliable ai agent for digital marketing requires looking past vanity benchmarks (such as creative prose quality) and quantifying system performance under adverse operational conditions.
Reliability hinges on state determinism, tool-calling schema adherence, execution latency, and recovery resilience during third-party API outages.
| Evaluation Metric | Target Threshold | Measurement Methodology | Operational Risk Mitigated |
|---|---|---|---|
| Tool Execution Accuracy | > 99.4% | Percentage of tool calls returning zero structural or type validation errors | Malformed payload injection into downstream marketing APIs |
| Hallucination Rate (Metrics) | < 0.1% | Synthetic regression suites evaluating claims against warehouse truth | Reporting fabricated conversions or phantom attribution metrics |
| Deterministic Routing Consistency | > 99.8% | Identical path execution across deterministic input edge cases | Inconsistent compliance enforcement across campaigns |
| End-to-End Task Latency | < 4,500 ms | p95 execution time from event ingestion to finalized dispatch | Stale bid adjustments during dynamic programmatic auction spikes |
| Recovery Rate from API Degradation | 100% | Graceful handling of rate-limited or unavailable ad network APIs | State desynchronization between agent memory and ad platforms |
| Cost per Successful Execution | < $0.04 | Aggregate LLM token cost divided by valid, committed actions | Token consumption outstripping human administrative savings |
Production Readiness Checklist
- Schema Rigidity: Does the agent enforce typed Pydantic or JSON schemas across every outbound tool call?
- Idempotency Guarantees: Are state updates and API calls idempotent, preventing double-budget allocations on transient network failures?
- Observability Traces: Does the runtime emit OpenTelemetry spans for every internal reasoning step, tool call, and state transition?
- Adversarial Resilience: Has the agent model been stress-tested against prompt injections hidden inside user-generated campaign inputs?
- Graceful Degradation: If an ad network API rate-limits the agent, does the architecture switch to exponential backoff and notify human supervisors before dropping execution state?
Deterministic Guardrails and Human-in-the-Loop Governance
Autonomous agents must operate within explicit operational boundaries. When software manages real financial transactions and public-facing communication, brand protection and financial governance cannot rely on stochastic model judgments. Deterministic software guardrails must sit between the agent runtime and production infrastructure.
These safeguards take the form of pre-commit filters, API proxy layers, and dynamic human-in-the-loop (HITL) checkpoints. When an agent attempts an action that exceeds its operational envelope, the system freezes execution, writes state to a durable datastore, and surfaces a review request to a human operator.
Architectural Rule: An agent must never have direct write access to billing credentials, credit card APIs, or unrestricted balance parameters. All transactional updates must be routed through an external budget throttle service that enforces hard programmatic spending limits.
Core Governance Mechanisms
- Budget Throttle Interceptors: A programmatic proxy monitors all outbound mutation requests to Meta, Google, or programmatic DSPs. If an agent submits an ad set update exceeding a 20% variance from historical moving averages, or if absolute daily spend exceeds a fixed limit, the call is blocked, and an alert is issued.
- Brand Policy Schemas: Creative assets pass through a deterministic validation pipeline that audits text length, checks prohibited terms against regular expression blocks, evaluates image color contrasts, and runs automated sentiment checks before deploying assets.
- Human-in-the-Loop Interruption Nodes: In LangGraph, execution can be paused indefinitely at a designated checkpointer node using an interrupt pattern. A human marketer inspects the generated audience cohort or ad copy via a dashboard, approves or modifies the state payload, and issues an execution resume command.
- Supervisor Kill-Switches: A lightweight watchdog agent runs alongside the primary execution graph. If the watchdog detects thrashing (such as an agent adjusting bids back and forth repeatedly over minutes) or token context degradation, it triggers an immediate kill-switch, rolling back campaign configurations to the last known stable checkpoint.
Future Evolution: Model Context Protocols and Real-Time Ad Engines
As autonomous systems mature through 2026, integration architectures are moving away from brittle, bespoke API wrappers toward standardized dynamic interfaces. The emergence of open standards like the Model Context Protocol (MCP) enables marketing agents to discover, query, and mutate external enterprise data sources using unified protocol specifications rather than fragmented, proprietary SDKs.
Through standardized context protocols, an audience optimization agent can connect to enterprise data warehouses, ad networks, and web analytics stacks dynamically. Instead of engineering separate connectors for every platform update, the agent queries the platform server schema, introspects available capabilities, and executes actions with zero architectural friction.
Looking Ahead: The next frontier is real-time contextual bidding. By coupling multi-modal foundation models with edge inference nodes, marketing agents are shifting from batch-level campaign tweaks to real-time, per-impression creative generation and auction valuation within milliseconds.
Organizations standardizing their agent systems on clean graph abstractions and robust protocol layers will transition smoothly toward real-time ad engines, leaving competitors behind who remain stuck maintaining fragile, single-prompt automations.
Frequently Asked Questions
How do ai agents for marketing automation differ from traditional workflow triggers?
Traditional marketing automation relies on deterministic if-this-then-that branching logic. In contrast, ai agents for marketing automation evaluate ambiguous real-time signals, plan sequential actions dynamically, invoke external APIs, and autonomously optimize campaign strategy toward a global objective function without hardcoded pathways.
What is the primary architectural requirement of an autonomous marketing agent?
The primary requirement is a stateful multi-agent control loop incorporating dynamic memory, deterministic tool-calling, and strict schema validation. This architecture allows the agent to interact safely with external platforms such as CRMs, ad networks, and email gateways without drifting.
How do engineering teams prevent autonomous agents from overspending marketing budgets?
Teams enforce deterministic middleware guards, programmatic API throttles, and supervisor intervention nodes. These mechanisms check budget increments against hard spending caps and require human approval before any transaction exceeding a specific financial threshold is committed.
Which agentic orchestration frameworks are best suited for marketing systems?
LangGraph and CrewAI are widely preferred in production. LangGraph offers fine-grained cyclic graph control with durable state management, while CrewAI excels at orchestrating role-based agent collaborations across research, drafting, and compliance review pipelines.
Autonomous marketing agents represent a fundamental shift in how digital acquisition systems operate. By transitioning from fragile prompt wrappers and static DAGs to stateful, multi-agent control loops, engineering teams can build platforms that adapt to fluctuating market conditions, discover optimization opportunities, and maintain operational stability at scale.
However, autonomy without governance invites operational disruption. Sustainable systems combine agentic flexibility with rigorous software engineering: typed state schemas, cyclic verification graphs, deterministic budget throttles, and reliable human-in-the-loop oversight. Building this resilient infrastructure ensures that marketing autonomy delivers consistent growth without operational risk.