
In production environments, the transition from static LLM chains to dynamic systems is defined by the move toward agentic flow. When simple prompt sequences fail to navigate complex, non-deterministic branching, engineers must implement architectures that treat reasoning as a stateful, iterative process rather than a single request-response cycle.
This article dissects the mechanics of building resilient agentic flows, focusing on state management, failure recovery, and orchestration trade-offs. We move beyond theoretical design to address the practical bottlenecks of latency, context retention, and multi-agent coordination in production-grade AI systems.
Defining the Mechanics of Agentic Flow
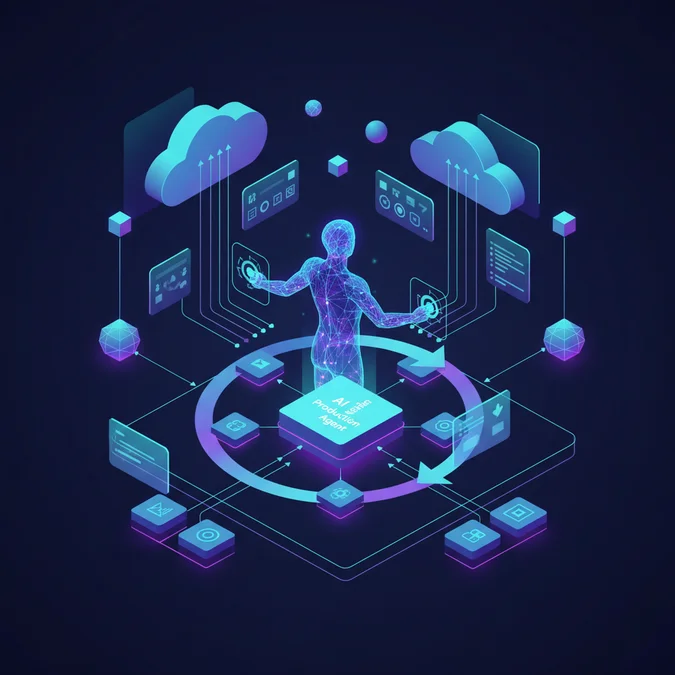
An agentic flow is an architectural pattern where an LLM acts as the central controller, iteratively evaluating inputs, selecting tools, and updating its internal state until a goal is achieved. Unlike linear chains, which function as a rigid pipeline, agentic flows utilize a feedback loop to refine output based on execution results.
Architectural Callout: The primary differentiator of an agentic flow is the presence of an evaluation loop. If the output of a tool call does not satisfy the system prompt’s termination criteria, the agent re-enters the reasoning phase rather than proceeding to the next step.
This autonomy allows for dynamic pathing, where the agent decides whether to query a database, perform a web search, or calculate a result based on the specific requirements of the user request. By decoupling the reasoning engine from the task sequence, developers gain the ability to build systems that handle edge cases without hardcoding every possible branch in the application logic.
Taxonomy of Agentic AI Flow Architectures
Understanding the structure of an agentic ai flow requires mapping the interaction model between the reasoning engine and external resources. These patterns represent the spectrum of complexity from simple reactive tasks to complex, multi-agent swarms.
| Architecture Pattern | Complexity | Primary Use Case | Latency Profile |
|---|---|---|---|
| Reactive Agent | Low | Single tool execution | Low |
| Deliberative Planner | Medium | Multi-step task decomposition | High |
| Multi-Agent Swarm | High | Complex, parallel workflows | High |
Reactive agents respond to triggers with immediate tool invocation, making them ideal for high-throughput, low-latency requirements. In contrast, deliberative planners break down high-level objectives into sub-tasks, which increases latency but significantly improves accuracy for complex reasoning. Swarm architectures distribute tasks across specialized agents, which introduces coordination overhead but allows for massive scalability in specialized domains.
Implementing Robust State Management
Long-running agentic flows frequently suffer from context loss when sessions exceed the limits of memory. To maintain state, the system must externalize the reasoning thread into a durable store. This ensures that if a process crashes or a token limit is hit, the agent can reconstruct its thought process.
def save_agent_state(session_id, history, current_plan): # Use Redis for high-speed state persistence redis_client.set(f"agent:{session_id}:history", serialize(history)) redis_client.set(f"agent:{session_id}:plan", serialize(current_plan))def resume_agent_session(session_id): history = deserialize(redis_client.get(f"agent:{session_id}:history")) return historyProduction Readiness Checklist:
- Implement automatic checkpointing after every tool invocation.
- Use a TTL (Time-to-Live) on session state to prevent memory leaks.
- Ensure atomicity in database operations to avoid partial state corruption.
- Encrypt sensitive user data stored within the agent session context.
Production Readiness and Failure Recovery
Hallucinations and tool-use loops are the primary failure modes in production agents. To mitigate these, you must implement strict guardrails and circuit breakers that monitor the agent’s output for logical consistency and repetition.
def validate_tool_execution(result, max_retries=3): if result.is_hallucinated(): return trigger_human_intervention() if result.is_looping(): return force_reset_to_previous_state() return resultFailure Recovery Checklist:
- Enforce a maximum step count per request to prevent infinite loops.
- Implement human-in-the-loop (HITL) triggers for high-stakes tool calls.
- Monitor latency metrics to detect performance degradation in agent planning.
- Use structured output formats like JSON to ensure tool responses are parseable.
Comparative Analysis of Orchestration Frameworks
Choosing the right framework depends on whether your priority is granular control over the state machine or rapid development of multi-agent interactions. The following table compares current industry standards.
| Framework | State Control | Debugging Ease | Latency Overhead |
|---|---|---|---|
| LangGraph | High (DAG-based) | Excellent | Low |
| CrewAI | Medium (Swarm) | Moderate | Moderate |
| Temporal | High (Durable) | High | High |
LangGraph excels in production scenarios where fine-grained control over the state graph is required. CrewAI provides a more abstracted interface for multi-agent coordination, which accelerates time-to-market but makes deep debugging more difficult. Temporal is the gold standard for long-running workflows where reliability is the absolute priority over raw latency.
Frequently Asked Questions
What is the primary difference between a standard prompt chain and an agentic flow?
An agentic flow enables autonomous decision-making through iterative reasoning, planning, and tool interaction. Unlike a linear prompt chain, which follows a fixed sequence, an agentic flow allows the system to evaluate its own progress, handle errors, and dynamically choose the next step based on real-time task feedback.
How does an agentic ai flow maintain context during long-running tasks?
Maintaining context in an agentic ai flow requires durable state persistence. Developers use external databases like Redis or Postgres to store agent memory, thread snapshots, and tool outputs. This ensures the system can resume operations after a timeout or failure without losing the current reasoning session.
Architecting for agentic flow requires a disciplined approach to state management, observability, and failure recovery. By moving away from monolithic prompt chains and toward modular, stateful architectures, engineering teams can build AI systems that are both resilient and capable of performing complex reasoning tasks at scale.
As you move to production, prioritize observability and human-in-the-loop controls. These are the components that distinguish a prototype from a stable, enterprise-grade agentic system.