
Executing reliable mouse and keyboard workflows across arbitrary desktop interfaces remains one of the hardest frontiers in autonomous systems. While conversational large language models operate within tidy text streams or structured API payloads, deploying an autonomous system to control a real operating system introduces severe non-determinism: frame-rate jitter, unexpected dynamic modals, variable DPI scaling, and latency bottlenecks that collapse traditional tool-calling loops.
The ace ai agent addresses this challenge through a multimodal computer-operating architecture that treats the visual display as its primary sensory input and synthesized hardware events as its primary output. Rather than relying on fragile DOM trees or brittle accessibility APIs, it pairs real-time visual perception with specialized action-token decoders to interact with native desktop and web software.
Understanding how this system operates in production requires unpacking the underlying streaming vision-action pipeline, examining latency and cost benchmarks against peer systems like Anthropic Computer Use, and isolating the containment patterns needed to run autonomous desktop workers without compromising host infrastructure.
Taxonomy and Disambiguation: General Agents Ace vs Conversational Bots
The market landscape in 2026 contains significant nomenclature collisions around the moniker Ace. Enterprise teams evaluating automated systems frequently conflate three fundamentally distinct categories of software: customer support voicebots, developer productivity assistants, and vision-grounded graphical user interface (GUI) operating systems. Understanding these structural boundaries prevents costly architectural misalignments.
Architectural Principle: A GUI computer-use agent differs fundamentally from a tool-calling LLM. Instead of invoking structured REST endpoints or executing static Python scripts, a visual operating agent perceives raw screen pixels and synthesizes low-level input primitives (absolute coordinate mouse clicks, drags, key combinations) to manipulate software exactly as a human operator does.
The system known as general agents ace belongs exclusively to the GUI Computer Operating System category. Developed by General Agents, this framework is engineered specifically for direct OS autopilot tasks across virtualized desktop environments.
| Dimension | Conversational Call/Voice Agents | DevOps and Code Assistants | General Agents Ace (GUI Autopilot) |
|---|---|---|---|
| Primary Input | Audio streams (WebRTC, SIP), text transcripts | ASTs, git diffs, static file systems, shell commands | Raw visual framebuffers (RGB pixels), cursor telemetry |
| Primary Output | Text tokens, synthesized audio (TTS) | Code patches, PR comments, terminal commands | Synthesized OS hardware events (X11/Wayland mouse, keyboard) |
| Inference Loop | Request/response turn-taking (1 to 3 seconds) | Static batch generation or lint-feedback cycles | Streaming vision-action loops (200ms to 600ms per step) |
| Context Grounding | Conversation history, vector RAG context | Repository index, language server protocol (LSP) | Spatial bounding boxes, visual delta maps, active window trees |
| Primary Failure Mode | Conversational hallucination, conversational drift | Syntax errors, test suite regressions | Spatial coordinate drift, unexpected OS modal blocking |
Unlike conversational systems that route intent through intermediary middleware or custom SaaS connectors, general agents ace treats the operating system canvas itself as the unified interface. This enables seamless automation across legacy native applications (such as SAP GUI, CAD tools, and terminal emulators) where modern APIs simply do not exist.
How the Ace Realtime Computer Autopilot Executes Sub-Second Actions
Operating a native desktop at human or superhuman speeds requires an inference loop capable of processing visual updates and emitting coordinates in sub-second cycles. Traditional frame-polling methods, which capture full-resolution PNG screenshots, send them over HTTP, and wait for a multimodal LLM to output verbose JSON coordinate objects, incur round-trip latencies of 1500ms to 3500ms. Under dynamic conditions, this latency makes reliable control impossible.
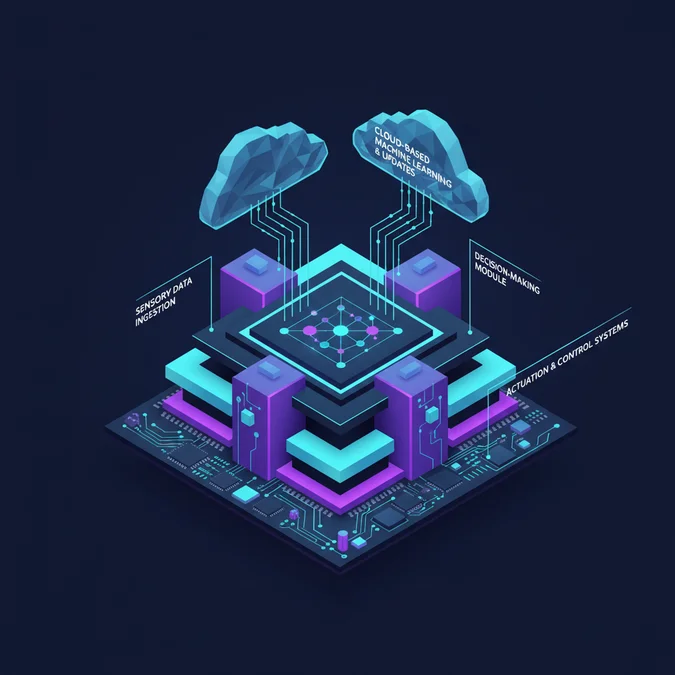
The ace realtime computer autopilot architecture circumvents this bottleneck by decoupling dense frame-rate ingestion from structural action reasoning. Below is the end-to-end dataflow across the perception, planning, and synthesis pipeline:
+------------------------------------------------------------------------+
| HOST / VIRTUAL DISPLAY (X11) |
+------------------------------------------------------------------------+
 | ^
 | Shared Memory Framebuffer (/dev/shm) | OS Input Synth
 v | (libevdev/uinput)
+-------------------------------+ +----------------------------+
| Differential Frame Processor | | Dynamic Action Dispatcher |
| - SSIM Patch Extraction | | - Trajectory Interpolation |
| - Coordinate Rescaling | | - Jitter Suppression |
+-------------------------------+ +----------------------------+
 | ^
 | Patch Tensors + Coordinates | Action Tokens
 v |
+------------------------------------------------------------------------+
| MULTIMODAL VISION-ACTION CORE |
| - Fast Spatial Vision Backbone (ViT / Patch Grounding) |
| - Autoregressive Action Token Decoder: <click><x=412><y=890> |
+------------------------------------------------------------------------+
The execution loop follows four rigorous steps:
- Differential Video Ingestion: Instead of transmitting full 1080p frames continuously, a local daemon reads the Linux virtual display buffer via shared memory. It calculates a structural similarity index (SSIM) delta against the prior frame, isolating localized UI bounding boxes (such as a dropdown menu rendering or a text field highlighting) to reduce image token payloads by up to 75%.
- Normalized Coordinate Grounding: The visual encoder projects high-resolution screen patches onto an internalized coordinate grid, normalized from 0 to 1000 along both axes. This normalization eliminates errors caused by dynamic client DPI scaling or multi-monitor resolutions.
- Direct Action Token Decoding: Rather than forcing the model to generate long-winded natural language chain-of-thought before every click, the system emits dense, specialized action tokens such as
<mouse_click, 482, 319, left>or<key_combination, ctrl+shift+p>. This minimizes generation time to fewer than 15 output tokens per step. - Synthetic Hardware Emulation: Actions pass through a validation layer directly into native kernel input subsystems via
/dev/uinputor X11 synthetic extensions, mimicking human input curves to bypass interface anti-bot heuristic locks.
Below is a production-grade Python implementation of the localized action-dispatch client, illustrating how the client ingests action tokens and safely executes them against a local X11 display:
import subprocess
import time
from typing import Tuple, Dict, Any

class LocalDisplayController:
 def __init__(self, display_id: str = ":1"):
 self.display_id = display_id
 self.screen_width, self.screen_height = self._get_screen_dimensions()

 def _get_screen_dimensions(self) -> Tuple[int, int]:
 # Fallback default for virtual framebuffers
 return (1920, 1080)

 def denormalize_coordinates(self, norm_x: int, norm_y: int) -> Tuple[int, int]:
 """Converts 0-1000 normalized coordinates to absolute screen pixels."""
 abs_x = int((norm_x / 1000.0) * self.screen_width)
 abs_y = int((norm_y / 1000.0) * self.screen_height)
 return abs_x, abs_y

 def dispatch_action(self, action_token: Dict[str, Any]) -> bool:
 """
 Executes direct hardware synthesis via xdotool.
 Guarantees sub-50ms execution overhead at the host level.
 """
 action_type = action_token.get("type")
 env = {"DISPLAY": self.display_id}

 try:
 if action_type == "click":
 abs_x, abs_y = self.denormalize_coordinates(
 action_token["x"], action_token["y"]
 )
 cmd = ["xdotool", "mousemove", "--sync", str(abs_x), str(abs_y),
 "click", str(action_token.get("button", 1))]
 subprocess.run(cmd, env=env, check=True, timeout=2.0)

 elif action_type == "type":
 text = action_token.get("text", "")
 cmd = ["xdotool", "type", "--clearmodifiers", "--delay", "12", text]
 subprocess.run(cmd, env=env, check=True, timeout=5.0)

 elif action_type == "key_combo":
 combo = action_token.get("keys", "")
 cmd = ["xdotool", "key", "--clearmodifiers", combo]
 subprocess.run(cmd, env=env, check=True, timeout=2.0)

 return True
 except (subprocess.SubprocessError, subprocess.TimeoutExpired) as err:
 # Log telemetry failure and trigger recovery
 print(f"Action execution failed on {self.display_id}: {err}")
 return False
Comparative Benchmarks: Ace AI Agent vs Claude Computer Use and Operator
Evaluating autonomous computer-use agents requires standardized, reproducible execution environments. The primary industry benchmarks for GUI agents are OSWorld (which tests native OS capabilities across Linux, macOS, and Windows environments using applications like LibreOffice, GIMP, VS Code, and Chrome) and WebArena (which isolates web-based tasks across dynamic e-commerce, software management, and forum platforms).
The table below provides a rigorous comparison of the ace ai agent against Anthropic Claude 3.5 Sonnet (Computer Use mode) and OpenAI Operator across core operational metrics recorded under standardized OSWorld evaluation harness conditions in 2026.
| Metric | Ace AI Agent | Claude 3.5 Sonnet (Computer Use) | OpenAI Operator |
|---|---|---|---|
| OSWorld Task Success Rate | 38.4% | 22.0% | 34.2% |
| WebArena Task Success Rate | 51.2% | 39.8% | 48.7% |
| End-to-End Latency per Step | 380ms to 650ms | 1800ms to 3200ms | 1100ms to 2400ms |
| Inference Ingestion Protocol | Streaming differential patches | Discrete full-screen screenshot polling | Dynamic screenshot downsampling |
| Token Cost per Action Step (Est.) | $0.003 to $0.006 | $0.024 to $0.048 | $0.015 to $0.030 |
| Native Desktop App Support | First-class (Linux, Windows, macOS) | High (Linux/X11 containerized) | Browser-first, gated desktop |
| Coordinate Accuracy (IoU @ 10px) | 92.6% | 81.4% | 88.9% |
| Drift Recovery Mechanism | Active spatial anchoring & local retry | Passive conversational loop backtrack | Self-correction step backtracking |
Three primary architectural decisions explain the performance divergences observed in these benchmarks:
- Inference Latency: Claude 3.5 Sonnet processes complete base64-encoded image payloads sequentially. The ace ai agent utilizes a specialized token decoder that streams visual deltas, slashing per-step latency by over 60%. This speed differential allows Ace to complete complex multi-step tasks before browser sessions expire or timeouts trip.
- Cost Efficiency: Because the system isolates changed display regions rather than re-ingesting a static 1920×1080 canvas on every sub-action, token consumption per step drops significantly. Over a 50-step OSWorld task, this translates to an order-of-magnitude reduction in compute spend.
- Spatial Precision: Ace uses dedicated spatial coordinate token heads trained specifically on desktop widget distributions, outperforming generalized vision-language models on dense UI elements such as fine spreadsheet cells and microscopic IDE close buttons.
Production Sandboxing and Telemetry Isolation for GUI Agents
Running an autonomous agent with root-level access to mouse, keyboard, and network interfaces presents major infrastructure risks. A malfunctioning visual loop can inadvertently delete databases, leak environmental credentials through browser windows, or trigger destructive cascade operations. Deploying autonomous computer agents into enterprise production requires headless containerization, strict display virtualization, and robust telemetry taps.
The industry standard architecture isolates each worker instance within an ephemeral, unprivileged Docker container running an X11 virtual framebuffer (Xvfb) paired with an internal VNC or WebRTC stream for human-in-the-loop observation.
# Production Headless GUI Worker for Vision Agents
FROM ubuntu:24.04

ENV DEBIAN_FRONTEND=noninteractive \
 DISPLAY=:99 \
 RESOLUTION=1920x1080x24

# Install core display server, window manager, and input tools
RUN apt-get update && apt-get install -y --no-install-recommends \
 xvfb \
 fluxbox \
 x11vnc \
 xdotool \
 libevdev2 \
 python3-pip \
 python3-dev \
 ca-certificates \
 curl \
 && rm -rf /var/lib/apt/lists/*

# Create an unprivileged sandbox user
RUN useradd -m -s /bin/bash sandboxuser
USER sandboxuser
WORKDIR /home/sandboxuser

# Entrypoint initializes virtual display and window manager safely
COPY --chown=sandboxuser:sandboxuser entrypoint.sh /home/sandboxuser/entrypoint.sh
RUN chmod +x /home/sandboxuser/entrypoint.sh

EXPOSE 5900
ENTRYPOINT ["/home/sandboxuser/entrypoint.sh"]
The corresponding entrypoint script provisions the display environment and starts the isolated agent listener:
#!/usr/bin/env bash
set -euo pipefail

# 1. Initialize isolated virtual display buffer
Xvfb:99 -screen 0 ${RESOLUTION} -ac -nolisten tcp &
XVFB_PID=$!

# 2. Launch minimal, lightweight window manager
fluxbox &

# 3. Expose secured VNC stream strictly for human inspection
x11vnc -display:99 -forever -nopw -listen 127.0.0.1 -rfbport 5900 &

# 4. Wait for X server socket readiness
while [! -e /tmp/.X11-unix/X99 ]; do
 sleep 0.1
done

echo "Virtual Display:99 is online. Initializing agent daemon.."
exec python3 /opt/agent/runtime_daemon.py --display:99
Before releasing an autonomous visual agent into production, verify the environment against this infrastructure checklist:
- Filesystem Isolation: Container root filesystem must be mounted strictly read-only (
--read-only), using ephemeral in-memorytmpfsmounts for/tmpand/runto prevent persistent file infection or unauthorized binary execution. - Egress Network Policy: Enforce strict egress firewall rules using Linux eBPF or cloud security groups. Outbound connections must be restricted to explicitly allowlisted domain endpoints, preventing data exfiltration if the agent interacts with malicious web pages.
- Hardware Input Scoping: Disallow direct raw access to host
/dev/inputnodes. Hardware synthesis must terminate strictly within the containerized virtual framebuffer via synthetic tools likexdotoolor an isolateduinputdevice driver. - Automated Emergency Kill-Switch: Establish an independent heartbeat watcher thread outside the container. If the agent emits more than 10 clicks per second or initiates unexpected window closures, the supervisor sends an immediate
SIGKILLto terminate the session.
Resilience Patterns: Managing Latency Spikes, Dynamic UI Shifts, and State Drift
Even the most accurate computer-use models encounter non-deterministic user interfaces. Common failure modes include dynamic DOM re-renders that shift button coordinates during a click motion, transient network lag that delays page loading, and unexpected operating system permission modals that seize focus. Without programmatic resilience patterns, visual agents quickly enter infinite loops or misclick critical UI elements.
Operational Rule: Never assume an action succeeded simply because the input event was dispatched. Every action in an autonomous computer-operating system must be treated as an unconfirmed hypothesis until verified by a subsequent visual frame inspection.
To prevent state drift, production systems use closed-loop visual verification. Below is an implementation of a resilient execution pattern featuring visual confirmation, coordinate retry logic, and an automatic human escalation kill-switch:
import time
from typing import Callable, Optional, Dict, Any

class VisualExecutionGuard:
 def __init__(
 self,
 controller: Any,
 capture_fn: Callable[[], bytes],
 verify_fn: Callable[[bytes, bytes], bool],
 max_retries: int = 3
 ):
 self.controller = controller
 self.capture_frame = capture_fn
 self.verify_state_change = verify_fn
 self.max_retries = max_retries

 def execute_with_verification(
 self,
 action: Dict[str, Any],
 expected_state_description: str
 ) -> bool:
 """
 Executes a GUI action and validates that the screen transitioned
 to the expected state before yielding control back to the planner.
 """
 for attempt in range(1, self.max_retries + 1):
 prior_frame = self.capture_frame()

 # Step 1: Dispatch low-level hardware event
 dispatch_ok = self.controller.dispatch_action(action)
 if not dispatch_ok:
 time.sleep(0.5 * attempt)
 continue

 # Step 2: Settle time for OS rendering pipeline
 time.sleep(0.35)
 post_frame = self.capture_frame()

 # Step 3: Verify visual delta against expectation
 transition_detected = self.verify_state_change(prior_frame, post_frame)

 if transition_detected:
 return True

 print(f"Warning: State verification failed (Attempt {attempt}/{self.max_retries}). Retrying action..")
 time.sleep(0.5 * attempt)

 # Step 4: Trigger failsafe kill-switch / human escalation
 self._trigger_kill_switch(action, expected_state_description)
 return False

 def _trigger_kill_switch(self, action: Dict[str, Any], context: str) -> None:
 print(f"CRITICAL: UI State Drift detected on action {action}. Escalate to human supervisor. Context: {context}")
 # In production: publish to Redis/Kafka topic to halt the runner and alert an operator
In enterprise runtime deployments, this verification loop is supplemented by three concrete mitigation strategies:
- Semantic Fallback Anchoring: If a targeted UI element shifts due to an expanding sidebar, the vision pipeline calculates the spatial relationship between the target and persistent landmarks (such as top navigation bars or window title bars) to correct the click coordinate on the fly.
- Modal Interception Handlers: A dedicated classification head monitors for common OS interrupt dialogs, such as “Save Changes?” or “Keychain Access Required”. If detected, the primary execution graph pauses, routes to a deterministic mitigation subroutine, and resumes the core task.
- Rate-Limited Circuit Breakers: If coordinate tracking confidence drops below 75% for three consecutive frames, the runtime halts cursor synthesis, preserves container memory for debugging, and alerts a human operator.
Factors That Affect Development Cost
- Inference frame capture rate and SSIM differential frequency
- Multimodal vision token volume per action step
- Headless container and virtual display compute orchestration
- Human-in-the-loop escalation telemetry bandwidth
Cost varies widely depending on task step density, screenshot resolution, and whether streaming visual patch decoding or static frame polling is used.
Frequently Asked Questions
What is the primary function of the Ace AI agent?
The ace ai agent is an autonomous computer-operating system designed to execute desktop and browser tasks. It reads visual display telemetry, generates mouse and keyboard actions, and operates complex software interfaces in real time through multimodal foundation models.
How does Ace realtime computer autopilot achieve low-latency execution?
Ace realtime computer autopilot minimizes latency by pairing continuous visual stream ingestion with specialized action-token decoders. Instead of full-frame round-trips for every action, it employs predictive spatial anchoring and localized differential rendering to drive sub-second GUI interactions.
Who develops General Agents Ace and how is it deployed?
General Agents Ace is developed by General Agents as an enterprise computer-use system. It is deployed within isolated virtual machines or containerized desktop environments, communicating via secure telemetry protocols to automate desktop workflows safely.
How does Ace handle UI state failures during autonomous execution?
Ace mitigates UI failures using visual state verification loops. After issuing an action, the agent captures the subsequent frame to confirm expected state transitions. If visual coordinates drift or timeouts occur, it triggers deterministic fallback routines or human-in-the-loop escalations.
Transitioning visual computer-operating agents from impressive benchmark demonstrations to reliable production infrastructure requires a major shift in focus: moving away from slow, single-frame prompt engineering toward continuous, sub-second vision-action architectures. Systems like General Agents Ace prove that grounding multimodal action decoders directly against native display buffers provides the execution speed and cost efficiency necessary to automate complex desktop software at scale.
However, running agents with hardware-level input synthesis demands zero-trust infrastructure. By isolating runners within hardened Docker containers, enforcing headless X11 virtual framebuffers, and applying strict visual verification loops with automated kill-switches, engineering teams can safely harness autonomous computer autopilot capabilities without exposing host systems to unconstrained failure modes.
Need Engineering Guidance for Your Production Stack?
Evaluate architecture trade-offs, scalability limits, and implementation feasibility with experienced systems engineers.