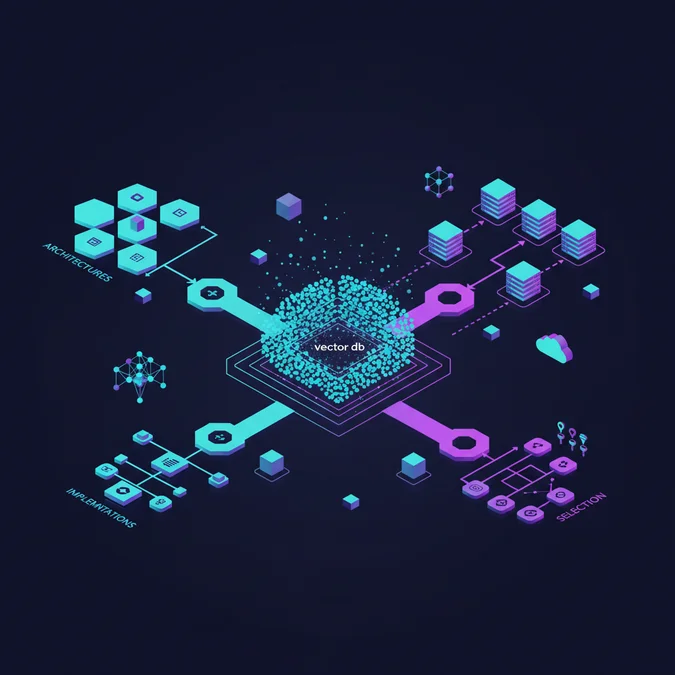

Vector databases are specialized data stores designed to efficiently store, index, and query high-dimensional numerical vectors, often representing embeddings generated from complex data like text, images, or audio. Their primary function is to facilitate rapid similarity searches, identifying data points that are semantically close to a given query vector. This capability is fundamental to modern artificial intelligence applications, enabling functions such as semantic search, recommendation systems, anomaly detection, and Retrieval-Augmented Generation (RAG) pipelines.
The explosion of AI/ML models has made the efficient management and retrieval of vector embeddings a critical challenge in building scalable, intelligent systems. Traditional relational or NoSQL databases are ill-suited for the unique demands of high-dimensional vector operations, leading to the emergence of purpose-built vector dbs. This article delves into their core mechanics, explores the diverse landscape of solutions, and provides a framework for selecting and deploying the optimal vector database for your production needs in 2026.
Understanding Vector Databases: The Foundation of Semantic Search
At its core, a vector database is an optimized system for managing vector embeddings, which are numerical representations of data points in a high-dimensional space. These embeddings capture semantic meaning, allowing for operations that transcend simple keyword matching. When discussing what is a vector database in AI, it is critical to understand its role as a specialized engine for similarity computations, crucial for applications that rely on understanding context and relationships within data.
The journey begins with an embedding model, such as OpenAI’s text-embedding-3-large or a fine-tuned BERT variant, transforming raw data (text, images, audio, etc.) into dense numerical vectors. Each vector represents the semantic characteristics of its original data point. These vectors are then ingested into vector dbs, which index them in a way that allows for extremely fast retrieval of similar vectors. This process is known as vector similarity search, making the vector database an essential vector similarity search engine.
Key Concept: Embeddings
An embedding is a dense vector representation of an object (word, sentence, image, etc.) where objects with similar meanings are located closer to each other in the vector space. The quality and dimensionality of these embeddings directly impact the accuracy and performance of any downstream similarity search.
Unlike traditional databases that query based on exact matches or structured fields, vector databases operate on the principle of distance in a multi-dimensional space. The closer two vectors are, the more similar their underlying data. This paradigm shift enables powerful new AI capabilities, moving beyond brittle keyword searches to truly semantic understanding.
How Vector Databases Work: Embeddings, Indexing, and Algorithms in Action
The efficiency of a vector database hinges on two primary components: effective embedding generation and sophisticated indexing for Approximate Nearest Neighbor (ANN) search. For a concrete vector database example, consider a scenario where a user queries a product catalog with natural language. The query text is first converted into a vector embedding. This query vector is then sent to the vector database, which rapidly finds the most similar product embeddings, translating to relevant product recommendations.
The process starts with converting raw data into embeddings. Here is a Python snippet demonstrating how to generate embeddings using a common library:
from sentence_transformers import SentenceTransformer

def generate_embedding(text: str) -> list[float]:
 """Generates a vector embedding for the given text."""
 try:
 model = SentenceTransformer('all-MiniLM-L6-v2')
 embedding = model.encode(text).tolist()
 return embedding
 except Exception as e:
 print(f"Error generating embedding: {e}")
 return []

# Example usage for vector db examples
product_description = "A lightweight, durable hiking backpack with a 40L capacity."
query_text = "Backpacks for outdoor adventures"

product_embedding = generate_embedding(product_description)
query_embedding = generate_embedding(query_text)

print(f"Product Embedding (first 5 dims): {product_embedding[:5]}..")
print(f"Query Embedding (first 5 dims): {query_embedding[:5]}..")
Once embeddings are generated, the vector database indexes them. Given the high dimensionality, exact nearest neighbor search is computationally prohibitive for large datasets. This is where ANN algorithms become crucial, allowing what software provides fast vector search by sacrificing a small amount of accuracy for significant speed improvements.
Distance Metrics
Similarity between vectors is measured using distance metrics. Common choices include Cosine Similarity (measures the angle between vectors, ideal for text), Euclidean Distance (straight-line distance, sensitive to magnitude), and Dot Product (similar to cosine for normalized vectors, penalizes smaller magnitudes).
Two prominent ANN algorithms are Hierarchical Navigable Small Worlds (HNSW) and Inverted File Index with Flat Quantization (IVF_FLAT). Each offers distinct trade-offs:
| Algorithm | Description | Pros | Cons | Typical Use Case |
|---|---|---|---|---|
| HNSW (Hierarchical Navigable Small Worlds) | Builds a multi-layer graph structure where each layer connects fewer, more distant neighbors, enabling fast traversal from coarse to fine granularity. | High recall at high speed, efficient indexing and querying, robust for various data distributions. | Higher memory footprint, index construction can be slower for extremely large datasets. | Real-time semantic search, recommendation engines. |
| IVF_FLAT (Inverted File Index with Flat Quantization) | Divides vector space into ‘cells’ (clusters) and quantizes vectors within each cell. Search involves finding nearest cells, then searching within them. | Lower memory usage, faster index construction, good for very large datasets where memory is a constraint. | Recall can be lower than HNSW, requires careful tuning of ‘nprobe’ (number of cells to search). | Large-scale image retrieval, cold storage vector search. |
These algorithms are fundamental to how vector databases achieve their performance. They enable the rapid identification of relevant items from millions or billions of vectors, making real-time AI applications feasible.
Exploring the Vector Database Landscape: Open-Source, Managed, and Hybrid Solutions
The market for vector databases has rapidly matured by 2026, offering a diverse array of options spanning open-source projects, managed services, and hybrid deployments. Understanding this landscape is crucial for selecting the right tool for your specific application. Here, we explore the major categories and provide a vector databases list of prominent solutions.
Open-Source Vector Databases
Open source vector database solutions provide maximum flexibility and control, often coming with a vibrant community and no direct licensing costs. They are ideal for teams with strong DevOps capabilities and specific customization needs. Many also offer a free vector database option for local development and smaller-scale projects.
- Weaviate: A cloud-native, open source vector database that combines vector search with semantic capabilities. Supports GraphQL and has built-in modules for various AI models.
- Qdrant: A vector similarity search engine written in Rust, known for its high performance and robust filtering capabilities. It can be deployed as an open source vector db on-premise or in the cloud.
- Milvus: A highly scalable vector database designed for AI applications, capable of handling billions of vectors. It is a popular choice for large-scale semantic search and recommendation systems.
- Faiss (Facebook AI Similarity Search): While not a full vector database, Faiss is a library for efficient similarity search and clustering of dense vectors. It is often used as a backend for custom local vector db solutions.
- Chroma: A lightweight, embeddable vector database, ideal for local development and smaller applications. It provides a simple API and is easy to integrate.
Managed Vector Database Services
Managed services abstract away infrastructure management, offering scalability, reliability, and often advanced features with less operational overhead. These are particularly attractive for businesses focusing on application development rather than infrastructure.
- Pinecone: One of the most recognized leading vector search services, offering a fully managed, scalable vector database with robust filtering and real-time indexing capabilities.
- Zilliz Cloud: The managed service for Milvus, providing a scalable, enterprise-grade vector database experience without the complexities of self-hosting.
- Supabase Vector: Built on PostgreSQL with the pgvector extension, offering a managed solution that combines relational data with vector search capabilities.
- Redis Stack (with RedisSearch/RedisJSON): While primarily a key-value store, Redis Stack can be extended with modules to provide vector search, making it a versatile option.
Many of these popular vector databases and popular vector db services are backed by leading vector database companies that also contribute significantly to the broader AI ecosystem. The choice between open-source and managed often boils down to a balance of control, operational burden, and cost.
Deployment Model Checklist:
- Self-Hosted/On-Premise: Full control over infrastructure, data, and security. Requires significant operational expertise.
- Cloud-Hosted (IaaS/PaaS): Deploy open-source solutions on cloud VMs or container platforms. Offers more flexibility than managed services but still requires some management.
- Fully Managed Service: Minimal operational overhead. Vendor handles scaling, maintenance, and upgrades. Ideal for rapid development and lean teams.
- Hybrid: Combine on-premise components with cloud services for specific workloads or data residency requirements.
- Local/Embedded: Lightweight solutions like Chroma or Faiss for development, testing, or edge applications where a full server is overkill.
By 2026, the trend shows increased adoption of managed services for production, while open-source remains dominant for research, custom solutions, and smaller-scale deployments. The most popular vector database options often include a mix of both, catering to diverse enterprise needs.
Choosing Your Vector Database: A Comparative Analysis for Production Systems
Selecting the best vector database for your project requires a rigorous evaluation against several key criteria. There is no single best vector db, as the optimal choice depends heavily on your specific application, data volume, query patterns, and team capabilities. This section provides a framework to help you choose from the top vector database solutions available in 2026, including insights for a leading vector database for business and a best vector database service for startups.
Critical Selection Factors
Prioritize scalability for future growth, ensure a rich feature set for metadata filtering and hybrid search, evaluate performance under anticipated load, and consider the total cost of ownership (TCO) including operational overhead.
Features to Look For in a Vector Database:
- Scalability: Can it handle billions of vectors and high query throughput? Does it scale horizontally or vertically?
- Performance: Low latency for similarity search (e.g. <50ms for 100M vectors) and high QPS (Queries Per Second).
- Filtering Capabilities: Ability to combine vector search with structured metadata filtering (e.g. “find similar products by brand X”). This is crucial for the best database to retrieve vector embeddings in complex scenarios.
- Data Freshness & Consistency: How quickly are new or updated vectors indexed and searchable? What consistency models does it offer?
- Deployment Options: Self-hosted, managed service, cloud-agnostic, or specific cloud provider integration.
- Ecosystem & Integrations: Support for popular AI frameworks (PyTorch, TensorFlow), language clients, and existing data pipelines.
- Cost: Licensing, infrastructure, operational costs, and potential vendor lock-in for managed services.
- Community & Support: Active open-source community or enterprise-grade support from the vendor.
- Hybrid Search: Support for combining keyword search (e.g. BM25) with vector search for enhanced relevance.
Here is a comparative overview of some highly rated vector database software and services, focusing on aspects relevant for production systems:
| Solution | Deployment | Key Strengths | Typical Latency (100M vectors, 128D) | Max Throughput (QPS) | Memory Footprint |
|---|---|---|---|---|---|
| Pinecone | Managed Cloud | Fully managed, robust filtering, high scalability, real-time updates. | ~20-50 ms | ~500-1000+ | Managed (cost based on vector count) |
| Weaviate | Self-hosted, Managed Cloud | Semantic search, GraphQL API, strong knowledge graph capabilities. | ~30-70 ms | ~300-800 | Moderate to High |
| Qdrant | Self-hosted, Managed Cloud | High performance, Rust-native, advanced filtering, good for large datasets. | ~15-40 ms | ~600-1200+ | Low to Moderate |
| Milvus (Zilliz Cloud) | Self-hosted, Managed Cloud | Massive scalability (billions of vectors), distributed architecture. | ~40-100 ms | ~400-900 | High (distributed) |
| Chroma | Embedded, Self-hosted | Lightweight, easy to use, ideal for local development and small-scale. | ~5-20 ms (local, smaller scale) | ~100-300 (local) | Very Low (local) |
| Supabase Vector (pgvector) | Managed Cloud, Self-hosted | Integrates vector search with PostgreSQL, good for hybrid queries. | ~50-150 ms | ~100-400 | Moderate (depends on PG setup) |
When considering the best AI vector search engine, look for solutions that natively support metadata filtering and offer low-latency query performance under heavy load. For a best vector database service for startups, ease of use, managed features, and a clear pricing model are often more critical than extreme customization. Businesses seeking a leading vector database for business will prioritize enterprise-grade security, compliance, and 24/7 support.
Advanced Deployment and Architectural Patterns for Vector Databases
Integrating a vector db into a production AI system demands careful architectural planning to ensure scalability, performance, and data freshness. Common patterns emerge in applications like Retrieval-Augmented Generation (RAG) and recommendation engines.
Architectural Pattern: Retrieval-Augmented Generation (RAG)
A RAG system leverages a vector database to retrieve relevant context for a large language model (LLM), enhancing its ability to generate accurate and informed responses. This pattern is critical for enterprise AI applications requiring up-to-date, domain-specific knowledge.
+-----------------+
| Data Sources |
| (Docs, DBs, APIs) |
+--------+--------+
 |
 v
+--------+--------+
| Embedding Model|
| (e.g. OpenAI) |
+--------+--------+
 |
 v
+-----------------+
| Vector Database |
| (e.g. Pinecone)|
| (Indexed Docs)|
+--------+--------+
 |
 v
+-----------------+
| User Query |
+--------+--------+
 |
 v
+--------+--------+
| Embedding Model |
| (Query Vector) |
+--------+--------+
 |
 v
+-----------------+
| Vector Database |
| (Similarity Search)|
+--------+--------+
 |
 v
+-----------------+
| Retrieved Chunks|
+--------+--------+
 |
 v
+-----------------+
| LLM (GPT-4) |
| (Context + Query)|
+--------+--------+
 |
 v
+-----------------+
| Generated Answer|
+-----------------+
In this RAG workflow, the vector database acts as the memory and knowledge base for the LLM, providing relevant document chunks based on semantic similarity to the user’s query.
Managing Data Freshness and Re-indexing
Data in production systems is rarely static. Maintaining data freshness in a vector database is crucial for accuracy. Strategies include:
- Incremental Updates: For data that changes frequently, update specific vectors or small batches rather than re-indexing the entire dataset.
- Scheduled Re-indexing: Periodically rebuild the entire index for datasets with high churn or when the embedding model is updated. This can be done with a blue/green deployment strategy to minimize downtime.
- CDC (Change Data Capture): Integrate with CDC tools to stream data changes directly to the embedding pipeline and then to the vector database for near real-time updates.
Performance Optimization Tip
When dealing with high-dimensional vectors, consider techniques like dimensionality reduction (e.g. PCA, UMAP) if the intrinsic dimensionality of your data is lower than the embedding output. This can reduce memory footprint and improve query speeds, though it may slightly impact recall.
Here is a simplified Python example demonstrating a re-indexing strategy using a temporary index:
import time
import random
from typing import List, Dict

# Assume 'vector_db_client' is an initialized client for your vector database
# and 'generate_embedding' is a function from Section 2

class ProductionVectorDB:
 def __init__(self, client):
 self.client = client
 self.current_index_name = "production_index_v1"
 # Initialize the production index if it doesn't exist
 # self.client.create_index(self.current_index_name, dimension=128)

 def get_current_index(self):
 return self.current_index_name

 def query(self, query_vector: List[float], top_k: int = 5) -> List[Dict]:
 print(f"Querying index: {self.current_index_name}")
 # Simulate a query operation
 time.sleep(0.01)
 return [{"id": f"doc_{i}", "score": random.random()} for i in range(top_k)]

 def reindex_data(self, new_data_batch: List[str]):
 print("Starting re-indexing process..")
 new_index_name = f"production_index_v{int(time.time())}"
 # 1. Create a new, empty index
 # self.client.create_index(new_index_name, dimension=128)
 print(f"Created new index: {new_index_name}")

 # 2. Ingest all new and existing data into the new index
 for item in new_data_batch:
 embedding = generate_embedding(item)
 # self.client.upsert(index_name=new_index_name, vectors=[(item_id, embedding)])
 print(f"Ingested data point: {item}")
 time.sleep(0.001) # Simulate ingestion time

 # 3. Validate the new index (optional but recommended)
 # self.client.validate_index(new_index_name)
 print(f"Validated new index: {new_index_name}")

 # 4. Atomically switch the alias/pointer to the new index
 old_index = self.current_index_name
 self.current_index_name = new_index_name
 # self.client.update_alias("production_alias", new_index_name)
 print(f"Switched active index from {old_index} to {new_index_name}")

 # 5. Optionally, delete the old index after a grace period
 # self.client.delete_index(old_index)
 print(f"Old index {old_index} marked for deletion (or retention).")
 print("Re-indexing complete.")

# Example usage:
# from sentence_transformers import SentenceTransformer
# model = SentenceTransformer('all-MiniLM-L6-v2')
# def generate_embedding(text: str) -> list[float]:
# return model.encode(text).tolist()

# Mock client (replace with actual vector DB client)
class MockVectorDBClient:
 def create_index(self, name, dimension): pass
 def upsert(self, index_name, vectors): pass
 def validate_index(self, name): pass
 def update_alias(self, alias, new_index): pass
 def delete_index(self, name): pass

mock_client = MockVectorDBClient()
prod_db = ProductionVectorDB(mock_client)

print(prod_db.query(generate_embedding("test query")))

new_data = [
 "Updated product description for laptop X",
 "New article about quantum computing breakthroughs",
 "Customer review for smart home device Y"
]
prod_db.reindex_data(new_data)

print(prod_db.query(generate_embedding("another test query")))
This blue/green deployment approach ensures continuous availability during potentially long re-indexing operations. By carefully planning for data lifecycle management and integrating vector databases into robust architectural patterns, organizations can unlock the full potential of semantic search and AI-driven applications.
Frequently Asked Questions
What is the key difference between a vector store and a vector database?
A vector store typically refers to a component or library focused solely on storing and searching vector embeddings. In contrast, a vector database offers a complete, production-ready system with additional features like data management, indexing, filtering, scalability, and often enterprise-grade reliability and security for managing vector data at scale.
What are critical engineering considerations for top vector databases?
When implementing top vector databases, prioritize deterministic execution, rigorous error handling, observability metrics, and strict security isolation to maintain production reliability and eliminate latency bottlenecks.
What are critical engineering considerations for vector store vs vector database?
When implementing vector store vs vector database, prioritize deterministic execution, rigorous error handling, observability metrics, and strict security isolation to maintain production reliability and eliminate latency bottlenecks.
Vector databases have cemented their position as an indispensable component in the modern AI/ML stack by 2026. Their ability to manage and query high-dimensional embeddings efficiently powers the next generation of intelligent applications, from sophisticated semantic search to highly contextualized RAG systems. The landscape offers a rich choice of open-source and managed solutions, each with distinct advantages for different use cases and operational models.
The critical takeaway is that careful selection and thoughtful architectural integration are paramount. Understanding the nuances of embedding models, ANN algorithms, and deployment considerations will directly impact the performance, scalability, and ultimately, the success of your AI initiatives. By leveraging the insights and frameworks presented here, engineers and architects can confidently navigate the vector database ecosystem and build robust, future-ready AI systems.