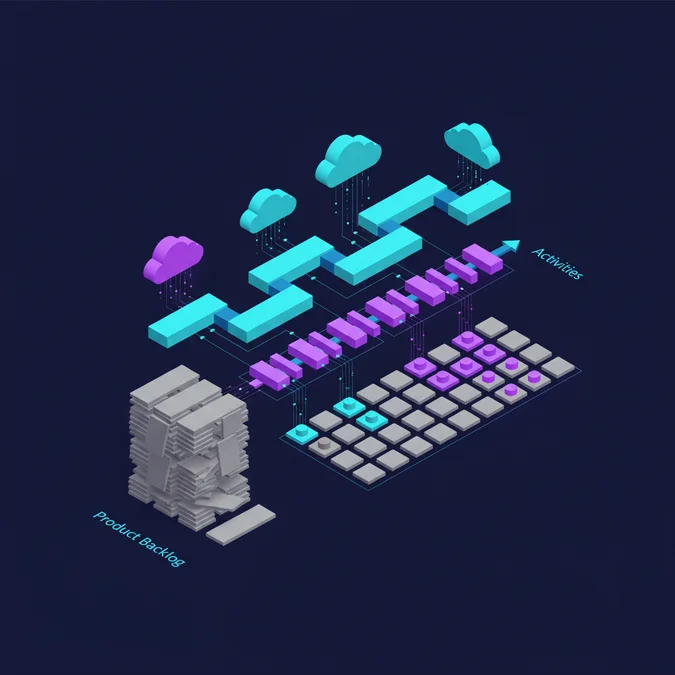

User story mapping is a collaborative product planning method that arranges functional software requirements across a dynamic two-dimensional grid: user activities align chronologically along a horizontal narrative backbone, while vertical columns stack granular user tasks prioritized by execution criticality. By moving beyond flat Jira backlogs, engineering organizations visualize user workflows holistically and deliver coherent vertical slices rather than fragmented technical components.
When software teams rely on one-dimensional task lists, context collapses. Flat backlogs obscure upstream and downstream system dependencies, degrade cross-functional alignment, and encourage engineering silos to prioritize isolated horizontal layers such as database schemas, middle-tier controllers, or front-end components. These disconnected efforts invariably stall integration testing and delay end-to-end user validation.
This architectural guide provides a concrete blueprint for executing user story mapping in complex software ecosystems. We explore core conceptual taxonomies, contrast discovery frameworks, examine a complete multi-tenant fintech SaaS story map, and detail technical vertical slicing strategies that guarantee continuous delivery value.
Foundational Architecture of User Story Mapping
A typical product backlog operates as a linear queue of tickets, ranked by isolated priority numbers. In complex systems, this linear arrangement causes cognitive friction: teams cannot ascertain how a specific database optimization or schema migration aligns with the human user journey. User story mapping resolves this fundamental issue by introducing a two-dimensional operational coordinate space.
+-------------------------------------------------------------------------------+
| THE NARRATIVE BACKBONE |
| [Activity: Authentication] -> [Activity: Ingestion] -> [Activity: Audit] |
+-------------------------------------------------------------------------------+
| USER TASKS / STEPS |
| [Task 1.1] [Task 1.2] [Task 2.1] [Task 3.1] |
+===============================================================================+
| SLICE 1: WALKING SKELETON (Minimal end-to-end viability) |
| - Devise token handler - Single CSV upload - Stdout log |
+-------------------------------------------------------------------------------+
| SLICE 2: MVP / RELEASE 1.0 (Core market functionality) |
| - SAML / SSO integration - S3 Batch polling - DB Audit log |
+-------------------------------------------------------------------------------+
| SLICE 3: ENHANCEMENTS / RELEASE 2.0 (Scale, automation, fault tolerance) |
| - WebAuthn / Passkeys - Kafka Stream Pipeline - SIEM streaming |
+-------------------------------------------------------------------------------+
The Horizontal Axis: Narrative Backbone and Journey Steps
The horizontal axis models the user timeline from left to right. It is organized hierarchically into two tiers:
- Activities (Backbone): High-level system interactions that represent broad user goals (for example, Authenticate Identity, Ingest Ledger Data, Generate Invoices, Reconcile Payments). Activities are rarely optional; removing one leaves the business process functionally broken.
- Steps / Tasks (Ribs): Specific technical or operational interactions that an actor carries out under an Activity. Under Authenticate Identity, steps might include Submit Credentials, Challenge Multi-Factor Token, and Authorize RBAC Roles.
The Vertical Axis: Prioritization Depth and Value Slicing
The vertical axis represents necessity, technical dependency, and delivery urgency. Unlike a flat backlog, where tickets shuffle arbitrarily between sprints, the vertical axis groups tasks into functional delivery tiers:
- Top Row (Walking Skeleton): The bare minimum technical implementation required to link all system boundaries end to end. It exercises architectural components, database migrations, network transport, and client communication, even if user interfaces are primitive.
- Middle Rows (Minimum Viable Product): The smallest release tier that safely serves real-world production workloads without catastrophic manual intervention.
- Lower Rows (Growth and Scalability): Optimized, highly automated variations, edge-case remediation, fault-tolerant fallbacks, and performance tuning.
Architectural Takeaway: A story map is not a decorative workflow diagram. It functions as an operational contract between product management, distributed systems architects, and delivery teams, guaranteeing that every engineering pull request directly supports an observable step in the user journey.
Anatomy of the Walking Skeleton
The walking skeleton is the foundational baseline of a resilient user story map. It constitutes the thinnest executable slice of system functionality spanning every structural tier of your software architecture. For a cloud-native microservices cluster, the walking skeleton connects ingress routing, authentication middleware, domain event dispatchers, operational databases, and notification webhooks.
Walking Skeleton Architectural Checklist
- Cross-boundary network connectivity validated across all downstream domain services
- Persistence layer migrations and schema rollouts execute idempotently via continuous delivery pipelines
- Distributed tracing contexts (W3C Trace Context, OpenTelemetry) span every horizontal workflow node
- Minimal end-to-end integration test passes deterministically inside ephemeral staging environments
- Zero dead-end architectural mockups; every node transmits authentic bytes through the wire
Mapping Framework Taxonomy: Story Maps vs Flat Backlogs vs Journey Maps
Engineering teams frequently confuse user story maps with Customer Journey Maps (CJMs), Event Storming sessions, and traditional Jira backlogs. Each technique optimizes for fundamentally distinct operational objectives across discovery and execution lifecycles.
| Evaluation Vector | User Story Mapping | Customer Journey Map (CJM) | Event Storming (DDD) | Linear Flat Backlog |
|---|---|---|---|---|
| Primary Objective | Release slicing, technical dependency ordering, and vertical delivery governance. | Customer sentiment tracking, qualitative emotion analysis, and brand touchpoints. | Domain boundary discovery, aggregate definition, and asynchronous event modeling. | Sprint task tracking, localized ticket assignment, and basic burndown metrics. |
| Dimensionality | 2D Grid: Chronological sequence (X) vs Release criticality (Y). | 2D / Timeline: Funnel stages (X) vs Experience / Friction tiers (Y). | Linear Timeline: Chronological domain events running left-to-right on an infinite canvas. | 1D: Single-column linear stack prioritized by arbitrary business rank. |
| Target Stakeholders | Principal Engineers, Technical Product Managers, Engineering Leads, QA Teams. | Product Designers, UX Researchers, CMOs, Product Marketers. | Domain-Driven Design (DDD) Architects, Lead Engineers, Domain Experts. | Scrum Masters, Individual Contributors, Delivery Managers. |
| Architectural Granularity | Deconstructs workflow steps into API contracts, database operations, and UI states. | Abstract operational touchpoints (for example, Receives Onboarding Email, Waits on Call). | Explicit Domain Events, Commands, Read Models, and Bounded Contexts. | Isolated technical tickets; system-level context is frequently lost. |
| Release Planning Utility | High: Native vertical slicing reveals the minimum viable walking skeleton instantly. | Low: Identifies user frustration areas but lacks engineering delivery boundaries. | Medium: Surfaces command-event boundaries but does not schedule release increments. | Extremely Low: Teams often cherry-pick isolated tasks, yielding un-shippable builds. |
| Failure Mode | Scope creep if facilitators fail to establish rigid vertical release cutlines. | Abstract operational insights that fail to translate into actionable Jira tickets. | Analysis paralysis around domain linguistics without concrete shipping cadences. | Fragmented technical layers shipped across sprints without user-facing value. |
While Customer Journey Maps reveal qualitative operational friction, they do not provide the concrete architectural constraints needed to construct continuous delivery pipelines. Similarly, Event Storming excels at establishing domain boundaries and identifying event-driven pub/sub messaging patterns, but it stops short of organizing backlog tickets into release tiers.
User story mapping bridges this divide. It adapts the domain clarity discovered during Event Storming and translates it into an actionable, vertically sliced backlog that teams can safely ship to production staging environments.
Multi-Tenant Enterprise User Story Mapping Example
To examine the practical mechanics of a user story mapping example, consider a mission-critical B2B enterprise SaaS platform: a multi-tenant automated ledger dispatch, payment processing, and regulatory compliance platform. This architecture processes tenant-segregated financial data, enforces zero-trust access control, and integrates with legacy ERP systems via asynchronous event streams.
Enterprise Scenario: A financial platform must ingest enterprise ledger payloads from diverse tenants, validate schema conformance, execute credit facility sweeps, issue electronic tax invoices, and stream immutable audit logs to downstream compliance vaults.
End-to-End Enterprise Story Map Breakdown
| Backbone Activity | User / System Step | Walking Skeleton (Slice 1) | MVP / Release 1.0 (Slice 2) | Enterprise Scale / Release 2.0 (Slice 3) |
|---|---|---|---|---|
| 1. Tenant Provisioning & Auth | Onboard Tenant Organization | Hardcoded tenant ID provisioned via database seed scripts. | Self-serve organization portal with dynamic PostgreSQL schema creation. | SCIM 2.0 automated provisioning synchronized with Okta/Azure AD directories. |
| 1. Tenant Provisioning & Auth | Authenticate API Requests | Static API keys stored in Redis cache with manual invalidation. | HMAC SHA-256 signature validation with per-tenant rotating keys. | Mutual TLS (mTLS) with automated zero-trust certificate rotation via SPIFFE/SPIRE. |
| 2. Ledger Data Ingestion | Receive Transaction Batches | Synchronous HTTP POST endpoint accepting single JSON files up to 1MB. | Asynchronous S3 bucket ingestion triggered via bucket notifications and SQS queues. | Distributed Apache Kafka ingestion stream handling 50,000 events/second with idempotency keys. |
| 2. Ledger Data Ingestion | Schema Validation & Sanitization | Basic JSON Schema validation using an in-memory validator; drops invalid files. | Declarative validation engine yielding structured dead-letter queue (DLQ) records. | Streaming protobuf schema registry enforcement with self-healing data repair pipelines. |
| 3. Invoice Calculation Engine | Calculate Regional Taxes | Flat rate calculation hardcoded in application business logic. | Rule-based dynamic tax lookup table partitioned by regional ISO country codes. | Sub-millisecond integration with external tax compliance engines (Avalara / Vertex). |
| 3. Invoice Calculation Engine | Reconcile Account Balances | In-memory reconciliation thread executing inside a single service container. | Distributed locking via Redis (Redlock) across ledger-processing worker pods. | Distributed transactional saga powered by Temporal orchestrating multi-region balance sweeps. |
| 4. Settlement & Dispatch | Process Settlement Payment | Direct synchronous API call to a single payment gateway (Stripe). | Asynchronous gateway webhook reconciliation with automated exponential backoff retries. | Dynamic multi-rail payment router (Stripe, Adyen, ACH, SEPA) with fallback circuit breakers. |
| 4. Settlement & Dispatch | Dispatch Legal Invoice | Generates unformatted PDF document and sends via standard SMTP mail server. | HTML-to-PDF rendering engine depositing signed PDFs into secure S3 presigned URLs. | Cryptographically sealed PDF/A-3 invoices delivered via automated PEPPOL business networks. |
| 5. Audit & Observability | Export Audit Trails | Stdout log emission scraped via local FluentBit daemon. | Centralized query logging indexed in OpenSearch with 30-day retention policies. | WORM-compliant (Write Once, Read Many) tamper-evident storage with cryptographic Merkle trees. |
Observing this enterprise user story mapping example exposes the hazards of linear backlog planning. In a conventional flat backlog, engineers often spend three sprints building a distributed Kafka streaming pipeline (Activity 2, Slice 3) long before verifying that the payment settlement gateway (Activity 4, Slice 1) operates correctly under live network constraints.
By prioritizing the horizontal Walking Skeleton first, the team connects an end-to-end integration thread: a hardcoded tenant ingests a static JSON file, applies a basic tax rate, charges a test gateway, and emits a log event. The core system architecture is validated in production within the first two weeks of development.
Vertical Slicing Mechanics and Release Sizing
The single greatest operational hazard in modern software delivery is horizontal slicing: dividing work across architectural tiers such as database migrations in Sprint 1, API backend routing in Sprint 2, and user interface styling in Sprint 3. Horizontal slicing delays integration until the end of a milestone, creating integration bottlenecks, unmasked network failures, and unpredictable delivery timelines.
Vertical slicing cuts completely through all application layers for a narrow, well-defined user task. Every vertical slice incorporates continuous integration assets: updated database schemas, unit and integration tests, API contracts, backend logic, observability spans, and baseline front-end interfaces.
Applying the SPIDR Deconstruction Heuristic
When user story cards along the narrative backbone are too expansive to slot into a single release tier, engineering architects apply the SPIDR framework to systematically divide them:
- Spike: When a task carries unacceptable architectural ambiguity (for example, evaluating distributed cache performance between Dragonfly and Redis), timebox a 48-hour engineering spike to gather empirical benchmarks before slicing the functional workflow.
- Paths: Separate standard operational execution flows from secondary or failure paths. Slice the golden path first (for example, credit card charge succeeds), and defer alternative paths (chargeback processing, expired card fallbacks, card-declined notifications) to secondary release slices.
- Interfaces: Reduce technical friction by starting with streamlined interfaces. Deliver a headless, schema-validated command-line tool or REST API endpoint before committing frontend resources to a dynamic drag-and-drop dashboard interface.
- Data: Restrict the complexity, encoding diversity, or volume of data ingested by early slices. Build the pipeline to handle UTF-8 plain text or standard JSON schemas first; implement nested XML arrays, fragmented binary payloads, and multipart MIME documents in subsequent iterations.
- Rules: Relax business logic and regulatory policy constraints during early iterations. For example, build the transaction settlement engine with static domestic fee rules before layering on dynamic cross-border currency conversion, tariffs, and localized corporate discount tiers.
Vertical Slicing Governance Rule: If a proposed release slice cannot be deployed independently to an integration environment and tested by an automated test harness, it is a technical component, not a vertical slice. Reject horizontal layers and re-slice across the full delivery stack.
Translating Story Map Slices to Jira, GitHub, and Linear Hierarchies
To retain organizational clarity, modern engineering teams map the two-dimensional story map coordinates directly into their issue tracking systems using a structured hierarchy:
[Backbone Activity] --> Jira Initiative / Theme (Level 3) (e.g. Ledger Ingestion)
 [User Task / Step] --> Jira Epic / Feature (Level 2) (e.g. S3 Batch Polling)
 [Vertical Slice] --> Jira Story (Level 1) (e.g. Ingest Single CSV Payload)
 [Engineering] --> Jira Sub-task (Level 0) (e.g. Apply Flyway DB Migration)
By standardizing on this issue model, sprint planning transforms from arbitrary ticket voting into pulling a complete horizontal layer of stories directly from a single release slice on the story map.
Core Tenets from the User Story Mapping Book by Jeff Patton
Published in 2014, the seminal user story mapping book by Jeff Patton altered modern product development philosophy. Patton identified a systemic failure mode in agile engineering teams: treating user stories as written requirement documents rather than catalysts for shared conversation.
Teams frequently fall into the feature factory trap, prioritizing sprint velocity and story point burn-down charts over realized business outcomes. Patton’s core philosophy shifts product delivery metrics from raw software output to measurable customer value.
Patton’s Golden Axiom: “Minimize output, and maximize outcome and impact.” Software velocity is meaningless if the features deployed fail to resolve user problems or validate architectural hypotheses.
The Core Heuristics of Patton’s Framework
- Shared Understanding Over Shared Documents: Detailed requirement specification documents frequently lead to misaligned expectations. True engineering alignment occurs during the collaborative act of physically or digitally mapping the narrative backbone together.
- Vacillate Between Breadth and Depth: Never drill deep into technical specifications on step one before mapping the entire horizontal narrative backbone from beginning to end. Establishing breadth prevents premature optimization of secondary edge cases.
- Continuous Backlog Pruning: Backlogs naturally decay into unmanageable dumping grounds for abandoned ideas. A story map acts as a living, visual inventory that exposes obsolete tickets, redundant tasks, and unneeded architecture.
- Stop Estimating Individual Cards; Size Releases: Estimating isolated story points in a flat backlog yields inaccurate velocity metrics. Instead, evaluate the viability of the entire horizontal release slice to ascertain whether it achieves customer outcomes.
- Talk and Draw Simultaneously: Human memory drops complex technical nuance when communication is exclusively verbal. Mapping requirements visually as structured cards establishes an immutable, shared spatial memory across the entire team.
Mitigating Backlog Decay
Flat backlogs degrade predictably over time. As tickets age past 90 days, the initial discovery context evaporates, leaving engineers with obsolete Jira tickets requiring costly refinement meetings. In contrast, a user story map anchors every backlog item within a persistent horizontal narrative. If a task sits low on the vertical priority axis, its strategic value remains clear: it is an operational optimization preserved within the context of its parent workflow step, ready to be evaluated when that specific release slice moves into scope.
Engineering Trade-offs and Tooling Integration in 2026
In 2026, engineering teams rarely map user stories using physical sticky notes on whiteboards alone. Distributed engineering teams rely on digital canvases, native tracking synchronizations, and AI-assisted workflow engines. Selecting the appropriate tooling stack introduces measurable trade-offs across collaboration latency, architectural visibility, and administrative overhead.
| Tooling Category | Representative Platforms | Key Strengths | Operational Friction & Weaknesses |
|---|---|---|---|
| Infinite Canvas Tools | Miro, FigJam, Mural | Exceptional spatial collaboration; low entry barrier; optimal for rapid whiteboarding workshops. | Manual synchronization overhead; two-way state drift with Jira or GitHub Projects; lacks native CI/CD linking. |
| Native Story Mapping Plugins | Jira Align, Easy Agile, Avion | Direct two-way synchronization with issue databases; accurate sprint burndown tracking; native epic linking. | Slower UI rendering on large boards; rigid hierarchical constraints; higher licensing costs for enterprise seats. |
| Developer-Centric Issue Trackers | Linear, GitHub Projects, GitLab | Blazing fast keyboard-first workflows; native git branch and pull request linking; markdown-native tickets. | Lacks flexible 2D spatial narrative canvases; requires manual label conventions to simulate horizontal backbones. |
AI-Augmented Story Mapping Workflows
Modern engineering workflows leverage large language models to accelerate the initial construction of the story map backbone. Rather than initiating a workshop from an empty board, teams feed structured customer interview transcripts, technical RFCs, and regulatory mandates into LLMs using tailored system prompts:
SYSTEM PROMPT: You are a Principal Systems Architect and Staff Product Manager.
TASK: Parse the attached raw customer interview transcript for a multi-tenant B2B payments portal.
OUTPUT FORMAT: Return a valid JSON object matching the following structure:
{
 "backbone_activities": [
 {
 "name": "String (High-level user goal)",
 "chronological_order": 1,
 "user_steps": [
 {
 "step_name": "String (Actionable interaction)",
 "walking_skeleton_task": "String (Thinnest functional slice)",
 "mvp_task": "String (Core commercial functionality)",
 "growth_task": "String (Scale / automation / resilience)"
 }
 ]
 }
 ]
}
CONSTRAINTS: Strictly adhere to vertical slicing principles. Do not generate horizontal architectural layers (e.g. 'Build Database Schema'). Every task must yield an end-to-end testable functional capability.
Using automated extraction pipelines, teams convert hours of unstructured user discovery audio into an initial 2D story map draft within minutes. The core engineering team then steps in to refine architectural boundaries, validate edge-case constraints, and establish delivery feasibility.
Production Story Mapping Governance Checklist
- The horizontal backbone is finalized and peer-reviewed by architecture leads before estimating vertical slices
- Every vertical release slice includes automated end-to-end integration test definitions
- Zero orphan tasks: every card in the issue tracker links directly to an overarching Step and Activity
- Bidirectional syncing between digital visual canvases (Miro/FigJam) and issue trackers (Jira/Linear) runs automatically via webhooks to prevent state drift
- Release cutlines are evaluated against real production telemetry after each deployment phase
Frequently Asked Questions
What is user story mapping?
User story mapping is a two-dimensional backlog management method where user activities form a horizontal chronological backbone, and user stories hang vertically beneath them ordered by release priority. It ensures software teams build coherent, usable vertical slices rather than fragmented components.
What is an end-to-end user story mapping example?
An end-to-end user story mapping example features activities like User Onboarding, Transaction Ingestion, and Reporting along the top. Beneath Ingestion, prioritized tasks range from manual CSV uploads in the initial release slice to automated webhooks and real-time Kafka event streaming in later releases.
Why is the user story mapping book by Jeff Patton still essential?
Jeff Patton’s user story mapping book established the standard framework for collaborative product discovery. It shifts engineering cultures from tracking raw feature velocity to measuring customer outcomes, proving that shared mental models trump detailed requirement specification documents every time.
How does story mapping differ from a customer journey map?
A customer journey map explores user sentiment, emotional friction, and touchpoints across marketing and product ecosystems. A story map is an operational engineering delivery tool focused on technical scope, feature breakdown, functional dependencies, and vertical release scheduling.
User story mapping rescues engineering organizations from the cognitive trap of flat, unmanageable backlogs. By organizing requirements across a two-dimensional grid of user steps and vertical priority slices, teams build shared mental models, validate system architectures early via walking skeletons, and deliver measurable software value at every sprint boundary.
Transition your team away from one-dimensional ticket queues. Schedule an operational story mapping workshop, anchor your horizontal narrative backbone, slice your releases vertically down to their thinnest executable paths, and deploy resilient, outcome-focused architectures to production.