
In the high-throughput world of 2026, the performance of an AI application is defined by the latency of its retrieval layer. A pine cone vector database serves as the backbone for these systems, abstracting the complexities of high-dimensional indexing and allowing engineering teams to focus on model orchestration rather than cluster management.
This guide deconstructs the architectural requirements for integrating vector storage into production pipelines. We move past the marketing hype to examine the mechanical sympathy required to operate these systems at scale, focusing on data sharding, latency optimization, and the trade-offs inherent in managed vector infrastructure.
Foundational Concepts of the Pine Cone Vector Database
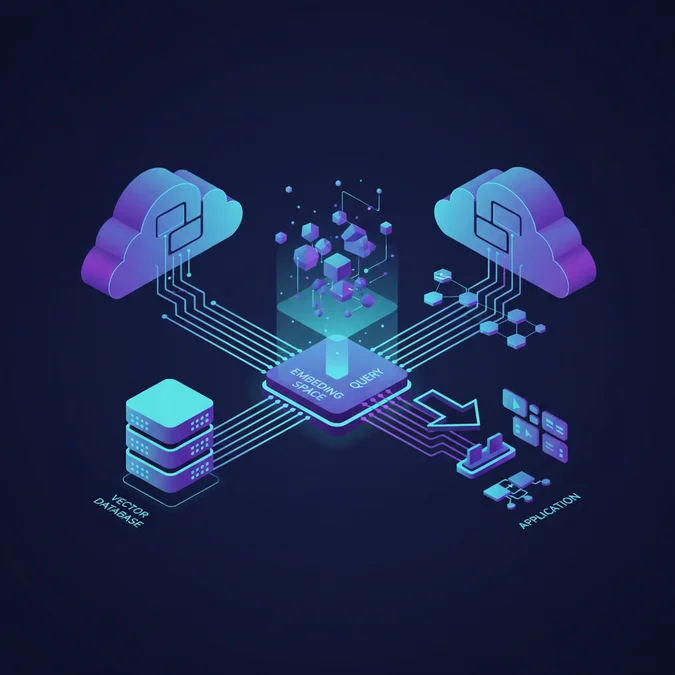
At its core, a pine cone vector database functions as an inverted index for embeddings. Unlike relational databases that index on scalar values, this architecture relies on Approximate Nearest Neighbor (ANN) algorithms to navigate high-dimensional space efficiently. The system transforms raw data into dense vectors, which are then mapped into an index that facilitates sub-millisecond retrieval.
Technical Note: The effectiveness of a pine cone vector database is bound by the quality of the embedding model. Ensure your input vectors are normalized to unit length if using cosine similarity to prevent drift in retrieval accuracy.
The system operates by decoupling the storage of metadata from the vector index, allowing for hybrid queries where developers can filter by scalar attributes while performing vector similarity searches. This dual-indexing capability is essential for filtering context in RAG (Retrieval-Augmented Generation) pipelines.
Engineering Trade-offs: Pine Cone Vector vs Alternatives
Selecting the right backend requires balancing operational overhead against query performance. The following matrix compares the pine cone vector ecosystem against other common approaches based on production-grade benchmarks.
| Feature | Pinecone | pgvector | Milvus |
|---|---|---|---|
| Management | Fully Managed | Self-Hosted/RDS | Self-Hosted/Cloud |
| Scaling | Automatic | Manual Partitioning | Sharded Clusters |
| Latency | Low (Global) | Moderate | Low (Configurable) |
| Maintenance | Near Zero | High | High |
While pgvector is an excellent choice for existing Postgres-heavy stacks, it often hits performance ceilings as vector counts exceed millions. Pinecone’s managed approach removes the need for manual vacuuming and index tuning, though it introduces a dependency on managed service availability.
Implementing High-Performance Pipelines with a Pine Cone Database
To build a production-ready RAG pipeline, you must handle embedding generation and upsert logic with robust error handling. Use the following implementation pattern to ensure your pine cone database integration remains resilient.
- Configure the index with the correct metric (cosine, euclidean, or dotproduct) to match your embedding model.
- Batch your upserts to stay within payload size limits, typically keeping batches under 100 vectors per request.
- Implement an exponential backoff strategy for network-related retries.
import pinecone
from langchain_openai import OpenAIEmbeddings

# Initialize client
pc = pinecone.Pinecone(api_key="YOUR_KEY")
index = pc.Index("production-index")

def upsert_document(text, metadata):
 embedding = OpenAIEmbeddings().embed_query(text)
 try:
 index.upsert(vectors=[{"id": "doc_01", "values": embedding, "metadata": metadata}])
 except Exception as e:
 print(f"Upsert failed: {e}")
 # Implement retry logic here
Operational Best Practices for Production Scale
Operating at scale requires moving beyond default configurations. Managing latency and index health is a day-two necessity.
- Shard Management: Monitor the namespace distribution to ensure even load across physical pods.
- Metadata Filtering: Leverage selective filtering to reduce the search space before calculating vector similarity.
- Index Warm-up: For high-traffic applications, ensure your index is warm by running a small set of baseline queries before routing production traffic.
- Monitoring: Track the ‘request_latency’ and ‘pod_utilization’ metrics in your dashboard to preemptively scale resources.
Factors That Affect Development Cost
- Index pod size and count
- Data ingestion throughput
- Query volume per second
- Metadata storage overhead
Costs scale linearly with the number of vectors and the frequency of read/write operations.
Frequently Asked Questions
What is a pine cone vector database used for?
A pine cone vector database is designed for storing and retrieving high-dimensional vector embeddings generated by machine learning models. It enables fast similarity search, which is essential for building Retrieval Augmented Generation (RAG) applications, semantic search engines, and personalized recommendation systems at massive scale.
How does pine cone vector search differ from traditional keyword search?
Traditional keyword search relies on exact text matches, whereas pine cone vector search uses mathematical representations of data. This allows the system to find conceptually similar content even if the specific words do not overlap, providing more relevant results in natural language processing tasks.
Is a pine cone database suitable for small-scale projects?
Yes, a pine cone database is highly scalable, offering serverless options that are cost-effective for small projects while remaining capable of handling billions of vectors. Engineers often choose it because it simplifies infrastructure management, allowing teams to focus on application logic rather than database maintenance.
Architecting with a managed vector backend requires a shift in mindset from traditional database management toward high-dimensional data governance. By focusing on embedding quality, batching efficiency, and intelligent filtering, you can build systems that remain performant as your dataset grows into the billions.
As you move to production, prioritize observability in your retrieval pipeline. Continuous monitoring of your similarity search latency will provide the feedback loop needed to optimize index configurations and ensure your AI workflows deliver consistent, low-latency results.