
A high-velocity projectile tunnelling clean through a thin wall is the quintessential failure mode of discrete collision detection. In production environments, whether orchestrating thousands of destructible assets at 120 FPS or validating torque vectors on a simulated robotic arm, physics simulation requires navigating mathematical compromises between numerical accuracy, computational complexity, and unconditionally stable state integration.
Building a robust physical world requires moving far beyond basic Newtonian equations. Modern real-time and scientific simulations rely on specialized numerical integrators to preserve system energy, spatial acceleration structures to cull millions of potential contact points, and iterative constraint solvers like Extended Position Based Dynamics (XPBD) or Projected Gauss-Seidel to resolve deep penetrations without explosive divergence.
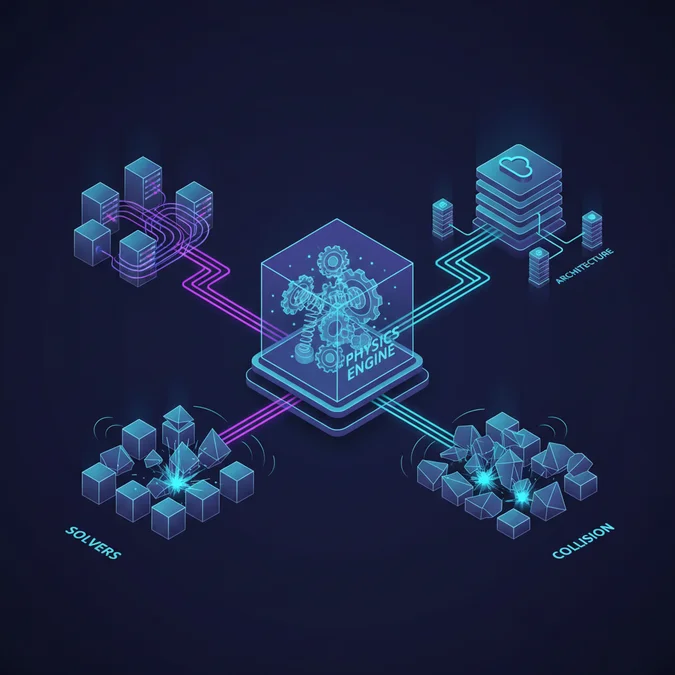
This architectural guide breaks down the core execution pipeline of modern simulation engines. From the mathematics of symplectic integrators to GPU-accelerated collision pipelines, we examine the structural decisions that govern state updates across game engines, robotics frameworks, and high-fidelity multiphysics modeling environments.
Core Mechanics: Mathematical Foundations of Real-Time Physics Simulation
Every physics simulation processes motion through numerical integration: evaluating dynamic state variables (position, velocity, acceleration) across discrete intervals of time. In an ideal continuous system, motion obeys ordinary differential equations (ODEs). In discrete computational engines, calculating the next state vector demands an integration scheme that balances algorithmic throughput with long-term energy conservation.
Explicit numerical methods, such as Explicit Euler, compute the future state strictly from current velocity and acceleration:
v_{t+dt} = v_t + a_t * dt
x_{t+dt} = x_t + v_t * dt
Explicit Euler is catastrophic for stiff constraint systems or oscillatory motion. It injects artificial kinetic energy at every timestep, causing springs to explode and orbits to spiral outward. In contrast, Semi-Implicit Euler (also known as Symplectic Euler or Euler-Cromer) evaluates the updated velocity before computing the new position:
v_{t+dt} = v_t + a_t * dt
x_{t+dt} = x_t + v_{t+dt} * dt
This simple shift turns the operator into a symplectic map. A symplectic integrator preserves the phase space volume of Hamiltonian systems, ensuring that total mechanical energy oscillates within bounded limits rather than drifting toward infinity. Consequently, Semi-Implicit Euler serves as the standard baseline for real-time game loops.
For applications demanding higher orders of positional accuracy, fourth-order Runge-Kutta (RK4) evaluates four intermediate derivative approximations per timestep. However, RK4 is non-symplectic and computationally prohibitive for systems with discontinuous velocity jumps, such as sudden rigid-body contacts. When rigid structures collide, continuous ODEs break down, requiring dedicated constraint solvers.
Architectural Insight: Real-time engines avoid high-order non-symplectic integrators like RK4 during impact-heavy scenarios. Discontinuous impulse changes violate the smoothness assumptions of Runge-Kutta, driving engines toward first-order symplectic integrators paired with iterative constraint projections.
Once positions and unconstrained velocities are integrated, external contacts and articulation joints impose kinematic constraints. Modern engines formulate these interactions as Linear Complementarity Problems (LCP) solved via Projected Gauss-Seidel (PGS), or as non-linear positional equations solved via Extended Position Based Dynamics (XPBD). The following implementation demonstrates a production-grade, thread-safe XPBD distance constraint solver, which eliminates mass-dependent stiffness tuning by scaling elastic compliance by the squared timestep.
#include <cstdint>
#include <cmath>
#include <algorithm>

struct Vec3 {
 float x, y, z;
 Vec3 operator+(const Vec3& o) const { return {x + o.x, y + o.y, z + o.z}; }
 Vec3 operator-(const Vec3& o) const { return {x - o.x, y - o.y, z - o.z}; }
 Vec3 operator*(float s) const { return {x * s, y * s, z * s}; }
 float dot(const Vec3& o) const { return x * o.x + y * o.y + z * o.z; }
 float length() const { return std:sqrt(dot(*this)); }
};

struct Particle {
 Vec3 position;
 Vec3 previous_position;
 Vec3 velocity;
 float inverse_mass; // 0.0 indicates infinite mass (kinematic/static)
};

class XPBDDistanceConstraint {
public:
 XPBDDistanceConstraint(uint32_t p1, uint32_t p2, float target_dist, float compliance): particle_a(p1), particle_b(p2), rest_length(target_dist), alpha(compliance), lambda(0.0f) {}

 void solve(Particle* particles, float dt) {
 Particle& p1 = particles[particle_a];
 Particle& p2 = particles[particle_b];

 float w_total = p1.inverse_mass + p2.inverse_mass;
 if (w_total <= 0.0f) {
 return;
 }

 Vec3 delta = p1.position - p2.position;
 float current_length = delta.length();
 if (current_length < 1e-6f) {
 return;
 }

 // Positional constraint: C(x) = |x1 - x2| - d
 float constraint_value = current_length - rest_length;
 Vec3 normal = delta * (1.0f / current_length);

 // Compliance scaled by squared timestep
 float alpha_tilde = alpha / (dt * dt);

 // Compute Lagrange multiplier increment
 float delta_lambda = (-constraint_value - alpha_tilde * lambda) / (w_total + alpha_tilde);
 lambda += delta_lambda;

 Vec3 correction = normal * delta_lambda;
 p1.position = p1.position + (correction * p1.inverse_mass);
 p2.position = p2.position - (correction * p2.inverse_mass);
 }

 void reset_lagrange() { lambda = 0.0f; }

private:
 uint32_t particle_a;
 uint32_t particle_b;
 float rest_length;
 float alpha; // Inverse stiffness: 0.0 = completely rigid
 float lambda; // Accumulated Lagrange multiplier
};
This formulation ensures that constraint stiffness remains invariant regardless of the engine’s update frequency. It allows high-fidelity physics sim workloads to execute with temporal stability under variable framerates.
Taxonomy of Modern Physics Simulation Software Across Industries
Engineers evaluating physics simulation software encounter vastly different paradigms depending on whether the workload targets competitive multiplayer games, autonomous robotics testing, or engineering-grade structural dynamics. Game-centric physics modeling software trades absolute floating-point precision for computational efficiency and determinism. Conversely, scientific simulators enforce rigorous energy conservation and continuous contact formulations that tolerate higher frame computation times.
Understanding where a framework sits along the precision-throughput spectrum determines architectural fit, runtime resource allocation, and continuous integration constraints.
| Engine / Framework | Target Domain | Core Mathematical Method | Target Latency | Primary Limitations |
|---|---|---|---|---|
| NVIDIA PhysX 5 | Real-Time Games, Autonomous Machines | TGS (Temporal Gauss-Seidel) & PBD | < 8 ms | Closed GPU-compute backends; memory overhead on mobile |
| Jolt Physics | Open-World Games, VR | Iterative Impulse Solver with SIMD focus | < 4 ms | Limited soft-body and complex cloth support |
| MuJoCo | Robotics, Biomechanics, RL | Generalized Coordinates & Convex Optimization | 10 to 50 ms | Suboptimal for non-convex mesh destruction and complex game dynamics |
| NVIDIA Isaac Sim | Synthetic Training Environments, Robotics | GPU Tensor Core Dynamics (PhysX base) | Batch parallel | Strict workstation GPU dependency (RTX architecture) |
| Project Chrono | Vehicle Dynamics, Multiphysics | Differential Algebraic Equations (DAE) | > 100 ms (Offline/HPC) | Incompatible with real-time interactive game loops |
Production Engine Selection Checklist
- Determinism Demands: If building lockstep multiplayer engines, ensure the solver operates without dynamic memory allocation or nondeterministic thread scheduling. Jolt and PhysX provide strict CPU paths; GPU-accelerated pipelines rarely guarantee bit-exact cross-hardware parity.
- Contact Formulations: Robotics pipelines requiring sub-millimeter grasp prediction require generalized coordinate solvers (MuJoCo, Drake) that eliminate joint drift entirely. Gaming pipelines prefer maximal coordinate solvers (PhysX, Havok) for faster processing of thousands of unconstrained free bodies.
- Soft-Rigid Coupling: Evaluate whether your cloth, cable, or fluid systems must back-react bidirectionally on rigid geometries. Unified solvers (PBD/XPBD) resolve these couplings natively in a single phase, avoiding complex co-simulation synchronization overhead.
The Geometry Pipeline: Broadphase, Narrowphase, and Continuous Collision Detection
Calculating collisions between every pair of colliders in an N-body environment generates O(N^2) geometric tests. At scale, this quickly bottlenecks CPU and GPU execution pipelines. High-performance 3d physics simulation software divides collision handling into a multi-tiered spatial architecture:
+---------------------------------------------------------+
| Broadphase (Dynamic BVH / SAP) |
| - Axis-Aligned Bounding Box (AABB) overlap testing |
| - Output: Candidate Overlap Pairs (O(N log N)) |
+---------------------------------------------------------+
 |
 v
+---------------------------------------------------------+
| Narrowphase (GJK / EPA / SAT) |
| - Exact convex hull distance and contact point finding |
| - Output: Contact Manifolds (Points, Normals, Depth) |
+---------------------------------------------------------+
 |
 v
+---------------------------------------------------------+
| Continuous Collision Detection (Swept / TOI) |
| - Time-of-Impact calculations for high-velocity bodies |
| - Prevents spatial tunneling across discretizations |
+---------------------------------------------------------+
Broadphase: Dynamic AABB Trees
The broadphase eliminates non-colliding pairs rapidly by enclosing complex convex shapes within simple Axis-Aligned Bounding Boxes (AABBs). Modern architectures utilize dynamic Bounding Volume Hierarchies (BVHs), often organized as balanced binary trees. When a body translates or rotates, its node in the BVH updates, triggering local tree rotations to preserve surface-area heuristic (SAH) efficiency without full spatial rebuilds.
Narrowphase: Gilbert-Johnson-Keerthi and Expanding Polytope Algorithms
Once the broadphase flags potential contact, the narrowphase determines exact geometric intersections. The Gilbert-Johnson-Keerthi (GJK) algorithm determines whether two convex sets intersect by evaluating their Minkowski difference: A (-) B = { x - y | x in A, y in B }. If the origin of coordinate space lies within the Minkowski difference set, the two original convex hulls penetrate.
When GJK confirms penetration, the engine switches to the Expanding Polytope Algorithm (EPA) to determine the minimum translational distance required to separate the colliders. EPA iteratively expands a simplex outward toward the boundary of the Minkowski sum to calculate the penetration depth vector and surface contact normal.
Continuous Collision Detection (CCD)
Discrete time integration samples object locations at static intervals. If an entity moves faster than its own bounding volume per frame, it passes entirely through thin static geometry: a breakdown known as tunneling. Modern engines prevent this via Swept Volume tests or Conservative Advancement to compute the exact Time of Impact (TOI).
#include <algorithm>

struct Ray { Vec3 origin; Vec3 direction; };
struct Sphere { Vec3 center; float radius; };

// Conservative continuous collision check for a moving sphere against a static plane
bool swept_sphere_vs_plane(
 const Sphere& sphere,
 const Vec3& velocity,
 const Vec3& plane_normal,
 float plane_distance,
 float dt,
 float& out_toi
) {
 float denom = plane_normal.dot(velocity);

 // Sphere moving parallel to or away from the plane
 if (denom >= -1e-6f) {
 return false;
 }

 float dist_current = plane_normal.dot(sphere.center) - plane_distance;

 // Already penetrating at start of step
 if (dist_current < sphere.radius) {
 out_toi = 0.0f;
 return true;
 }

 // Calculate precise time of impact along normalized velocity vector
 float t = (dist_current - sphere.radius) / (-denom);
 if (t >= 0.0f && t <= dt) {
 out_toi = t;
 return true;
 }

 return false;
}
Performance Warning: Continuous collision detection adds notable compute overhead. Enable full continuous swept hulls exclusively on fast-moving physical instigators (such as small projectiles or vehicle chassis) while evaluating static props using standard discrete sweeps.
Rigid Bodies vs Soft Bodies: Selecting the Right Physics Simulation Program
A rigid body assumes infinite internal stiffness: the distance between any two internal coordinate vertices remains completely invariant under external loads. This assumption simplifies dynamics into 6 degrees of freedom (DOF) per body: three translational axes, and three rotational axes managed through quaternion orientation. However, when evaluating deformable objects like soft tissues, cloth, or thin membranes, a physics simulation program must transition from rigid mechanics to continuum modeling.
Deformable surface and volumetric simulations rely on two primary competing numerical representations: Position Based Dynamics (PBD/XPBD) and the Finite Element Method (FEM).
| Metric / Property | Rigid Body Dynamics | XPBD Soft Bodies | Non-Linear FEM |
|---|---|---|---|
| Degrees of Freedom (DOF) | 6 per body | 3 per vertex (often thousands) | 3 per node across volume continuum |
| Material Non-Linearity | N/A (Rigid) | Approximated via non-linear constraints | Exact via hyperelastic strain tensors |
| Volume Conservation | Absolute (by definition) | Tetrahedral volume constraints | Rigorous Poisson ratio preservation |
| Computational Budget | Low (< 0.05 ms per body) | Moderate (1 – 5 ms per asset) | High (50 – 500+ ms per asset) |
| Numerical Stability | Medium (Prone to joint fighting) | Unconditionally stable | Sensitive to mesh inversion |
Evaluating Continuum Solvers for Production Pipelines
- Finite Element Method (FEM): Approximates continuous bodies by discretizing solid 3D volumes into tetrahedral volumetric elements. Strains and stresses are calculated using continuum mechanics equations (e.g. Neo-Hookean or Mooney-Rivlin models). FEM is critical for surgical simulation and engineering crash testing, but its matrix inversions limit real-time gaming deployments.
- Extended Position Based Dynamics (XPBD): Eliminates force integrations altogether, projecting non-linear position updates straight onto vertices while accounting for mass-weighted compliance. It delivers stable performance for dynamic cloth and soft-body characters, making it the preferred standard for interactive software.
- Mass-Spring Systems: Although simple to implement, traditional mass-spring approximations struggle with cross-axis shear resistance and suffer from numerical instability under low structural damping. They have largely been superseded by modern XPBD pipelines.
Hardware Acceleration and Multithreading: SIMD, GPU Pipelines, and Determinism
Modern physical simulations rarely hit limits due to simple FLOP execution capacity. Instead, the primary bottlenecks are memory bandwidth, cache line invalidation, and synchronization barriers across CPU cores. Scaling a simulation loop to tens of thousands of dynamic colliders requires restructuring processing loops around Data-Oriented Design (DOD) principles.
SIMD Vectorization and Cache Optimization
Standard Object-Oriented layouts, where a single RigidBody class encapsulates transform data, mass tensors, and geometry pointers, scatter memory references across heap space. This structure triggers frequent CPU cache misses. Modern high-throughput engines isolate operational data into contiguous, structure-of-arrays (SoA) memory blocks:
// Cache-unfriendly Array of Structures (AoS) - High latency cache misses
struct RigidBodyAoS {
 float transform[16];
 float linear_velocity[3];
 float angular_velocity[3];
 float inverse_mass;
 float inertia_tensor[9];
};

// Cache-friendly Structure of Arrays (SoA) - AVX-512 vectorizable
struct RigidBodySoA {
 float* pos_x;
 float* pos_y;
 float* pos_z;
 float* vel_x;
 float* vel_y;
 float* vel_z;
 float* inv_mass;
};
By packing positional axes and mass metrics into contiguous arrays, SIMD instruction sets (such as AVX-2, AVX-512, or ARM NEON) can compute updates for eight to sixteen particles simultaneously within a single CPU cycle.
GPU Compute Pipelines: CUDA and DirectCompute
Massively multi-agent simulations, such as particle fluids (Smoothed Particle Hydrodynamics), granular soils, and reinforcement learning environments, move integration and collision resolution entirely onto the GPU. Engines construct parallel spatial hashing grids in VRAM. Every thread calculates updates for a single element, resolving local cell interactions with zero CPU round-trip stalls.
Architecture Rule for Networking: GPU execution architectures are non-deterministic across different hardware lines due to variations in workgroup scheduling, dynamic warps, and native floating-point Fused Multiply-Add (FMA) order. To maintain multiplayer synchronization without continuous state corrections, isolate the physical simulation strictly to fixed-point operations on the CPU.
Deterministic Lockstep Execution
Competitive multiplayer games, rollback networking (e.g. GGPO), and distributed simulation engines demand deterministic synchronization. Two machines given identical control inputs must arrive at bit-exact, identical physical coordinates. Achieving deterministic physics requires enforcing four core pipeline rules:
- Fixed Timestep Updates: Never pass variable delta-times (
dt) into the integration pipeline. Decouple render loops from physics updates by running a fixed accumulation clock (such as a locked 60 Hz or 120 Hz tick). - Deterministic Memory and Task Allocation: Contact manifolds and island solvers must be sorted by unique identifiers prior to constraint processing. Running iterative constraint solvers across un-ordered multi-threaded queues introduces floating-point drift based on thread competition.
- IEEE-754 Normalization: Configure compilers with strict mathematical flags (e.g.
/fp:precisein MSVC or-ffp-contract=offin Clang/GCC) to prevent the generation of non-deterministic fused multiply-add operations across CPU platforms. - Fixed-Point Formulations: For strict cross-platform lockstep architectures connecting mobile ARM and desktop x86 systems, replace standard 32-bit floating-point coordinates with deterministic fixed-point math libraries.
Frequently Asked Questions
What is the primary difference between a game physics sim and scientific simulation software?
Game physics engines prioritize real-time performance, numerical stability, and visual plausibility at 60 Hz or higher. Scientific simulation software emphasizes absolute numerical accuracy, energy conservation, and microsecond convergence using explicit differential equations and finite element analysis.
How do developers choose the best physics simulation software for robotics?
Robotics platforms demand continuous contact modeling, sub-millimeter precision, and seamless sensor integration. Engines like MuJoCo, Isaac Sim, and Drake are favored over gaming engines because they handle generalized coordinates, smooth contact transitions, and parallel GPU environments for reinforcement learning.
Can 3D physics simulation software achieve deterministic results across different platforms?
Deterministic execution across heterogeneous platforms requires strictly identical floating-point rounding modes, fixed timestep integration, and sorted collision manifolds. Most teams enforce soft determinism or utilize fixed-point arithmetic solvers to guarantee reproducible state synchronization across different operating systems and CPU architectures.
Why is XPBD replacing traditional impulse-based physics modeling software in games?
Extended Position Based Dynamics (XPBD) eliminates mass-dependent tuning issues, solves positional constraints directly, and provides unconditional stability under large timesteps. This makes XPBD ideal for cloth, ropes, and combined soft-rigid body systems where traditional impulse solvers often diverge.
Modern physics simulation is defined by engineering trade-offs. Choosing an architectural path requires balancing the strict physical realism of continuous ODE solvers against the hard performance constraints of real-time execution loops. While engineering crash tests and robotic sensor validation demand microsecond-accurate contact mechanics, interactive media and gaming rely on symplectic Euler approximations, spatial tree culling, and unconditionally stable XPBD solvers to maximize stability.
As physical engines increasingly transition toward GPU-accelerated compute shaders and data-oriented CPU scheduling, maintaining cross-platform determinism and stable multi-threading remains essential. Designing decoupled simulation layers with fixed integration timesteps, spatial hierarchy partitioning, and memory-aligned layouts ensures that your physics pipeline scales reliably across diverse modern hardware.
Benchmarking Architecture Trade-offs?
Discuss real-world performance characteristics and production considerations for your specific workload.