
A Kafka producer is an asynchronous client engine designed to serialize, batch, and dispatch events to distributed broker partitions with strict delivery semantics. In high-volume event streams, a naive client configuration will exhaust system buffers, drop records under network partitions, or introduce unexpected serialization bottlenecks long before saturating the underlying broker cluster.
Achieving predictable performance requires mechanical sympathy with the producer internal subsystems: the thread boundary dividing the calling application from the background I/O loop, the memory-recycling mechanics of the RecordAccumulator, and the broker protocol coordinating idempotent handshakes. In modern Apache Kafka architectures, default settings have shifted decisively toward zero-data-loss guarantees, making an exact understanding of memory pools, backpressure, and transport configuration essential.
This technical reference deconstructs the internal write path of the Kafka producer, evaluates critical client properties, provides production-grade Java and Python patterns, and supplies empirical tuning matrices balancing sustained gigabyte-scale throughput against sub-millisecond dispatch latencies.
Internal Pipeline: How the Kafka Producer Publishes Records
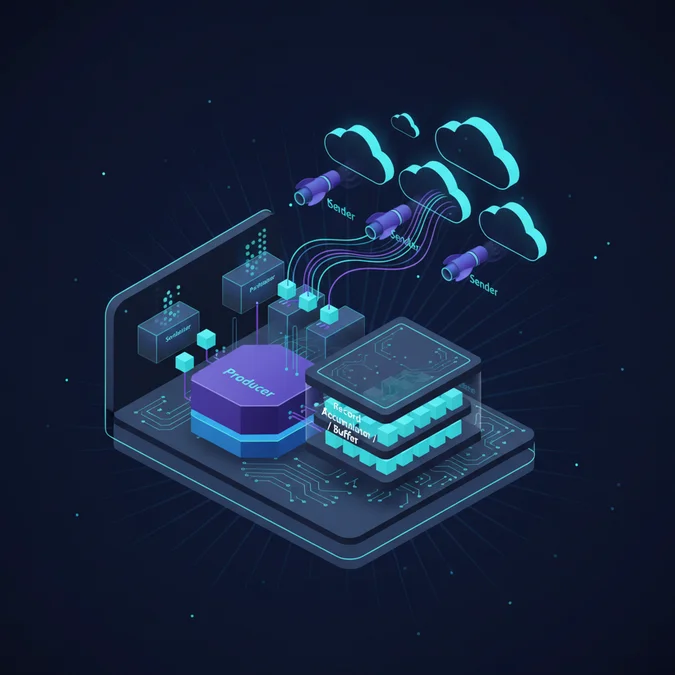
Publishing an event through the kafka producer looks like a single atomic function call from the application layer: producer.send(record). Under the hood, this invocation triggers a non-blocking, multi-stage pipeline partitioned across two distinct execution domains: the user application thread and the background Sender I/O daemon thread.
+-----------------------------------------------------------------------------------------+
| APPLICATION THREAD SPACE |
| |
| +------------------+ +-------------------+ +--------------------------------+ |
| | ProducerRecord | --> | Interceptors | --> | Serializer | |
| | (Topic, Key, V) | | (OnSend / Audit) | | (Key / Value to byte[]) | |
| +------------------+ +-------------------+ +---------------+----------------+ |
| | |
| v |
| +----------------+ |
| | Partitioner | |
| | (Murmur2/RR) | |
| +-------+--------+ |
+---------------------------------------------------------------------|-------------------+
 v
+-----------------------------------------------------------------------------------------+
| RECORD ACCUMULATOR |
| |
| Topic: payments-v1 |
| Partition 0: [ Batch 1 (Full) ] -> [ Batch 2 (Filling) ] -> [ BufferPool Page ] |
| Partition 1: [ Batch 1 (Filling) ] |
| Partition 2: [ Batch 1 (Full) ] -> [ Batch 2 (Full) ] |
+---------------------------------------------------------------------+-------------------+
 |
 DRAIN BATCHES VIA SOCKETS v
+-----------------------------------------------------------------------------------------+
| BACKGROUND SENDER THREAD |
| |
| +--------------------+ +---------------------+ +----------------------------+ |
| | In-Flight Requests | --> | NetworkClient | --> | Kafka Broker Sockets |
| | (Max: 5 per Node) | | (Java NIO Selector) | | (Leader Partitions) | |
| +--------------------+ +---------------------+ +----------------------------+ |
+-----------------------------------------------------------------------------------------+
The journey of every message through this pipeline follows an orchestrated, six-step sequence designed to prevent garbage-collection thrashing and maximize network bandwidth utilization:
- Producer Interceptors: The record passes through any configured
ProducerInterceptorinstances. These run synchronously within the calling thread, enabling distributed tracing injection (such as W3C Trace Context headers) or client-side payload auditing prior to mutation. - Key and Value Serialization: The record key and payload are converted into raw byte arrays using designated serializers (such as Apache Avro, Protobuf, or custom byte mappers). If schema registries are configured, this stage validates the schema fingerprint against the registry cache.
- Partition Assignment: The partitioner determines the target broker partition. If an explicit partition is specified in the
ProducerRecord, it is respected. If omitted and a key exists, the default partitioner computes a 32-bit Murmur2 hash of the serialized key bytes, executing a modulo operation against the count of active topic partitions. If no key is provided, modern Kafka clients utilize the built-in sticky partitioning strategy, packing records into the current batch until it reaches capacity before switching partitions to minimize fragmentation. - Accumulator Append and Buffer Allocation: The serialized record enters the
RecordAccumulator. The accumulator groups records into partition-specific double-ended queues (deques) containing batches sized tobatch.size(defaulting to 16 KB). Memory for these batches is managed by an internalBufferPoolallocating total heap space equal tobuffer.memory(defaulting to 32 MB). Reusing pooledByteBufferinstances eliminates the continuous allocation and deallocation overhead that otherwise triggers Java virtual machine stop-the-world pauses. - Sender Thread Execution: Running asynchronously in a separate daemon thread, the
Senderiterates through ready batches in the accumulator, transforms them into low-level client socket requests, and hands them off to the internalNetworkClientbacked by Java NIO selectors. - Broker Dispatch and In-Flight Accounting: The
NetworkClienttransmits the socket frames to the leader brokers for each partition. Up tomax.in.flight.requests.per.connection(default: 5) unacknowledged request pipelined packets are permitted concurrently per TCP connection while maintaining strict in-order guarantees under idempotency.
Architecture Rule: The handoff between the user thread and the Sender thread inside
RecordAccumulatoris the single most common failure point under high load. If the application thread produces data faster than the Sender thread can drain it across the network, theBufferPoolruns dry, blocking application threads up tomax.block.msbefore throwing a fatalTimeoutException.
Decoupled Event Streaming: Kafka Producer Consumer Dynamics
Event-driven topologies rely on a decoupled publish-subscribe contract between the kafka producer consumer boundaries. Unlike traditional message queues where a broker broker tracks individual message consumption and deletes acknowledged items, Kafka persists an immutable distributed append-only write-ahead log. This divergence dictates how producers and consumers coordinate around throughput, partition scale, and partition assignment.
Producers operate in a push model: they dictate write throughput, log segmentation, and partition distribution. Consumers run in a pull model: organized into cooperative consumer groups, they govern their read cadence by fetching batches from partition leaders and committing absolute log offsets.
| Architectural Dimension | Kafka Producer Mechanics | Kafka Consumer Mechanics |
|---|---|---|
| Data Flow Direction | Push (Client initiates write to partition leader) | Pull (Client polls broker sockets on scheduled loop) |
| State and Tracking | Stateless regarding historic logs; tracks in-flight batches, sequence numbers, and PID | Stateful; tracks partition assigned offsets, commit generation, and consumer group epochs |
| Scaling Bottlenecks | Network socket egress, BufferPool exhaustion, CPU serialization, batch compression overhead | Partition skew, long garbage-collection pauses triggering heartbeat timeouts, rebalance storms |
| Partition Coupling | Can write to any partition across topics dynamically using partitioners | Bounded strictly by partition count: active consumers per group cannot exceed topic partitions |
| Delivery Semantics | Configured via acks (0, 1, all) and enable.idempotence | Configured via offset commit strategies (at-most-once, at-least-once, transactional read_committed) |
Because the producer establishes partition distribution, it inherently dictates the downstream parallelization capacity of the consumer group. If a producer leverages an unbalanced partitioning key, data skews heavily into a small subset of partitions. Downstream, the specific consumer instances assigned to those saturated partitions will fall behind, suffering runaway consumer lag while other group members sit idle.
Operational Insight: Producers should never be coupled to consumer group scale. However, engineers must provision enough partition headroom up front. While producers seamlessly handle dynamic partition expansions, adding partitions to an existing keyed topic breaks Murmur2 hash consistency, redirecting identical keys to different partitions and invalidating strict partition-level consumption ordering.
Essential Kafka Producer Properties for Durability and Speed
Configuring a client for reliable production operation demands fine-tuning specific kafka producer properties. Historically, older Kafka versions defaulted to performance-first settings that could compromise data safety, such as non-idempotent delivery and loose acknowledgments. Modern versions establish a durable-by-default baseline that must be understood before adjusting for specialized edge cases.
Understanding both canonical and camelCase shorthand representations of kafkaproducer properties ensures systems operate predictably across varying platform runtimes:
| Configuration Property | Default Value | Production Range | Impact on Durability and Latency |
|---|---|---|---|
acks |
all (-1) |
1, all |
Determines how many partition replicas must record the batch before acknowledging the client. all guarantees zero loss across in-sync replicas (ISR). |
enable.idempotence |
true |
true |
Assigns a Producer ID (PID) and monotonically increasing sequence numbers per batch to deduplicate writes at the broker level during network retries. |
retries |
2147483647 (Integer.MAX_VALUE) |
10 to Integer.MAX_VALUE |
Governs how many times the client reattempts transient errors (e.g. NOT_ENOUGH_REPLICAS, LEADER_NOT_AVAILABLE). |
retry.backoff.ms |
100 |
50 to 1000 |
Initial backoff time before retrying a failed batch request, typically paired with exponential backoff configurations. |
batch.size |
16384 (16 KB) |
32768 to 131072 |
The memory ceiling for a single partition-level batch. Larger batches boost compression ratios and network efficiency at the expense of memory footprint. |
linger.ms |
0 |
5 to 100 |
Artificial delay introduced to allow user threads to append more records to a batch before dispatching it to the network layer. |
buffer.memory |
33554432 (32 MB) |
67108864 to 536870912 |
Total memory reserved by the RecordAccumulator across all partition queues. Must scale with partition counts and throughput targets. |
max.block.ms |
60000 (60 sec) |
5000 to 30000 |
How long send() and metadata fetching will block before throwing an exception when buffer pools are exhausted. |
compression.type |
none |
zstd, lz4, snappy |
Compresses entire record batches on the client prior to transport. Reduces network socket saturation and broker disk I/O significantly. |
max.in.flight.requests.per.connection |
5 |
1 to 5 |
Concurrent unacknowledged requests allowed per socket. With idempotence active, values up to 5 maintain strict in-order guarantees. |
To safely manage these properties, engineers should adhere to an architectural baseline checklist prior to deploying to staging or production:
- Verify that
enable.idempotenceremains set totrue. Disabling this opens the system to duplicate records on transient TCP dropouts. - Ensure broker-side
min.insync.replicasis configured to at least2when clientacks=allis set. Anacks=allconfiguration with a brokermin.insync.replicas=1allows silent data loss if the single leader broker fails immediately after acknowledging a record. - Validate that
delivery.timeout.msis equal to or greater thanlinger.ms + request.timeout.ms + retry.backoff.ms. The client will abort batches whose age exceedsdelivery.timeout.msregardless of remaining retries. - Ensure that heap allocations reserve at least twice the value of
buffer.memoryto account for off-heap buffers, serialization overhead, and network socket allocations.
Building a Resilient Kafka Producer Example in Java and Python
A production-ready kafka producer example must implement robust, non-blocking error management. Simply invoking get() on the Future returned by send() degrades the architecture into a synchronous bottleneck, negating the throughput capabilities of the underlying network client. Instead, applications must use asynchronous callbacks combined with structured handling of retriable versus fatal exceptions.
Production-Grade Java Producer Implementation
The following Java pattern demonstrates thread-safe record streaming, non-blocking callback handling, explicit error isolation, and graceful lifecycle termination using modern client standards:
package com.engineers.kafka;

import org.apache.kafka.clients.producer.*;
import org.apache.kafka.common.serialization.StringSerializer;
import org.apache.kafka.common.errors.RetriableException;
import org.slf4j.Logger;
import org.slf4j.LoggerFactory;

import java.time.Duration;
import java.util.Properties;

public class ResilientEventProducer implements AutoCloseable {
 private static final Logger log = LoggerFactory.getLogger(ResilientEventProducer.class);
 private final Producer<String, String> producer;

 public ResilientEventProducer(String bootstrapServers) {
 Properties props = new Properties();
 props.put(ProducerConfig.BOOTSTRAP_SERVERS_CONFIG, bootstrapServers);
 props.put(ProducerConfig.KEY_SERIALIZER_CLASS_CONFIG, StringSerializer.class.getName());
 props.put(ProducerConfig.VALUE_SERIALIZER_CLASS_CONFIG, StringSerializer.class.getName());

 // Resiliency and Idempotence Baselines
 props.put(ProducerConfig.ENABLE_IDEMPOTENCE_CONFIG, "true");
 props.put(ProducerConfig.ACKS_CONFIG, "all");
 props.put(ProducerConfig.RETRIES_CONFIG, Integer.MAX_VALUE);
 props.put(ProducerConfig.MAX_IN_FLIGHT_REQUESTS_PER_CONNECTION, 5);

 // Throughput and Batching Dynamics
 props.put(ProducerConfig.BATCH_SIZE_CONFIG, 64 * 1024); // 64 KB
 props.put(ProducerConfig.LINGER_MS_CONFIG, 20); // 20 ms batch accumulation
 props.put(ProducerConfig.COMPRESSION_TYPE_CONFIG, "zstd");
 props.put(ProducerConfig.BUFFER_MEMORY_CONFIG, 64 * 1024 * 1024L); // 64 MB pool
 props.put(ProducerConfig.MAX_BLOCK_MS_CONFIG, 15000); // 15s max block

 this.producer = new KafkaProducer<>(props);
 }

 public void publish(String topic, String key, String payload) {
 ProducerRecord<String, String> record = new ProducerRecord<>(topic, key, payload);

 this.producer.send(record, new Callback() {
 @Override
 public void onCompletion(RecordMetadata metadata, Exception exception) {
 if (exception == null) {
 log.debug("Delivered to partition {} at offset {}",
 metadata.partition(), metadata.offset());
 } else {
 handleFailure(record, exception);
 }
 }
 });
 }

 private void handleFailure(ProducerRecord<String, String> record, Exception exception) {
 if (exception instanceof RetriableException) {
 // The client retries automatically; reaching here means delivery.timeout.ms expired
 log.error("Exhausted retries for key {}. Routing to internal DLQ storage.",
 record.key(), exception);
 } else {
 // Fatal error: serialization failure, auth failure, topic authorization
 log.error("Fatal unrecoverable error sending key {}. Halting pipeline.",
 record.key(), exception);
 }
 }

 @Override
 public void close() {
 log.info("Initiating graceful producer flush and shutdown..");
 // Flush remaining batches in memory pool within a bounded timeout
 this.producer.close(Duration.ofSeconds(10));
 }
}
Production-Grade Python Implementation (kafka-python / confluent-kafka)
For Python ecosystems, high-throughput applications leverage bindings built over librdkafka (such as confluent-kafka) to achieve C-level socket performance while maintaining asynchronous delivery callbacks:
import logging
import sys
from confluent_kafka import Producer, KafkaError

logging.basicConfig(level=logging.INFO)
logger = logging.getLogger(__name__)

class ResilientPythonProducer:
 def __init__(self, bootstrap_servers: str):
 conf = {
 'bootstrap.servers': bootstrap_servers,
 'acks': 'all',
 'enable.idempotence': True,
 'compression.type': 'zstd',
 'linger.ms': 20,
 'batch.num.messages': 1000,
 'queue.buffering.max.kbytes': 65536, # 64 MB
 'queue.buffering.max.messages': 100000,
 'retries': 10000000,
 'retry.backoff.ms': 100,
 }
 self.producer = Producer(conf)

 def _delivery_callback(self, err, msg):
 if err is not None:
 if err.retriable():
 logger.error(f"Retriable error dispatching message: {err.str()}")
 else:
 logger.critical(f"Fatal error dispatching message: {err.str()}")
 else:
 logger.debug(f"Delivered to {msg.topic()} [{msg.partition()}] at {msg.offset()}")

 def publish(self, topic: str, key: str, value: str):
 try:
 # Asynchronously pushes record to librdkafka accumulator queue
 self.producer.produce(
 topic=topic,
 key=key.encode('utf-8'),
 value=value.encode('utf-8'),
 on_delivery=self._delivery_callback
 )
 # Non-blocking poll to serve delivery callbacks on the background thread
 self.producer.poll(0)
 except BufferError:
 logger.warning("Local buffer full, triggering short flush backpressure")
 self.producer.poll(100) # Wait 100ms for buffer drainage
 self.producer.produce(topic=topic, key=key, value=value, on_delivery=self._delivery_callback)

 def teardown(self):
 logger.info("Flushing queued records..")
 self.producer.flush(timeout=10)
Clean Code Rule: Always implement explicit client closure using bounded timeouts (such as
close(Duration.ofSeconds(10))in Java orflush(timeout=10)in Python). Terminating an application without an explicit flush aborts the batches currently held inside theRecordAccumulator, corrupting inflight operations and dropping records.
Throughput vs Latency: Workload Configuration Presets
A common misstep in distributed architectures is applying uniform client configurations to fundamentally divergent workloads. An IoT telemetry collector transmitting millions of non-critical metric pulses requires an entirely different tuning model than an algorithmic payment execution engine handling sub-millisecond financial transfers.
Adjusting the trade-offs between throughput and latency centers on batch formation. Setting linger.ms=0 commands the background thread to dispatch packets the instant a socket becomes writeable, lowering latency at the cost of tiny, fragmented TCP segments. Elevating linger.ms to 20ms or 50ms enables continuous streams of incoming records to coalesce into consolidated memory blocks, unlocking high network efficiency and high data compression ratios.
| Metric & Attribute | Preset A: High-Throughput Ingestion | Preset B: Ultra-Low Latency | Preset C: Balanced Durability Baseline |
|---|---|---|---|
| Target Scenarios | Telemetry, Clickstreams, Audit Logs | Financial trading, Real-time alerting | Core transactional systems, Microservices |
acks |
all |
1 |
all |
enable.idempotence |
true |
false |
true |
batch.size |
131,072 bytes (128 KB) | 4,096 bytes (4 KB) | 32,768 bytes (32 KB) |
linger.ms |
50 |
0 |
10 |
compression.type |
zstd (Level 3) |
none |
lz4 |
max.in.flight.requests |
5 |
1 |
5 |
| Throughput Ceiling | Over 150,000 records/sec/instance | 15,000 to 25,000 records/sec/instance | 60,000 to 80,000 records/sec/instance |
| End-to-End Latency | 40 ms to 120 ms (p99) | 0.8 ms to 2.5 ms (p99) | 8 ms to 18 ms (p99) |
| CPU Overhead Source | Batch compression / decompression | Context switching & system calls | Balanced memory management |
Compression selection plays an instrumental role in resolving these trade-offs. lz4 delivers blazing compression and decompression speeds with modest CPU overhead, making it ideal for balanced architectures. zstd incurs higher client CPU utilization during encoding but achieves phenomenal compression ratios, significantly reducing network egress costs on cloud providers and slashing partition disk utilization across broker nodes.
Troubleshooting Buffer Exhaustion and Network Failures
When high write volume intersects with network jitter or broker metadata recalculations, producers experience abrupt backpressure. If misdiagnosed, these friction points manifest as cascading application timeouts, out-of-memory crashes, or silent data truncation.
Understanding the root causes of client-side failures prevents production incidents from escalating across distributed microservices:
- BufferPool Starvation (BufferExhaustedException): When broker writes stall or TCP windows shrink, the background
Sendercannot empty ready batches quickly enough. The calling thread attempts to append new data to theRecordAccumulator, finds no free buffers, and halts. It blocks formax.block.msbefore failing with a buffer exhaustion error. Remedy: Scalebuffer.memoryfrom 32 MB to 128 MB or 256 MB, increase downstream partition counts to distribute broker load, or apply rate limiting at the edge. - Metadata Staleness (TimeoutException: Failed to update metadata): If the producer cannot contact any broker specified in
bootstrap.serversor if the cluster undergoes an extended controller election, partition topology caches become invalid. Subsequentsend()invocations block waiting for metadata updates. Remedy: Ensure thatbootstrap.serverscontains at least three distinct brokers representing distinct availability zones, and confirm security certificates and firewalls permit ongoing discovery requests. - Retriable Exception Handling (NOT_ENOUGH_REPLICAS): This error surfaces when a partition leader determines that the count of active in-sync replicas (ISR) is below the topic configuration
min.insync.replicas. Because this error is classified as aRetriableException, the producer handles retries transparently untildelivery.timeout.msis reached. Remedy: Audit broker hardware, disk write speeds, and replication health rather than modifying client configurations. Never reducemin.insync.replicasto 1 in durable production environments. - MessageSizeTooLargeException: Thrown synchronously if the uncompressed record exceeds the client limit
max.request.size(default 1 MB) or asynchronously if the broker rejects the batch due to its ownmessage.max.bytesceiling. Remedy: Align client and broker payload limits, enable compression (such aszstd), or adopt the claim-check pattern by storing large payloads in an object store like S3 and passing object URIs through Kafka.
Telemetry Baseline: Never monitor producers based purely on application logs. Continuously export JMX client metrics to Prometheus or OpenTelemetry, establishing operational alarms on
record-queue-time-max(time spent waiting inside the accumulator),buffer-exhausted-rate, andrecord-retry-rate.
Frequently Asked Questions
What does a Kafka producer do in an event streaming pipeline?
An Apache Kafka producer is an application client responsible for publishing data records to specific topics within a Kafka cluster. It handles message serialization, partition assignment, batch buffering, compression, and network transport to broker leader partitions asynchronously while guaranteeing configurable durability.
How do core Kafka producer properties prevent message duplication?
Setting enable.idempotence to true instructs the broker to track unique producer IDs and sequence numbers for each message batch. This prevents duplicate writes caused by network retries without requiring distributed two-phase transactions, ensuring exactly-once delivery per partition automatically.
What is the primary architectural difference between a Kafka producer and consumer?
A Kafka producer pushes serialized records directly to partition leader brokers using partitioners and memory accumulators. Conversely, a Kafka consumer pulls messages via polling loops, coordinates offset commits within consumer groups, and manages partition rebalances across dynamic subscriber instances.
What is a standard Kafka producer example configuration for high throughput?
High-throughput producer configurations increase batch.size to 65536 bytes, set linger.ms between 10 and 50 milliseconds, enable snappy or zstd compression, and set max.in.flight.requests.per.connection to 5, maximizing TCP packet utilization and broker throughput efficiency.
Optimizing the Kafka producer demands balancing client-side memory safety, transport throughput, and distributed persistence guarantees. Modern Kafka defaults emphasize reliability, establishing idempotent delivery and complete in-sync replica acknowledgments out of the box. However, achieving production efficiency at enterprise scale requires tuning the interaction between application threads and the background network client.
By matching linger.ms, batch.size, and compression strategies to specific business SLAs, and by actively monitoring accumulator queue times and buffer pool saturation, engineers can establish resilient, deterministic event pipelines capable of processing sustained message volumes with zero data loss.