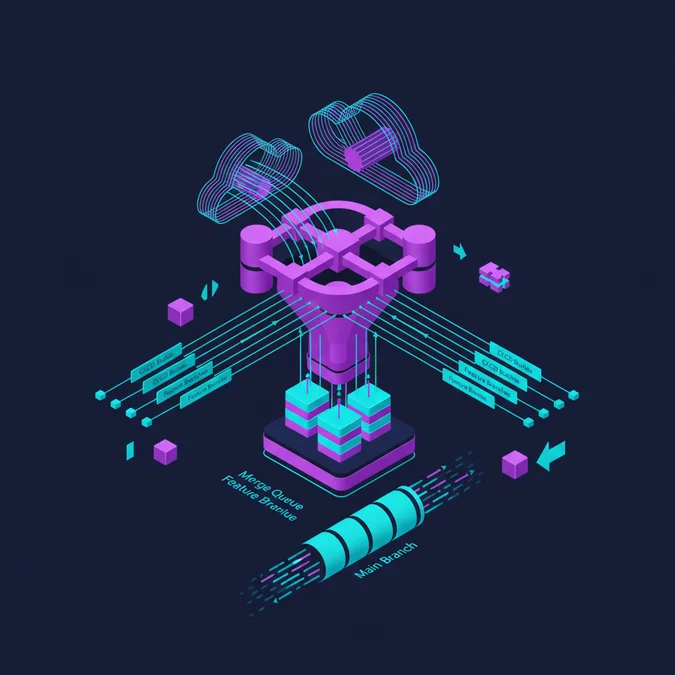

A GitHub merge queue is an automated coordination engine that tests pull requests serially or in speculative batches against the latest target branch state before merging. It eliminates the semantic merge conflicts, broken default branches, and integration race conditions that occur when multiple engineers merge concurrently into busy production trunks.
Data from the DORA State of DevOps research reveals that elite engineering teams deploy multiple times per day with lead times under an hour, yet branch contention regularly causes trunk instability at scale. When pull requests are validated against stale base branches, integration test suites pass in isolation only to fail immediately upon hitting the main branch. This phenomenon halts delivery pipelines across entire engineering departments.
Managing this bottleneck requires moving beyond branch protection rules that demand manual rebases. By implementing an automated queuing architecture, teams maintain continuous delivery integrity, accelerate pipeline velocity, and remove the human coordination overhead required to keep complex application codebases stable.
The Anatomy of Branch Contention and Semantic Conflicts
Standard Git branch protections often enforce a requirement where branches must be up to date before merging. In a repository with twenty engineers opening pull requests simultaneously, this rule creates a cascading queue lock. When engineer A merges a pull request, the base branch shifts forward. As a result, branches belonging to engineers B, C, and D are immediately marked out of date by GitHub. Each engineer must rebase, run their entire CI workflow again, and race to merge before another teammate invalidates their build.
Even more dangerous are semantic conflicts, which Git cannot detect automatically. A text conflict occurs when two branches modify the exact same line of code. A semantic conflict occurs when two branches modify distinct files that depend on one another logically. For example:
- Pull Request A: Deprecates and removes an internal authentication parameter across legacy route definitions.
- Pull Request B: Introduces a new administrative reporting endpoint relying on that exact legacy parameter.
Both pull requests pass automated CI testing against the main branch because neither branch contains the other’s changes. If merged without serialization, the main branch breaks immediately upon arrival. Solving this problem requires validating the precise merged state before changing the pointer of the base branch. This process forms the core mandate of modern deployment engineering, ensuring that systematic processes for producing software remain reliable under heavy organizational concurrency.
Architecture Deep Dive: GitHub Merge Queue Mechanics
GitHub merge queue replaces manual branch updating with an automated queue controller. Instead of merging directly, authorized developers submit their approved pull requests to a staging buffer. The merge queue controller then provisions temporary merge group branches to execute CI checks against real-world combined states.
Temporary Merge Groups and Speculative Execution
The queue creates ephemeral references named gh-readonly-queue/{base_branch}/pr-{pr_number}-{commit_sha}. The platform supports two core validation behaviors:
- Strict Serialization: Each pull request is merged virtually into the tip of the branch resulting from the preceding queue item. CI runs on this isolated combination. Once green, GitHub pushes the commit to the main branch.
- Speculative Parallelism (Batching): To prevent long CI pipelines from stalling delivery, GitHub batches multiple pull requests together into a speculative target. If pull requests 101, 102, and 103 are queued, the engine builds a combined commit containing all three changes and runs the test suite once.
If the batched run succeeds, all three pull requests merge simultaneously. If the speculative run fails, the merge queue engine triggers a bisection algorithm. It splits the batch into smaller clusters or isolates pull requests individually to identify which specific commit broke the test suite, evicting the faulty branch and allowing healthy contributions to merge without human intervention.
Configuring GitHub Merge Queue with GitHub Actions
Adopting GitHub merge queue requires updating existing continuous integration workflows to listen for the merge queue trigger event. Pipelines configured exclusively for pull_request or push events will fail to run when GitHub creates temporary merge group refs, causing the queue to hang indefinitely waiting for required status checks.
The GitHub Actions workflow configuration below demonstrates how to configure test matrices, static analysis, and framework test suites for both standard review cycles and merge queue validation:
name: Continuous Integration Matrix

on:
 pull_request:
 branches: [ main ]
 merge_group:
 types: [ checks_requested ]

jobs:
 run-verification:
 name: Test and Analyze
 runs-on: ubuntu-22.04
 timeout-minutes: 20

 steps:
 - name: Checkout Code
 uses: actions/checkout@v4
 with:
 # Fetch full history to ensure base branch diffs resolve cleanly
 fetch-depth: 0

 - name: Setup PHP Environment
 uses: shivammathur/setup-php@v2
 with:
 php-version: '8.3'
 extensions: mbstring, pdo_sqlite, redis
 coverage: none

 - name: Install Dependencies
 run: composer install --no-progress --prefer-dist --optimize-autoloader

 - name: Run Static Analysis
 run:/vendor/bin/phpstan analyse --level=8

 - name: Execute Automated Test Suite
 run: php artisan test --parallel
Within the repository branch protection settings, the status check labeled Test and Analyze must be set as a required check. When a pull request enters the queue, GitHub executes this workflow against the dynamic merge_group context, merging the pull request automatically as soon as the job reports success.
CI Pipeline Optimization for High-Volume Monorepos and Frameworks
When using speculative batching, lengthy test execution creates compounding latency. If a test suite requires 45 minutes to execute, a speculative failure forces the engine to bisect the batch, adding an additional 45 minutes to re-test the split branches. Keeping queue throughput acceptable demands aggressive CI pipeline optimization.
Selective Path Filtering and Caching
Repositories housing multiple microservices or layered application architectures should avoid running monolithic test suites on non-impacting documentation or administrative changes. Utilizing intelligent path evaluation prevents running entire end-to-end integration matrices when an engineer updates a localized service or database migration.
Furthermore, testing networked dependencies requires deterministic caching and mock handling. When running complex integration suites that interact with downstream systems, implementing the Laravel HTTP client for resilient external APIs ensures that external connection timeouts or third-party service hiccups do not result in false-positive queue evictions. Combining deterministic mocks with parallelized runner nodes running on high-core compute instances keeps median queue wait times under fifteen minutes even during peak development windows.
Scaling Challenges: Handling Flaky Tests and Queue Eviction Cycles
The single greatest operational hazard when operating a merge queue is test flakiness. In standard pull request workflows, a developer who encounters an intermittent network timeout or race condition simply clicks the rerun button. In an automated merge queue environment, a single flaky test triggers an automated eviction cascade.
When a speculative batch of five pull requests encounters a single intermittent failure in an unrelated end-to-end test:
- The queue marks the entire speculative batch as failed.
- The engine drops the branch deemed responsible, or bisects the batch into two groups of three and two pull requests.
- CI runners trigger across both subgroups, consuming double the compute budget.
- If the flaky test strikes again during the bisection phase, multiple valid branches are evicted, forcing engineers to manually intervene and re-queue their work.
Mitigating this problem requires rigorous test quarantine practices. Systems teams must track flakiness metrics through test observability platforms, automatically isolating non-deterministic tests out of the blocking queue path into non-blocking monitoring pipelines until remediated. Team discipline surrounding test stability is mandatory before tightening merge queue restrictions.
Build vs Buy: Native GitHub Merge Queue vs Dedicated SaaS Engines
Organizations scaling their delivery pipelines must decide between adopting GitHub’s native merge queue or implementing dedicated third-party tools like Mergify, Trunk Merge, or custom in-house automation engines. While native tooling simplifies administrative overhead, dedicated solutions provide advanced scheduling logic.
| Evaluation Criterion | GitHub Merge Queue (Native) | Third-Party Merge Engines | In-House Custom Controller |
|---|---|---|---|
| Setup Complexity | Low (Integrated into GitHub settings) | Medium (Requires GitHub App permissions) | Extreme (Requires webhooks, worker queues, state engine) |
| Speculative Batching | Native support included | Highly customizable batching rules | Complex to engineer reliably |
| Priority Queuing | Basic priority ordering | Complex priority queues, hotfix lanes | Custom programmable |
| Maintenance Overhead | Zero platform maintenance | Third-party vendor management | High internal maintenance cost |
| Workflow Compatibility | Tightest integration with GitHub Actions | Supports cross-provider CI (CircleCI, Buildkite) | Platform agnostic |
For organizations already operating entirely within the GitHub ecosystem, the native merge queue eliminates vendor procurement cycles and maintains direct compatibility with native repository controls. Teams needing custom hotfix lane interruptions, dynamic rule-based priority routing, or cross-platform CI orchestration often find third-party vendors better suited to their operational models.
Comprehensive Cost and Financial Analysis
Adopting an automated merge queue shifts developer rebase time onto cloud compute infrastructure. Instead of engineers running local builds and waiting for rebase pipelines on their workstations, cloud runners execute continuous speculative batches. Calculating total cost requires evaluating GitHub plan access tiers, cloud runner minute consumption, and third-party software licenses.
License and Infrastructure Expenditure Breakdown
GitHub merge queue is natively available on GitHub Enterprise Cloud plans, which cost $21.00 per user per month when billed annually, or on standard public open-source repositories. Organizations running GitHub Team plans ($4.00 per user per month) must calculate the economic trade-off between upgrading to Enterprise or purchasing an external third-party merge queue add-on.
| Deployment Model | Monthly Software Cost | Estimated CI Compute Cost | Total Monthly Cost (50 Devs) |
|---|---|---|---|
| GitHub Enterprise Native | $21.00 per seat ($1,050.00/mo) | $600.00 to $1,400.00 (Actions minutes) | $1,650.00 to $2,450.00 |
| GitHub Team + Dedicated SaaS | $4.00 per seat + $350.00 base SaaS | $500.00 to $1,200.00 (CI minutes) | $1,050.00 to $1,750.00 |
| Custom-Built Queue Engine | $4.00 per seat + AWS compute ($120.00) | $500.00 to $1,100.00 | $820.00 + Internal Eng Retainer |
Organizations must factor in internal engineering maintenance overhead. Building an in-house queue controller typically demands two senior infrastructure engineers working for three months, translating to roughly $90,000.00 in initial capital expenditure, followed by $1,500.00 to $3,000.00 monthly in engineering time for maintenance, bug fixes, and edge case remediation. For high-performance backend teams leveraging modern runtimes such as Laravel Octane production deployments, directing capital toward optimized serverless or containerized CI runners yield significantly higher return on investment than building proprietary queue controllers.
Enterprise Rollout and Migration Strategy
Migrating a large engineering organization to a merge queue requires a disciplined rollout plan to avoid blocking ongoing product releases. Abruptly activating queue requirements across an unprepared engineering organization often results in deployment deadlocks.
Phased Migration Roadmap
- Audit CI Execution Times and Flakiness: Establish baseline test run durations and eliminate tests with variance higher than 1%. Ensure typical pipeline runs complete in under 15 minutes.
- Update Workflow Definitions: Ensure all relevant GitHub Actions workflows include the
merge_groupevent trigger alongside standard pull request checks. - Pilot with a Core Team: Enable the merge queue on a critical service with high throughput, setting the maximum batch size to 1 (strict serialization). This allows engineers to understand queue state transitions without speculative failure confusion.
- Tune Speculative Batch Sizes: Once the team is comfortable, increase batch sizes to groups of three to five pull requests. Monitor the bisection frequency and queue depth during peak work hours.
- Codify Architectural Standards: Maintain precise team alignment across pull request descriptions and branch labeling conventions. Following consistent software engineering acronyms and team title standards helps automate review approvals and triage operational merge queue alerts effectively.
Laravel Architecture and Base Directory Exploration
Engineering teams running sophisticated backend applications require robust deployment pipelines that pair rock-solid framework architecture with dependable trunk delivery. Managing complex migrations, queues, and containerized workloads begins with mastering underlying structural fundamentals.
Explore our complete Laravel, Basics directory for more guides.
Factors That Affect Development Cost
- GitHub account licensing tier (Enterprise Cloud vs Team)
- CI runner compute consumption from speculative bisecting
- Third-party merge engine SaaS subscription fees
- Internal engineering hours required for workflow modernization
Total operational costs typically range from $1,050 to $2,450 per month for a 50-engineer team depending on runner consumption and GitHub licensing tiers.
Implementing a GitHub merge queue resolves the architectural gridlock of branch contention and prevents semantic integration errors from polluting the default branch. By shifting the burden of branch rebasing and verification from human engineers to automated speculative batch runners, organizations maintain a pristine trunk while sustaining high deployment frequency.
Success requires treating the CI pipeline as a mission-critical production system. Teams must aggressively eliminate flaky tests, parallelize test suites, optimize compute allocations, and select the right balance between native GitHub Enterprise tools and specialized third-party engines. When executed thoughtfully, a merge queue transforms trunk-based development from an aspirational philosophy into an automated, predictable delivery reality.