
A customer initiates a high-value wire transfer, triggering a fraud verification challenge. The one-time password (OTP) must reach their device within 8 seconds. Simultaneously, the platform launches a scheduled flash sale campaign to 20 million users. Without decoupled queues and isolated compute pools, the surge of bulk marketing payloads saturates gateway threads, introduces bufferbloat, and starves the transactional channel. The OTP arrives four minutes late, the checkout session expires, and the financial platform suffers measurable churn.
Engineering a notification backbone capable of serving hundreds of millions of daily active users requires balancing conflicting delivery vectors: ultra-low latency transactional events versus high-volume, cost-optimized digest broadcasts. The system must accommodate external downstream failures, handle asynchronous Apple Push Notification service (APNs) and Firebase Cloud Messaging (FCM) token invalidation lifecycles, and enforce deterministic idempotency across non-idempotent vendor APIs like Twilio, SendGrid, and AWS SNS.
This technical blueprint covers the end-to-end architecture of a modern notification platform. We examine mathematical capacity planning, high-level event streaming topologies, low-level object-oriented design patterns, database partitioning strategies, and resilient vendor fallback mechanisms configured to withstand upstream traffic spikes and downstream provider outages.
System Requirements, Throughput Modeling, and Hard Engineering Constraints
When you design a notification system for enterprise workloads, system boundaries must explicitly isolate transactional and promotional throughput. A single architectural bottleneck cannot be allowed to degrade critical system alerts or security challenges.
Functional and Non-Functional Engineering Requirements
- Multi-Channel Support: Native routing across Mobile Push (APNs, FCM), SMS (Twilio, Sinch), Email (SendGrid, AWS SES), and In-App WebSockets.
- Strict Delivery Latency (p99): Sub-3 seconds for high-priority transactional alerts (OTP, account access); sub-5 minutes for marketing broadcasts and engagement digests.
- Idempotency and Exactly-Once Guarantees: Guarantee at-least-once downstream transport with strict end-user deduplication to prevent double-charging or duplicate alerts.
- User Preference and Quiet Hours: Dynamically honor channel opt-outs, granular category controls, and localized quiet-hour delays based on recipient time zones.
- Vendor Fault Tolerance: Instantaneous circuit-breaker failover across upstream telecommunication aggregators without dropping messages in flight.
Throughput Modeling and Capacity Sizing (500M Messages/Day)
Designing for scale requires concrete baseline calculations. Consider a global application supporting 100 million Daily Active Users (DAU) generating an average of 5 notifications per user per day.
- Total Daily Volume: 500,000,000 notifications / 24 hours = 5.787 × 10^7 messages/hour.
- Average Ingestion RPS: 500,000,000 / 86,400 seconds = ~5,787 requests/sec.
- Peak Ingestion Factor (4x Surge): 5,787 × 4 = 23,148 RPS.
- Payload Payload Footprint: Average notification payload (metadata, localized copy, routing headers) is ~2 KB.
- Ingestion Ingress Bandwidth (Peak): 23,148 RPS × 2 KB = 46.3 MB/sec (370.4 Mbps).
- Daily Persistence (Raw Notification Logs): 500M × 2 KB = 1,000 GB/day (1 TB raw logs/day). With indexes and 3x replica factors, storage scales at ~4 TB/day.
| Metric Parameter | Transactional Priority | Promotional / Marketing | Analytical / System Logs |
|---|---|---|---|
| Ingestion Throughput (Peak) | 5,000 RPS | 20,000 RPS | 25,000 RPS |
| Target p99 Latency SLA | < 3,000 ms | < 300,000 ms (5 min) | < 10,000 ms |
| Delivery Guarantee | At-least-once + Deduplicated | At-least-once | Best-effort |
| Storage Retention Period | 90 Days (Hot Partition) | 7 Days (TTL Eviction) | 365 Days (Cold Parquet) |
| Failure Retry Policy | Exponential backoff (3 attempts) | Linear backoff (2 attempts) | None / Silent drop |
Production SLA Checklist
- Define dedicated thread pools and CPU budgets between priority and standard ingestion gateways.
- Provision minimum 3x redundancy for message brokers across multi-Availability Zone (AZ) deployments.
- Set up distributed tracing span contexts (W3C TraceContext) across API gateways, brokers, and worker runtimes.
- Establish backpressure shedding controls at edge ingress points to throttle non-critical campaigns when transactional queues experience backlogs.
End-to-End Notification Service System Design and Component Pipeline
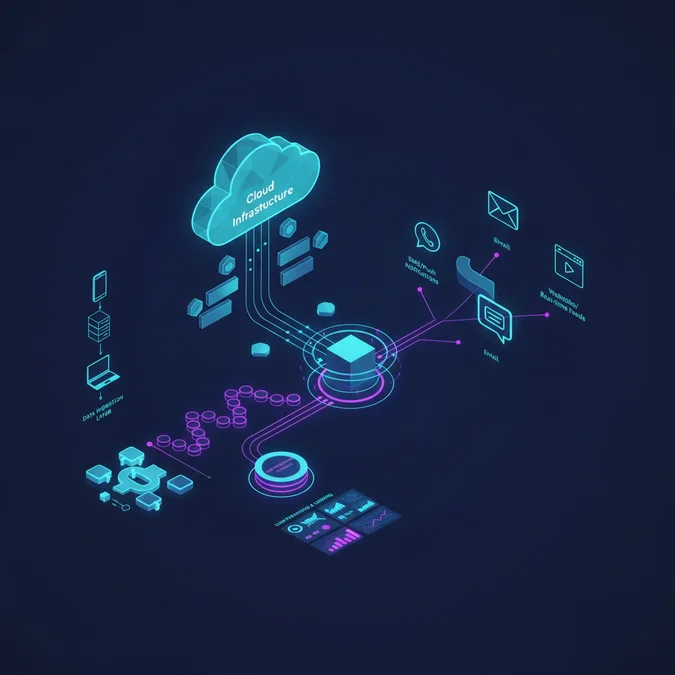
A high-performance notification service system design relies entirely on asynchronous, decoupled event-driven primitives. The core system architecture separates the synchronous edge ingress layer from downstream message processing, routing, and delivery workers.
+-------------------------------------------------------------------------------------------------+ | INGESTION & ROUTING TOPOLOGY | +-------------------------------------------------------------------------------------------------+ [ Upstream Services: Auth, Billing, Social ] | (REST / gRPC Ingestion) | +-------------------------------v--------------------------------+ | Edge Ingress API Gateway (Envoy / Kong) | | [Rate Limiter, Auth Tokens, Schema Validation] | +-------------------------------+--------------------------------+ | v +--------------------------------------------------+ | Notification Router Core | | [Idempotency Check, User Preferences, Digest] | +------------------------+-------------------------+ | +-------------------+--------------------+ | | | v v v +--------------------+ +--------------------+ +--------------------+ | Kafka / RabbitMQ: | | Kafka / RabbitMQ: | | Kafka / RabbitMQ: | | Push Topic (P0-P2) | | SMS Topic (P0-P1) | | Email Topic (P0-P2)| +---------+----------+ +---------+----------+ +---------+----------+ | | | v v v +---------+----------+ +---------+----------+ +---------+----------+ | Push Worker Engine | | SMS Worker Engine | | Email Worker Engine| +---------+----------+ +---------+----------+ +---------+----------+ | | | +--------+--------+ +--------+--------+ +--------+--------+ | | | | | | v v v v v v +----------+ +----------++----------+ +----------++----------+ +----------+ | APNs | | FCM || Twilio | | Sinch || SendGrid | | AWS SES | +----------+ +----------++----------+ +----------++----------+ +----------+Architecture Rule: Never route heterogeneous notification channels through a shared physical message broker topic. Channel contention guarantees that long-polling SMS networks or email rate limits will exhaust connection pools, inadvertently backing up push notifications.
Lifecycle of a Notification Request
- Ingestion and Validation: The upstream microservice issues an authenticated gRPC call to the Ingress API Gateway containing the recipient identifier, event template ID, context parameters, and priority classification.
- Idempotency Verification: The gateway intercepts the payload, extracts or hashes an idempotency key (such as
event_type:recipient_id:order_id), and executes a Redis distributed atomic lock. If the key exists, the request is safely rejected or returned as processed. - Recipient Context Enrichment: The Notification Router queries a low-latency cache (Redis Cluster) to fetch the user preference matrix, channel blacklists, registered device tokens, and local timezone constraints.
- Channel Demuxing and Fan-Out: If the message represents a multi-channel broadcast, the router disaggregates the event into discrete channel tasks and writes them into channel-specific, priority-segmented Apache Kafka topics (e.g.
push-high-priority,email-low-priority). - Worker Pool Execution: Dedicated, autoscaling worker groups consume from their designated partitions. The workers execute template compilation, invoke localized rate limits, and dispatch the payload to the external provider using isolated HTTP/2 or gRPC persistent client pools.
- Receipt and Feedback Invalidation: Outbound statuses, vendor message identifiers, and downstream bounce or token-invalidation payloads (e.g. APNs
BadDeviceToken) return to a feedback loop topic to reconcile device token registries and analytical warehouses.
Notification Service LLD: Class Abstractions and Behavioral Design Patterns
A resilient notification service LLD demands modular abstractions that isolate the dispatching logic from concrete vendor APIs. By combining the Strategy Pattern with the Factory Method and Observer patterns, new communication channels and downstream vendors can be integrated without modifying the core delivery engine.
Component Object-Oriented Architecture
| Design Pattern | Architectural Responsibility | Implementation Scope |
|---|---|---|
| Factory Pattern | Instantiates provider-specific adapters based on channel configurations and recipient routing metadata. | NotificationProviderFactory |
| Strategy Pattern | Decouples the abstract transmission interface from provider-specific protocols (APNs HTTP/2, Twilio REST, SendGrid v3). | PushDeliveryStrategy, SmsDeliveryStrategy |
| Observer Pattern | Notifies analytical dispatchers, billing trackers, and failure monitor handlers upon delivery completion. | DeliveryLifecycleManager |
TypeScript Implementation: Strategy and Factory Interfaces
import { Result } from "./types"; // Domain result wrapper

export interface NotificationPayload {
 recipientId: string;
 destination: string;
 templateId: string;
 params: Record<string, string>
 priority: "HIGH" | "NORMAL" | "LOW";
 idempotencyKey: string;
}

export interface DeliveryResponse {
 success: boolean;
 providerMessageId? string;
 errorCode? string;
 retryable: boolean;
}

// Strategy Interface: Provider Abstraction
export interface NotificationProvider {
 readonly providerName: string;
 send(payload: NotificationPayload): Promise<DeliveryResponse>
}

// Concrete Strategy: APNs HTTP/2 Integration
export class ApnsPushProvider implements NotificationProvider {
 readonly providerName = "APNS_HTTP2";

 async send(payload: NotificationPayload): Promise<DeliveryResponse> {
 try {
 // Production HTTP/2 client dispatch logic omitted for brevity
 return {
 success: true,
 providerMessageId: `apns-${crypto.randomUUID()}`,
 retryable: false,
 };
 } catch (err: any) {
 const isNetworkTimeout = err.code === "ETIMEDOUT";
 return {
 success: false,
 errorCode: err.message,
 retryable: isNetworkTimeout,
 };
 }
 }
}

// Concrete Strategy: Twilio SMS Integration
export class TwilioSmsProvider implements NotificationProvider {
 readonly providerName = "TWILIO_SMS";

 async send(payload: NotificationPayload): Promise<DeliveryResponse> {
 try {
 // Twilio SDK / API execution
 return {
 success: true,
 providerMessageId: `tw-${crypto.randomUUID()}`,
 retryable: false,
 };
 } catch (err: any) {
 return {
 success: false,
 errorCode: err.code || "PROVIDER_FAILURE",
 retryable: err.status >= 500,
 };
 }
 }
}

// Channel Factory
export class NotificationProviderFactory {
 private static providerRegistry: Map<string, NotificationProvider> = new Map();

 public static registerProvider(channel: string, provider: NotificationProvider): void {
 this.providerRegistry.set(channel, provider);
 }

 public static getProvider(channel: string): NotificationProvider {
 const provider = this.providerRegistry.get(channel);
 if (!provider) {
 throw new Error(`Provider for channel "${channel}" is not registered.`);
 }
 return provider;
 }
}

// Worker Service Context invoking Strategy
export class NotificationDispatcher {
 async dispatchMessage(channel: string, payload: NotificationPayload): Promise<void> {
 const provider = NotificationProviderFactory.getProvider(channel);
 const result = await provider.send(payload);

 if (!result.success) {
 if (result.retryable) {
 // Route to dead letter queue or delayed backoff broker
 await this.handleRetry(channel, payload, result.errorCode);
 } else {
 // Emit metrics, permanent failure
 this.handleTerminalFailure(channel, payload, result.errorCode);
 }
 }
 }

 private async handleRetry(channel: string, payload: NotificationPayload, err? string): Promise<void> {
 // Backoff implementation
 }

 private handleTerminalFailure(channel: string, payload: NotificationPayload, err? string): void {
 // Alerting and dead-letter log
 }
}
This low-level design ensures that upstream workers operate exclusively against the abstract NotificationProvider interface. When onboarding an alternate provider (such as MessageBird or AWS Pinpoint), developers only need to implement a new Strategy instance and register it with the Factory during the application bootstrap phase.
Data Persistence, Ephemeral Log Partitioning, and Idempotency Semantics
A high-throughput notification system handles two distinct persistence workloads: relational, strongly consistent transactional data (user preferences, opt-outs, provider configs), and append-heavy, high-velocity ephemeral data (delivery receipts, tracking logs, read receipts). Using a single database for both workloads degrades performance under heavy load.
Relational Storage: User Preference Matrix (PostgreSQL)
CREATE TABLE user_notification_preferences (
 user_id UUID NOT NULL,
 channel_type VARCHAR(32) NOT NULL, -- 'PUSH', 'SMS', 'EMAIL'
 category VARCHAR(64) NOT NULL, -- 'TRANSACTIONAL', 'MARKETING', 'SECURITY'
 is_enabled BOOLEAN DEFAULT TRUE NOT NULL,
 quiet_hours_start TIME WITHOUT TIME ZONE NULL,
 quiet_hours_end TIME WITHOUT TIME ZONE NULL,
 updated_at TIMESTAMP WITH TIME ZONE DEFAULT CURRENT_TIMESTAMP NOT NULL,
 PRIMARY KEY (user_id, channel_type, category)
);

CREATE INDEX idx_user_channel_lookup
ON user_notification_preferences (user_id, is_enabled);
High-Volume Delivery Logs (Apache Cassandra / ScyllaDB)
Delivery receipts generate massive write workloads. Cassandra or ScyllaDB provides horizontally scalable writes partitioned by recipient and time bucketing, allowing deterministic write paths and zero-cost time-to-live (TTL) cleanups.
CREATE KEYSPACE notification_logs
WITH replication = {'class': 'NetworkTopologyStrategy', 'us-east': 3, 'eu-central': 3};

CREATE TABLE notification_logs.deliveries_by_recipient (
 recipient_id uuid,
 bucket_month text, -- Format: YYYY-MM (prevents unbound partition size)
 created_at timestamp,
 notification_id uuid,
 channel_type text,
 template_id text,
 status text, -- 'ENQUEUED', 'DISPATCHED', 'DELIVERED', 'FAILED', 'BOUNCED'
 error_payload text,
 provider_reference_id text,
 PRIMARY KEY ((recipient_id, bucket_month), created_at, notification_id)
) WITH CLUSTERING ORDER BY (created_at DESC, notification_id ASC)
AND default_time_to_live = 7776000; -- 90-day automatic physical TTL eviction
Atomic Distributed Idempotency via Redis
To avoid sending duplicate notifications, workers must enforce distributed idempotency. At-least-once message queues often redeliver messages during network blips or worker node restarts. Downstream vendors (especially SMS aggregators) bill on every API call and deliver messages directly to end-user devices, making duplicate suppression critical.
import { Redis } from "ioredis";

export class IdempotencyEnforcer {
 private redis: Redis;

 constructor(redisClient: Redis) {
 this.redis = redisClient;
 }

 /**
 * Attempts to claim processing rights on an idempotency key.
 * Returns true if the key is acquired, false if it is a duplicate.
 */
 async acquireLease(idempotencyKey: string, ttlSeconds: number = 86400): Promise<boolean> {
 const namespacedKey = `idemp:${idempotencyKey}`;
 // Atomic SET if Not Exists (NX) with explicit time-to-live expiration
 const status = await this.redis.set(namespacedKey, "LOCKED", "EX", ttlSeconds, "NX");
 return status === "OK";
 }

 async markSuccess(idempotencyKey: string, providerResponse: string, ttlSeconds: number = 86400): Promise<void> {
 const namespacedKey = `idemp:${idempotencyKey}`;
 await this.redis.set(namespacedKey, providerResponse, "EX", ttlSeconds);
 }

 async releaseLock(idempotencyKey: string): Promise<void> {
 const namespacedKey = `idemp:${idempotencyKey}`;
 await this.redis.del(namespacedKey);
 }
}
Handling Vendor Outages with Circuit Breakers and Fallback Routing
External delivery partners inevitably experience transient degradation, connection dropouts, and multi-hour infrastructure outages. Directly tying internal delivery guarantees to an external upstream API exposes the entire architecture to cascading thread pool exhaustion.
Circuit Breaker State Machine Mechanics
Using a distributed state machine modeled after Netflix Hystrix or Resilience4j, the notification engine tracks vendor availability across rolling temporal windows. If a vendor’s error rate exceeds configured thresholds, the circuit breaker opens, automatically rerouting outbound messages to a secondary provider.
- Closed State: Requests pass directly to the primary vendor (e.g. Twilio). Telemetry monitors successful deliveries, vendor status codes (e.g.
429 Too Many Requests,503 Service Unavailable), and network timeouts within a rolling 60-second window. - Tripping the Circuit (Open State): If the error rate surpasses 5% or 3 consecutive network timeouts occur, the breaker transitions to Open. All outbound traffic routes instantly to the secondary vendor (e.g. AWS SNS / Sinch) without waiting for timeouts.
- Half-Open Probing: After a defined cooling period (e.g. 30 seconds), the circuit enters Half-Open. A fractional percentage of baseline traffic (e.g. 2% of egress) is directed to the primary vendor. If these canary probes succeed without error, the circuit resets to Closed; if any canary fails, the circuit switches back to Open.
Failure Boundary: Treat 4xx client errors (such as
InvalidPhoneNumberorTokenExpired) as terminal business failures, not provider outages. Tripping circuit breakers on bad user input causes false-positive failovers across all system vendors.
Dead Letter Queue (DLQ) Topology and Secondary Routing
When both primary and secondary vendor channels fail, messages must not be dropped. Instead, they route to a resilient retry tier structured around progressive backoff queues.
| Queue / Tier Name | Retention & Backoff | Storage Engine | Resolution Action |
|---|---|---|---|
| Immediate Channel Queue | 0s delay (active processing) | Kafka Partition / RabbitMQ | Initial dispatch attempt to primary provider. |
| Secondary Retry Queue | Exponential delay (2^n * 1000ms) | Delayed Message Broker / Redis ZSet | Failover attempt to secondary provider. |
| Terminal Dead Letter Queue | 14-day persistent retention | AWS SQS DLQ / ScyllaDB | Manual operational triage, root-cause analysis, batch re-injection. |
Sliding Window Aggregation, Digest Engines, and Per-Tenant Rate Limiting
A high-volume event publisher (such as a social network, collaborative SaaS workspace, or market exchange) can quickly overwhelm users with notifications. Sending individual alerts for every like, comment, or share creates notification fatigue and leads to app uninstalls. A production notification platform must include an aggregation and rate-limiting tier to prevent delivery storms.
Sliding Window Digest Aggregator
Rather than dispatching an event immediately, the system holds aggregation-eligible notifications inside a distributed sliding-window buffer. If multiple events occur within the aggregation window (e.g. 10 minutes), they are combined into a single digest message (such as: “Jane Doe and 4 others liked your post”).
import { Redis } from "ioredis";

export class NotificationAggregator {
 private redis: Redis;

 constructor(redisClient: Redis) {
 this.redis = redisClient;
 }

 /**
 * Adds an event to the user's aggregation buffer.
 * Returns true if an aggregation job is already pending, false if this is the first event.
 */
 async bufferNotification(
 userId: string,
 aggregationKey: string,
 eventPayload: string,
 windowSeconds: number
 ): Promise<boolean> {
 const listKey = `agg:buffer:${userId}:${aggregationKey}`;
 const lockKey = `agg:lock:${userId}:${aggregationKey}`;

 // Append event data to the user buffer list
 await this.redis.rpush(listKey, eventPayload);

 // Set lease window only if it is the first event in the series
 const acquired = await this.redis.set(lockKey, "ACTIVE", "EX", windowSeconds, "NX");

 if (acquired === "OK") {
 // This is the initial trigger event; schedule the aggregation flush job
 return false;
 }

 // An aggregation buffer timer is already active
 return true;
 }

 /**
 * Flushes the buffer after window expiration and compiles the digest payload.
 */
 async flushBuffer(userId: string, aggregationKey: string): Promise<string[]> {
 const listKey = `agg:buffer:${userId}:${aggregationKey}`;
 const lockKey = `agg:lock:${userId}:${aggregationKey}`;

 // Atomic fetch and clean
 const pipeline = this.redis.pipeline();
 pipeline.lrange(listKey, 0, -1);
 pipeline.del(listKey);
 pipeline.del(lockKey);

 const results = await pipeline.exec();
 const rawEvents: string[] = (results? results[0][1]: []) as string[];
 return rawEvents;
 }
}
Per-User and Per-Tenant Token Bucket Limiting
To guard against noisy neighbors and broken event loops, the system enforces multi-tiered rate limits via an atomic Token Bucket algorithm backed by Redis Lua scripts.
- Tenant Tier Limit: Maximum 5,000 dispatches per second per enterprise tenant to preserve global queue processing availability.
- User Tier Limit: Maximum 3 push notifications per 60 seconds per individual recipient, silently dropping or queueing promotional noise while letting security OTPs through unhindered.
- Channel Quotas: Explicit daily limits per user on SMS channels to avoid unexpected telecom charges.
Production Rate Limiting Checklist
- Enforce strict isolation between transactional and marketing rate limit buckets.
- Configure rate-limiter scripts to return exact
Retry-Afterheaders in ingestion API responses. - Run rate-limiting Redis nodes in in-memory clusters with local in-process caches for hot tenant keys.
- Emit rate-limit metrics directly to operational dashboards to catch misconfigured event loops early.
Frequently Asked Questions
How do you achieve idempotency when you design a notification system?
To enforce idempotency, generate a deterministic hash from the event ID, recipient ID, and message type. Ingestion workers verify this key against a distributed cache like Redis with a 24-hour TTL using atomic SETNX operations before enqueuing to prevent duplicate deliveries.
What core design patterns are required in notification service LLD?
Production notification service LLD relies heavily on the Strategy Pattern to decouple heterogeneous delivery protocols, the Factory Pattern to instantiate channel-specific payloads dynamically, and the Observer Pattern to subscribe downstream worker pools to upstream business domain events without tight coupling.
How should message queues be partitioned in notification service system design?
In notification service system design, decouple queues by channel type (push, SMS, email) and priority tier (transactional OTP versus promotional marketing). This prevents bulk marketing campaigns from exhausting worker thread pools and delaying critical verification codes or security alerts.
How do you handle third-party delivery provider rate limits and downtime?
Implement circuit breakers with secondary vendor failover paths, such as routing from Twilio to AWS SNS when error rates exceed five percent. Pair this with dead-letter queues and leaky-bucket client rate limiters tuned strictly to vendor contract thresholds.
Designing a robust, enterprise-grade notification platform requires moving beyond basic queue setups and simple provider APIs. By decoupling high-throughput ingestion from channel-specific delivery workers, separating transactional traffic from bulk marketing campaigns, and applying robust behavioral design patterns, you can build a resilient messaging pipeline that scales smoothly past hundreds of millions of daily deliveries.
A resilient system must handle failure at every layer. By pairing distributed idempotency keys and multi-tiered persistence with circuit-breaker failovers and digest aggregators, you can protect downstream services, control delivery costs, and reliably hit sub-second SLAs under heavy traffic.