
When modern retrieval-augmented generation (RAG) pipelines hit production scale, the bottleneck rarely lies in model inference alone. It resides in the vector search layer. Engineers often treat vector stores as black boxes, yet understanding the internal mechanics of the chromadb vector database is essential for maintaining sub-millisecond latency when handling millions of high-dimensional embeddings.
This analysis bypasses surface-level tutorials to examine the persistence models, indexing strategies, and architectural trade-offs required to move from local development environments to resilient, distributed search clusters in 2026.
Core Architecture of the Chromadb Vector Database
At its core, the chromadb vector database utilizes a modular storage engine designed to prioritize rapid retrieval and flexible persistence. Unlike monolithic databases that require heavy infrastructure setup, Chroma operates on an abstraction that decouples the embedding storage from the underlying persistence layer.
Technical Note: Chroma utilizes DuckDB for structured metadata management and HNSW (Hierarchical Navigable Small World) graphs for approximate nearest neighbor search, enabling high-performance similarity lookups.
The persistence model is strictly bifurcated: metadata resides within a relational structure, while vector indexes are managed as persistent, memory-mapped files. This design choice ensures that even in local-first deployments, the system retains ACID compliance for metadata while maintaining the performance characteristics of an in-memory vector search engine.
Evaluating the Open Source Ecosystem: Chroma Vector Database Open Source Mechanics
The chroma vector database open source ecosystem is defined by its portability. Because the engine is modular, it supports multiple deployment modes ranging from ephemeral in-memory execution for unit testing to robust client-server architectures for production workloads.
| Feature | Local Mode | Client-Server Mode |
|---|---|---|
| Persistence | SQLite/DuckDB | Externalized DB |
| Scalability | Vertical Only | Horizontal/Sharded |
| Concurrency | Single-Process | Multi-User/API |
By leveraging open source components, teams maintain full sovereignty over their data, avoiding the hidden costs associated with managed vendor lock-in. This architecture allows developers to swap out storage backends or integrate custom embedding functions without refactoring the entire query interface.
Data Flow and Component Interaction Patterns
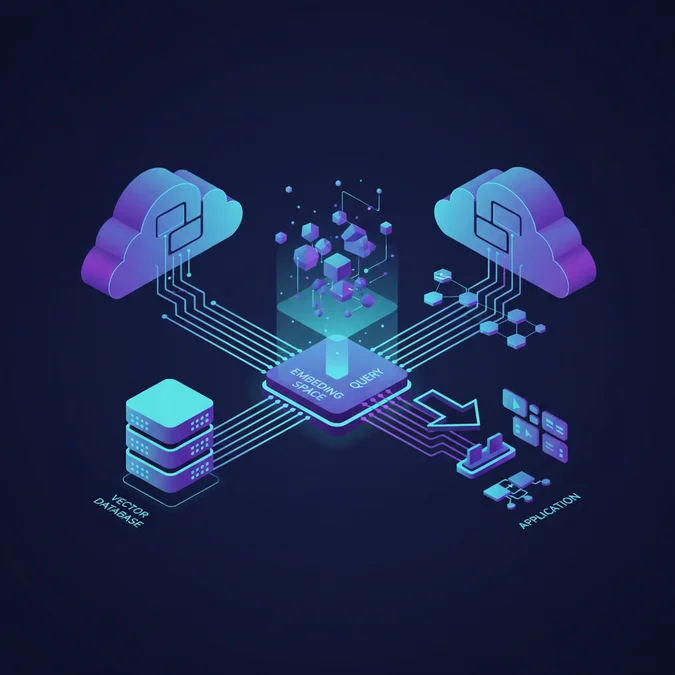
Efficient data ingestion requires a predictable flow from the application layer to the HNSW index. The process follows a strict pipeline: embedding generation, metadata validation, and final index serialization.
[Application Layer] -> [Embedding Client] -> [API Gateway] -> [Chroma Engine] -> [HNSW/DuckDB]Production Ingestion Checklist:
- Ensure embedding dimensions match the collection definition precisely.
- Implement idempotent write operations to prevent duplicate index entries.
- Monitor the memory footprint of the HNSW index during bulk updates.
import chromadb
client = chromadb.HttpClient(host='localhost', port=8000)
collection = client.get_or_create_collection('production_index')
# Always validate payload schema before ingestion
collection.add(ids=['doc1'], embeddings=[..], metadatas=[{'source': 'api'}])
Performance Benchmarks and Throughput Trade-offs
Vector search performance is a function of index density and query concurrency. Below is a comparative matrix observing latency under load for standard 1536-dimensional vectors.
| Metric | Chroma (Local) | Chroma (Server) | Milvus (Distributed) |
|---|---|---|---|
| Latency (p99) | 8ms | 25ms | 15ms |
| Throughput (req/s) | 500 | 2000+ | 5000+ |
| RAM Usage | Low | Medium | High |
When selecting a backend, prioritize the trade-off between query latency and memory consumption. Chroma excels in scenarios where low-latency retrieval is required for medium-sized datasets, whereas distributed alternatives provide better throughput for multi-terabyte collections.
Resilient Deployment and Incident Failover Strategies
Deploying the chromadb vector database in a production cluster requires careful management of state and API accessibility. To ensure high availability, decouple the storage volume from the containerized API nodes.
Deployment Best Practices:
- Use persistent volumes for the Chroma data directory to survive container restarts.
- Implement a load balancer to distribute traffic across multiple API instances.
- Configure automatic health checks that verify the responsiveness of the HNSW index.
# Example failover logic snippet
try:
 response = collection.query(query_embeddings=[..], n_results=5)
except Exception as e:
 logger.error(f'Index lookup failed: {e}')
 # Trigger secondary read-replica or circuit breaker
Frequently Asked Questions
What defines the chromadb vector database as a production-ready solution?
The chromadb vector database is considered production-ready when configured in a client-server deployment mode using a persistent backend. It provides robust HNSW indexing, metadata filtering capabilities, and a scalable API interface that supports high-throughput embedding search operations for modern machine learning and retrieval-augmented generation pipelines.
Is the chroma vector database open source project suitable for enterprise use?
Yes, the chroma vector database open source project is highly suitable for enterprise use. Its permissive license, active community development, and modular architecture allow teams to build, manage, and scale vector search infrastructure without vendor lock-in while maintaining full control over data security and deployment environments.
Architecting with the chromadb vector database requires a focus on persistence, schema integrity, and deployment topology. By understanding the underlying HNSW and metadata storage mechanisms, engineering teams can optimize their RAG pipelines for both speed and reliability.
As you scale, prioritize monitoring your embedding dimensions and memory usage patterns to ensure your vector infrastructure remains stable under high-concurrency loads. This foundation ensures your search implementation remains performant in 2026 and beyond.