
An unhandled null response from an enterprise inventory microservice leaves a standard conversational assistant frozen, waiting for user guidance. In contrast, an agentive AI system detects the anomaly, cross-references an alternate warehouse ledger, verifies transit route margins against vendor SLAs, executes a fallback purchase order, and alerts downstream logistics before human operators even log into their dashboards.
Agentive AI represents a distinct architectural shift from passive conversational models to autonomous software entities. Rather than generating completions bounded by single prompts, an agentive system maintains state, perceives dynamic environmental changes, breaks down open-ended objectives into deterministic directed acyclic graphs (DAGs), and interacts with external tools through structured execution loops. In enterprise runtimes, this transition elevates the underlying large language model from an interactive text engine to a probabilistic reasoning unit embedded within a deterministic operating framework.
Engineering teams deploying these systems face critical operational constraints: cascading non-deterministic errors, token consumption spikes, state drift across long horizons, and unconstrained recursion. This architecture reference deconstructs the structural anatomy of agentive AI, contrasting its operational execution model with retrieval-augmented generation and assistive copilots, while establishing production standards for state persistence, guardrail enforcement, and inference economics.
Deconstructing the Agentive AI Meaning and Core System Mechanics
To comprehend the agentive AI meaning, systems architects must separate agency from basic generative capability. Generative AI maps inputs to probabilistic distributions over token sequences. While powerful, this mechanism is fundamentally reactive and stateless: it produces an output and immediately terminates its execution context. Conversely, agentive AI systems are continuous control loops that observe environmental states, deliberate over desired outcomes, formulate multi-step plans, and invoke external actuators or APIs to effect state changes in surrounding enterprise systems.
The distinction between assistive systems, classic robotic process automation (RPA), and true agentive AI lies in cognitive autonomy and adaptability. RPA delivers high determinism but collapses when inputs diverge from brittle if-this-then-that scripts. Assistive copilots augment human actions but rely on the user to serve as the runtime control loop, determining sequence, validation, and recovery. Agentive AI occupies the autonomous operational quadrant: it formulates execution paths dynamically when faced with novel states, validates intermediate outputs against schema contracts, and self-corrects upon encountering runtime exceptions.
Architectural Definition: The agentive AI meaning centers on closed-loop, goal-directed computation. An agentive system couples a probabilistic reasoning engine (such as an LLM or SLM) with explicit working memory, a deterministic execution sandbox, external environment telemetry, and a graph-based state machine capable of autonomous progression toward an end state.
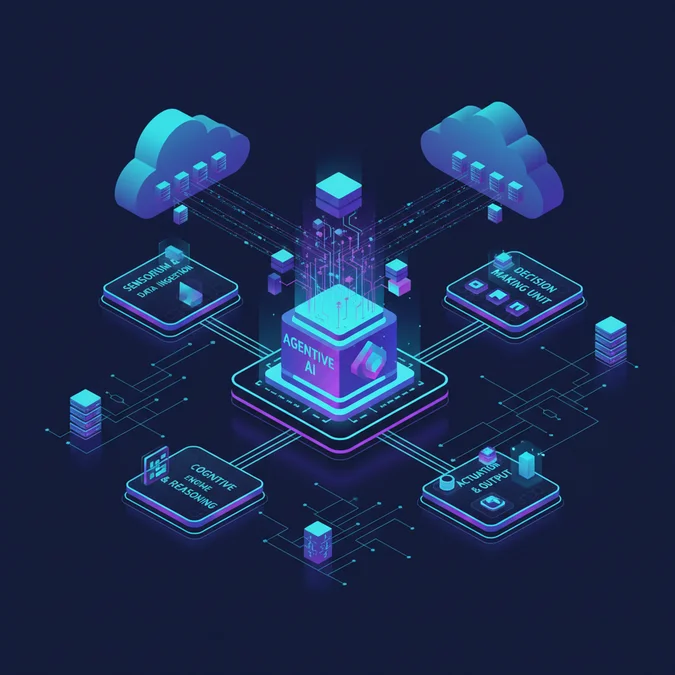
At the mechanical level, an agentive system relies on four decoupled planes:
- The Perception Plane: Ingests structured and unstructured inputs, including webhook notifications, API responses, database change data capture (CDC) streams, and human feedback, converting them into standardized observations.
- The Cognition and Planning Plane: Evaluates the delta between the current environmental state and the target objective. It constructs a plan of action, routes subtasks to specialized foundational models, and enforces decomposition logic.
- The Execution Plane: Interacts deterministically with external environments. It manages authenticated tool runs, validates JSON schemas, and manages write-ahead transactional logs.
- The Memory and State Plane: Persists execution histories, intermediate scratchpads, and vector-indexed episodic experiences across distributed storage engines.
Architectural Taxonomy: Assistive vs Generative vs Agentive AI Systems
Designing enterprise architectures requires clear boundaries between assistive copilots, retrieval-augmented generation (RAG) pipelines, and true agentive AI runtimes. Confusing these architectural layers leads to fragile implementations, runaway cloud expenditures, and dangerous permission escalations.
Standard retrieval-augmented generation augments a single inference pass with semantically matched vector embeddings. While this provides contextual grounding, the execution topology remains strictly linear: input query goes to retriever, retriever feeds context to generator, and generator outputs text to the client. The system has no capacity to probe whether the retrieved data was sufficient, correct its strategy if the context yields contradictions, or take downstream action in an enterprise database.
Agentive AI redefines this paradigm by placing retrieval, tool execution, and code synthesis inside an iterative evaluation graph. The runtime maintains an explicit state machine that transitions based on real-time observations, maintaining transactional boundaries and fallback alternatives at every node.
| System Architecture | Autonomy Level | Execution Loop | State & Memory | External Mutation | Primary Failure Mode |
|---|---|---|---|---|---|
| Generative Completion | Zero (Passive) | Single forward pass | Stateless (Ephemerally bounded by context window) | Read-only (No tool integration) | Factual hallucination |
| Standard RAG Pipeline | Low (Reactive) | Deterministic linear pipeline (Retrieve-Augment-Generate) | Static vector store retrieval per query | Read-only (Query-time embeddings) | Context pollution, retrieval mismatch |
| Assistive Copilot | Moderate (Human-in-the-loop) | User-driven prompt/response cycles | Session-based thread memory | Human-approved external triggers | User cognitive overload, dropped intent |
| Agentive AI System | High (Proactive / Autonomous) | Iterative state machine (Perceive-Plan-Act-Verify) | Dynamic checkpoints, episodic memory, short-term scratchpad | Direct, autonomous API mutations with guardrails | Infinite recursion, state drift, cascading tool failures |
In practice, modern enterprise systems rarely operate as pure implementations of a single category. Instead, production architectures deploy agentive AI as the orchestrator over specialized RAG pipelines and deterministic services, allowing the agent to dynamically determine when information retrieval is mandatory before dispatching state-altering commands.
Perception-Action Loops: Dissecting ReAct, Plan-and-Solve, and ReWOO
The execution topology of an agentive AI framework dictates how it handles environmental uncertainty, token latency, and error propagation. Three foundational execution patterns dominate production architectures: ReAct (Reasoning and Acting), Plan-and-Solve, and ReWOO (Reasoning Without Observation).
The classic ReAct loop couples token generation with immediate tool execution in a tight, sequential cadence: Thought -> Action -> Observation -> Thought. While ReAct excels at exploratory tasks where each step depends entirely on dynamic feedback from the preceding step, it incurs severe latency penalties. Every external API invocation forces the system to pause inference, execute network I/O, append the observation to the context window, and trigger a new full-context inference request. For complex workflows involving 10 or more steps, token usage scales quadratically and latency frequently exceeds acceptable service level objectives.
+-----------------------------------------------------------------+ | ReAct Sequential Execution | +-----------------------------------------------------------------+ [User Intent] | v +------------+ +------------+ +-------------+ +------------+ | Thought 1 |--->| Action 1 |--->| Observation |--->| Thought 2 |---> [Result] +------------+ +------------+ +-------------+ +------------+ (API Call I/O) (Re-Inference) +-----------------------------------------------------------------+ | ReWOO Decoupled DAG Execution | +-----------------------------------------------------------------+ [User Intent] | v +--------------------+ | Planner Engine | (Single LLM Call generates full execution DAG) +--------------------+ | +------------------------+------------------------+ | | | v v v +---------------+ +---------------+ +---------------+ | Tool Worker A | | Tool Worker B | | Tool Worker C | (Parallel API) (Parallel API) (Parallel API) | | | +------------------------+------------------------+ | v +--------------------+ | Solver Engine | (Single LLM Call synthesizes final response) +--------------------+ | v [Terminal State]To mitigate the serialization bottlenecks of ReAct, the Plan-and-Solve pattern decouples architectural planning from execution. An orchestrator model decomposes the macro objective into an upfront execution graph. Individual workers then execute the plan steps sequentially or in parallel. However, if an intermediate step fails or yields unexpected results, the entire downstream plan must be recalculated via an explicit replanning node, introducing computational thrashing if the environment is highly volatile.
The ReWOO (Reasoning Without Observation) paradigm optimizes operational efficiency and inference costs by eliminating intermediate reasoning tokens entirely. The planner synthesizes a complete blueprint comprising variable tokens (such as #E1, #E2) representing expected tool outputs. The orchestration runtime executes all non-dependent external tools concurrently using standard worker pools, substituting the resolved tool outputs into the variable placeholders. Finally, a compact solver model evaluates the aggregated observations in a single inference pass. In benchmarks across deterministic enterprise workflows, ReWOO reduces token overhead by up to 64% and cuts end-to-end latency by half compared to iterative ReAct loops.
Architectural Heuristic: Deploy ReAct when the solution space is non-deterministic, exploratory, and requires continuous environmental probing (such as incident triage or live database debugging). Deploy ReWOO or Plan-and-Solve when tasks have predictable data dependencies (such as customer onboarding, multi-system reconciliation, or static document underwriting).
Building a Stateful Agent Runtime with Deterministic Tool Validation
A production agentive AI runtime cannot rely on unstructured string parsing or open-ended prompting. Enterprise environments demand deterministic schema enforcement, state rollbacks, and persistent execution checkpoints to survive container evictions, network timeouts, and model regressions. Implementing this architecture requires a state-graph orchestrator paired with typed data validation models.
The following production-ready implementation integrates LangGraph with Pydantic to build an enterprise order remediation runtime. It demonstrates typed state handling, schema-enforced tool execution, deterministic conditional routing, and transaction failure management.
import operator from typing import Annotated, Dict, List, Literal, Optional, TypedDict from pydantic import BaseModel, Field, ValidationError from langgraph.graph import StateGraph, END from langgraph.checkpoint.memory import MemorySaver # --- Deterministic Tool Validation Schemas --- class InventoryItemQuery(BaseModel): sku: str = Field(.. regex="^[A-Z]{3}-[0-9]{4}$", description="SKU format: AAA-0000") warehouse_id: str = Field(.. min_length=4, max_length=12) class OrderRemediationAction(BaseModel): order_id: str = Field(.. description="Target enterprise order ID") action: Literal["REROUTE", "CANCEL", "ESCALATE"] target_warehouse_id: Optional[str] = None remediation_reason: str = Field(.. max_length=250) # --- Enterprise Agent State Definition --- class AgentState(TypedDict): order_id: str sku: str primary_warehouse: str fallback_warehouse: str inventory_available: Optional[int] remediation_strategy: Optional[OrderRemediationAction] execution_history: Annotated[List[str], operator.add] retry_count: Annotated[int, operator.add] status: Literal["RUNNING", "SUCCESS", "FAILED", "HUMAN_REVIEW"] # --- Mock Tool Execution Layer --- def check_inventory_service(sku: str, warehouse_id: str) -> int: # Deterministic simulation: primary warehouse is depleted, fallback has stock if warehouse_id == "WH-PRIMARY": return 0 elif warehouse_id == "WH-BACKUP": return 45 raise ConnectionError("Inventory service timeout") # --- Graph Node Implementations --- def verify_inventory_node(state: AgentState) -> Dict: sku = state["sku"] warehouse = state["primary_warehouse"] try: # Enforce runtime parameter validation via Pydantic valid_query = InventoryItemQuery(sku=sku, warehouse_id=warehouse) count = check_inventory_service(valid_query.sku, valid_query.warehouse_id) return { "inventory_available": count, "execution_history": [f"Checked inventory at {warehouse}: {count} units found."] } except (ValidationError, ConnectionError) as err: return { "inventory_available": -1, "execution_history": [f"Inventory probe failed: {str(err)}"], "status": "FAILED" } def plan_remediation_node(state: AgentState) -> Dict: # Deterministic decision branch based on verified state observations if state.get("inventory_available", 0) > 0: action = OrderRemediationAction( order_id=state["order_id"], action="REROUTE", target_warehouse_id=state["primary_warehouse"], remediation_reason="Stock confirmed at primary location." ) else: action = OrderRemediationAction( order_id=state["order_id"], action="REROUTE", target_warehouse_id=state["fallback_warehouse"], remediation_reason="Primary stock depleted. Automatic failover routed to secondary facility." ) return { "remediation_strategy": action, "execution_history": [f"Formulated strategy: {action.action} to {action.target_warehouse_id}"] } def execute_remediation_node(state: AgentState) -> Dict: strategy = state.get("remediation_strategy") if not strategy: return {"status": "FAILED", "execution_history": ["Missing remediation strategy."]} # Execute mutation through verified schemas if strategy.action == "REROUTE" and strategy.target_warehouse_id: # Simulate persistent ERP mutation return { "status": "SUCCESS", "execution_history": [f"Successfully mutated Order {strategy.order_id} to {strategy.target_warehouse_id}."] } return {"status": "HUMAN_REVIEW", "execution_history": ["Action requires managerial approval."]} # --- Conditional Routing Logic --- def route_after_inventory_check(state: AgentState) -> Literal["plan_remediation", "handle_failure"]: if state.get("inventory_available", -1) >= 0: return "plan_remediation" return "handle_failure" def handle_failure_node(state: AgentState) -> Dict: return { "status": "HUMAN_REVIEW", "execution_history": ["Unrecoverable error encountered. Escalated to manual operational triage."] } # --- Workflow Graph Construction --- builder = StateGraph(AgentState) builder.add_node("verify_inventory", verify_inventory_node) builder.add_node("plan_remediation", plan_remediation_node) builder.add_node("execute_remediation", execute_remediation_node) builder.add_node("handle_failure", handle_failure_node) builder.set_entry_point("verify_inventory") builder.add_conditional_edges( "verify_inventory", route_after_inventory_check, { "plan_remediation": "plan_remediation", "handle_failure": "handle_failure" } ) builder.add_edge("plan_remediation", "execute_remediation") builder.add_edge("execute_remediation", END) builder.add_edge("handle_failure", END) # Compile the runtime with an in-memory checkpointer for state isolation checkpointer = MemorySaver() agent_runtime = builder.compile(checkpointer=checkpointer) # Execution example config = {"configurable": {"thread_id": "tx-80492-session"}} initial_payload: AgentState = { "order_id": "ORD-99214", "sku": "LOG-4091", "primary_warehouse": "WH-PRIMARY", "fallback_warehouse": "WH-BACKUP", "inventory_available": None, "remediation_strategy": None, "execution_history": [], "retry_count": 0, "status": "RUNNING" } output = agent_runtime.invoke(initial_payload, config=config) print("Final Execution State:", output["status"]) print("Audit Trail:", output["execution_history"])In this architecture, the state is immutable and versioned across execution steps. If a downstream infrastructure service drops during execute_remediation, the runtime can rollback state to the plan_remediation checkpoint without re-querying the upstream inventory services. This checkpointing paradigm isolates failures, preserves token budgets, and ensures strict adherence to transactional integrity constraints.
Enterprise Failure Modes: State Drift, Hallucinated Tool Calls, and Infinite Loops
When deploying agentive AI into core enterprise workflows, architectures face failure profiles fundamentally different from those of standard stateless microservices. Non-deterministic tool selection, circular reasoning paths, and cumulative state drift present severe operational threats that require defensive engineering patterns.
The most pervasive enterprise vulnerability is infinite recursive looping. This occurs when an agentive AI receives an error or unexpected output from an external tool, reasons that it must try again, and invokes the identical tool with identical or slightly mutated arguments ad infinitum. In production, this behavior quickly exhausts API rate limits and generates catastrophic cloud inference bills within minutes.
Another common breakdown is state drift. As an agent proceeds through long execution chains, its context window fills with intermediate observations, partial completions, stack traces, and tool schemas. This context bloat increases semantic noise, diluting the original user objective. Over time, the foundational reasoning engine begins hallucinating non-existent parameters, mixing up entity IDs, or executing actions that contradict enterprise policies established in the initial system instructions.
To safeguard enterprise environments, architectures must enforce structured guardrails before permitting autonomous state mutations:
- Deterministic Cycle Breakers: Maintain an in-memory hash of the last
Nactions, tool payloads, and resulting observations. If an agent attempts to execute the identical tool call with parameters that match a prior failure state within the same thread, intercept execution immediately and trigger an explicit replanning or failure node. - Strict Hard Recursion and Token Ceilings: Every execution thread must carry non-bypassable constraints: a maximum step limit (e.g.
max_steps = 15) and a strict token consumption quota. Once exhausted, the runtime must suspend execution and transition the transaction to a degraded or manual review state. - Pre-Execution Schema Interceptors: Isolate foundational models from direct API invocation. Pass all model-generated tool arguments through typed validation layers (such as Pydantic or Zod) to assert parameter formatting, bounds, and entity existence before dispatching network packets.
- Human-in-the-Loop Interruption Gates: For state-altering mutations exceeding predefined operational risk thresholds (such as issuing financial refunds, deleting customer records, or applying database migrations), configure interrupt points in the state graph. The runtime suspends execution, serializes current thread state to persistent storage, and awaits cryptographically signed authorization from an authorized human operator before continuing execution.
- Semantic Diff Assertions: Measure verifiable state progress between iterations. If an agent completes a reasoning step without generating a measurable change in system state (e.g. retrieving novel facts or mutating target records), decrease the remaining execution budget exponentially.
Inference Economics and Latency Optimization in Multi-Agent Workflows
Deploying autonomous agentive AI workflows at enterprise scale without optimization results in severe cost inefficiency and unacceptable latency profiles. Because every step within an autonomous loop requires context ingestion, prompt formatting, model inference, and tool execution, costs and latency accumulate linearly or quadratically relative to plan depth.
To maintain financial and operational viability, architectures must move away from homogeneous model deployment, where a flagship reasoning model handles every phase of the loop. Instead, enterprise systems adopt speculative token routing and model tiering: routing orchestration, schema validation, and simple deterministic tool calls to specialized Small Language Models (SLMs) running locally or on edge inference nodes, reserving frontier reasoning models strictly for high-ambiguity planning, evaluation, and recovery decisions.
| Operational Node Type | Model Architecture Tier | Average Latency | Input / Output Cost Multiplier | Recommended Enterprise Role |
|---|---|---|---|---|
| Orchestrator / Macro-Planner | Frontier LLM (e.g. Claude 3.5 Sonnet, GPT-4o) | 1200 – 2500 ms | 10.0x (Baseline High) | Initial goal decomposition, DAG synthesis, exception handling |
| Deterministic Tool Invoker | Fine-tuned SLM (e.g. Llama 3.1 8B, Mistral 7B) | 80 – 220 ms | 0.15x – 0.3x | Pydantic payload extraction, parameter mapping, API calling |
| Context Compression / Reducer | Distilled Utility SLM or Embeddings | 40 – 150 ms | 0.05x – 0.1x | Scratchpad summarization, observation deduplication |
| Validation & Guardrail Checker | Rule-based deterministic engine + SLM | 15 – 90 ms | 0.01x – 0.08x | Policy assertions, schema validation, regex verification |
Beyond model tiering, systems architects must employ continuous context compression techniques. As the perception-action loop accumulates observations, the agent runtime should execute state reduction passes, stripping raw JSON payloads of unneeded fields and maintaining only high-signal semantic diffs. This practice keeps context windows clean, minimizes token processing costs, and directly counteracts state drift.
Cost-Per-Step Economic Formula: Enterprise teams should model end-to-end operational agent cost using:Total Cost = C_planning + Sum_{i=1}^{N}(C_inference(i) + C_tool_io(i)) + C_evaluation
Optimizing multi-agent workflows requires minimizing N (loop depth) through parallel tool execution while driving down C_inference on non-critical nodes using SLM delegation.
Additionally, production runtimes leverage speculative parallel tool calling. When a planning node identifies independent actions within an execution DAG, the runtime fires asynchronous network requests across multiple worker threads simultaneously rather than waiting for serialized roundtrips. Combining parallelization with deterministic semantic caching for read-only tools cuts median execution latency by up to 70% in distributed enterprise environments.
Frequently Asked Questions
What is the core agentive ai meaning in enterprise engineering?
Agentive AI refers to artificial intelligence architectures designed to operate with independent agency. Unlike passive generative assistants that respond only to single prompts, agentive systems evaluate environmental state, formulate sequential plans, invoke external tools, self-correct after runtime errors, and pursue complex objectives with minimal human intervention.
How does agentive AI differ from conversational generative AI?
Conversational generative AI generates static text outputs directly mapped to incoming context windows. Agentive AI utilizes foundational models as reasoning engines within an active control loop, dynamically executing API calls, writing memory across persistence layers, and triggering external workflows until a multi-step objective completes.
What frameworks are standard for building agentive AI platforms in 2026?
In 2026, leading frameworks for agentive systems include LangGraph, PydanticAI, LlamaIndex Workflows, and AutoGen. Production architectures increasingly favor graph-based state machines that enforce strict type checking, deterministic edge transitions, and distributed state persistence over unconstrained agent loops.
How do developers prevent infinite recursive loops in agentive AI?
Engineers mitigate recursive loops by configuring hard recursion limits, maximum token budgets, and deterministic cycle-detection monitors. Implementing state-diff assertions ensures that agents do not execute identical consecutive actions without demonstrating quantifiable progress toward the declared terminal state.
Agentive AI marks a fundamental evolution in software architecture. By coupling foundational reasoning capabilities with stateful execution runtimes, structured schemas, and deterministic validation layers, enterprise teams can transition from passive conversational copilots to resilient, autonomous systems capable of executing mission-critical business objectives.
However, production autonomy demands strict engineering discipline. Uncontrolled agent loops, unvalidated tool calls, and runaway token consumption can rapidly destabilize production systems. Organizations that succeed in scaling agentive AI do so not by eliminating determinism, but by wrapping probabilistic models inside rigorous graph-based state machines, strict execution checkpoints, comprehensive failure-circuit breakers, and clear human oversight boundaries.